Everything in LLMs & Generative AI, page 6
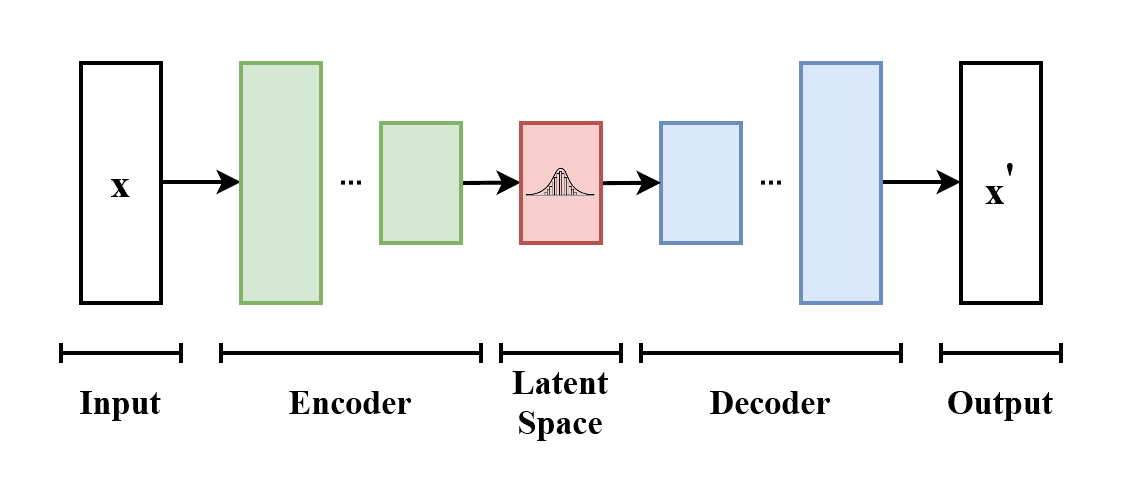
Key latent space difference between Autoencoder and VAE, and generative use
This tests deterministic versus probabilistic latent representations. Standard autoencoders encode fixed points; VAEs encode distributions. Sampling the regularized latent distribution generates new data. Red flag: calling VAEs mere noise adders.
Explain GAN architecture, generator and discriminator roles, and objective function
Tests adversarial training as a minimax game. Strong answers: generator maps noise z to fakes; discriminator classifies real versus fake; both optimize V(D,G)=E[log D(x)]+E[log(1-D(G(z)))].
What fixes an LLM agent's incorrect JSON arguments for a complex tool?
Tests mixing prompting with system guardrails for valid tool JSON. Outline: few-shot demos plus CoT prompting; schema validation, constrained decoding, and retries. Red flag: weak prompts without validation or structured output.

Describe a ReAct agent architecture for multi-step dependent tool calls
Sketch ReAct's thought-action-observation cycle; keep state in an append-only trajectory; re-plan after each observation.
Walk me through building a weather agent with get_weather
Register get_weather, let the model emit parameters, execute it yourself, feed the result back, then synthesize the answer.
How does function calling work in modern LLMs?
Schemas in the prompt; model emits JSON name and arguments; client executes and returns results.
How would you architect a multi-turn conversational RAG system?
This tests memory and query reformulation design beyond single-turn RAG. A strong answer covers 5-10 turn windows, LLM-based rewriting with coreference resolution, hybrid fallbacks, and summarized memory.
Identify RAG latency bottlenecks and propose optimizations
This tests systems thinking across the RAG pipeline. A strong answer names four bottlenecks—embedding, search, chunking, and generation—and pairs each with caching, index tuning, and distillation. Red flag: GPU scaling without indexing fixes.

How would you modify retrieval architecture for hybrid text and SQL RAG?
It tests unified retrieval across unstructured text and structured SQL. Outline a query planner that routes to vector search or text-to-SQL, joins the results, and synthesizes a final answer. Never suggest embedding the whole database as text chunks.

Why does your RAG ignore or contradict retrieved context?
Tests separation of retrieval failures from generation grounding in RAG. Strong answers trace symptoms to root causes like bad chunks, prompt ordering, or parametric knowledge override, then outline systematic debugging. Do not just say hallucination.
Describe a basic RAG architecture and its two main components
This tests retrieval-generation separation. Good answers name the retriever, which fetches relevant documents, and the generator, which synthesizes an answer using those documents plus the query.

What does the KL-divergence penalty do in RLHF PPO, and if zeroed?
It tests RLHF reward hacking awareness. The KL penalty anchors PPO to the reference model to stop mode collapse; zeroing it causes over-optimization against the proxy reward model, yielding incoherent outputs.
What is catastrophic forgetting in LLMs and how do you mitigate it?
This tests stability-plasticity trade-offs in fine-tuning. A strong answer defines catastrophic forgetting as lost prior capabilities, cites LoRA, regularization, and continual learning.
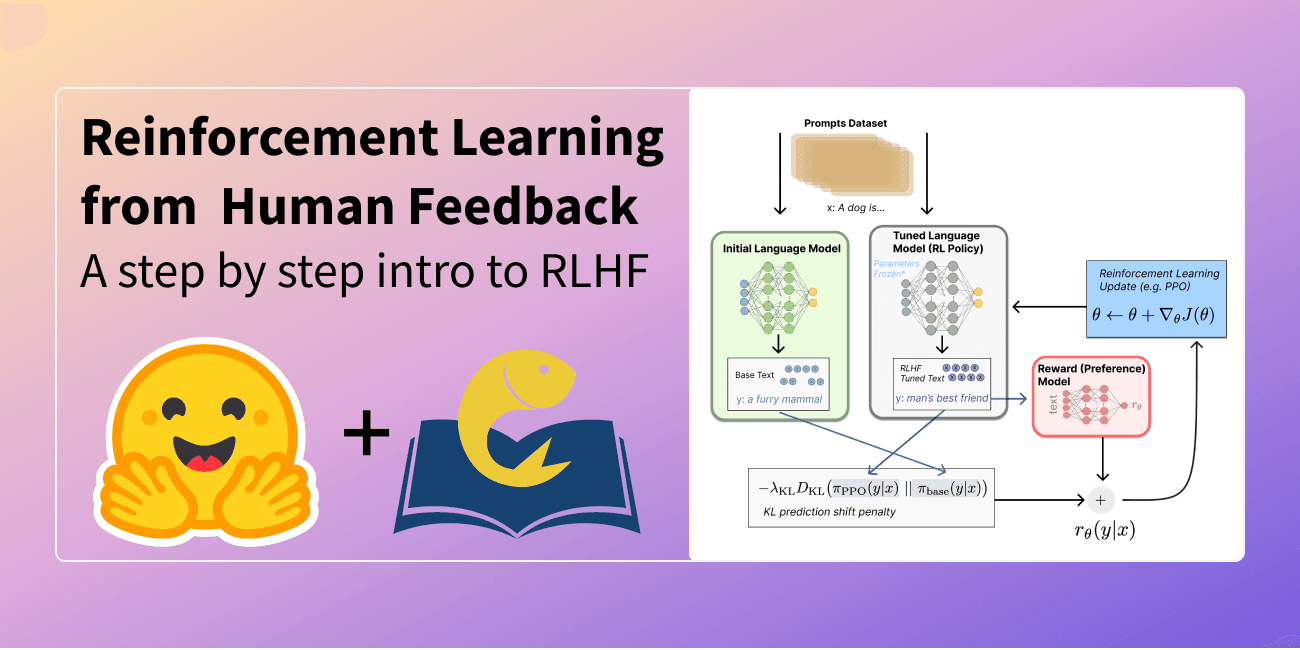
Walk through RLHF's three stages, outputs, and purposes.
Tests your grasp of the RLHF pipeline end-to-end. A strong answer lists: pretrain an instruction-following LM, train a reward model outputting a scalar preference score, then fine-tune the LM via RL.
How does LoRA work and why is it memory-efficient?
LoRA freezes weights and trains A and B so delta-W equals BA, cutting trainable params 10,000x and memory 3x since only A and B get grads.
Full fine-tuning or LoRA on a tight compute budget?
This tests budget-constrained adaptation for many tasks. A strong answer picks LoRA: it trains only a small number of extra parameters, cutting compute and storage versus full fine-tuning while matching performance.
Describe supervised fine-tuning for a pre-trained language model
Tests if you know SFT aligns a base model to instructions using curated prompt-completion data. A strong answer covers next-token prediction on completions, conversational formats, and small learning rates.
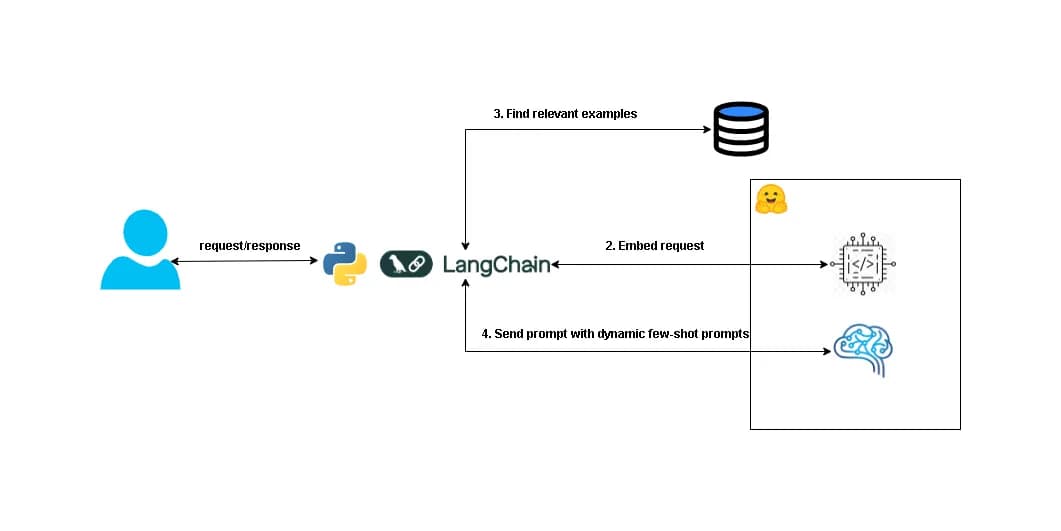
Design dynamic few-shot example retrieval from a vector database
Tests RAG-style prompt engineering with semantic retrieval and latency. Use shared embeddings, approximate nearest neighbors with metadata filters, diversity reranking, and token-bounded prompt templates.

Describe two prompt-based techniques to ensure valid LLM JSON output
This tests output constriction via prompt design. First, embed an exact JSON skeleton with empty values. Second, provide few-shot exemplars mapping inputs to valid JSON. A red flag is suggesting only post-hoc regex repair or larger models.
How do you select in-context examples for text-to-SQL prompts?
What it tests: practical ICL design for structured generation. Answer outline: select examples by SQL syntax similarity plus pattern diversity, order from simple to complex, and anchor schema context. Red flag: claiming random examples work fine.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles