Everything in MLOps & Infrastructure, page 2
Directed Acyclic Graph (DAG) for Workflows
A DAG models a workflow as tasks (nodes) connected by dependency edges with no cycles, so a scheduler knows the valid execution order. It enables parallelism, safe retries, and idempotent reruns, and underpins orchestrators like Airflow for ML pipelines.
Staging Environments for ML Pipelines
A staging environment mirrors production so models and pipelines are validated on production-like data and infrastructure before release. It catches drift, integration breaks, and serving regressions early, making promotion to production a safe, repeatable…
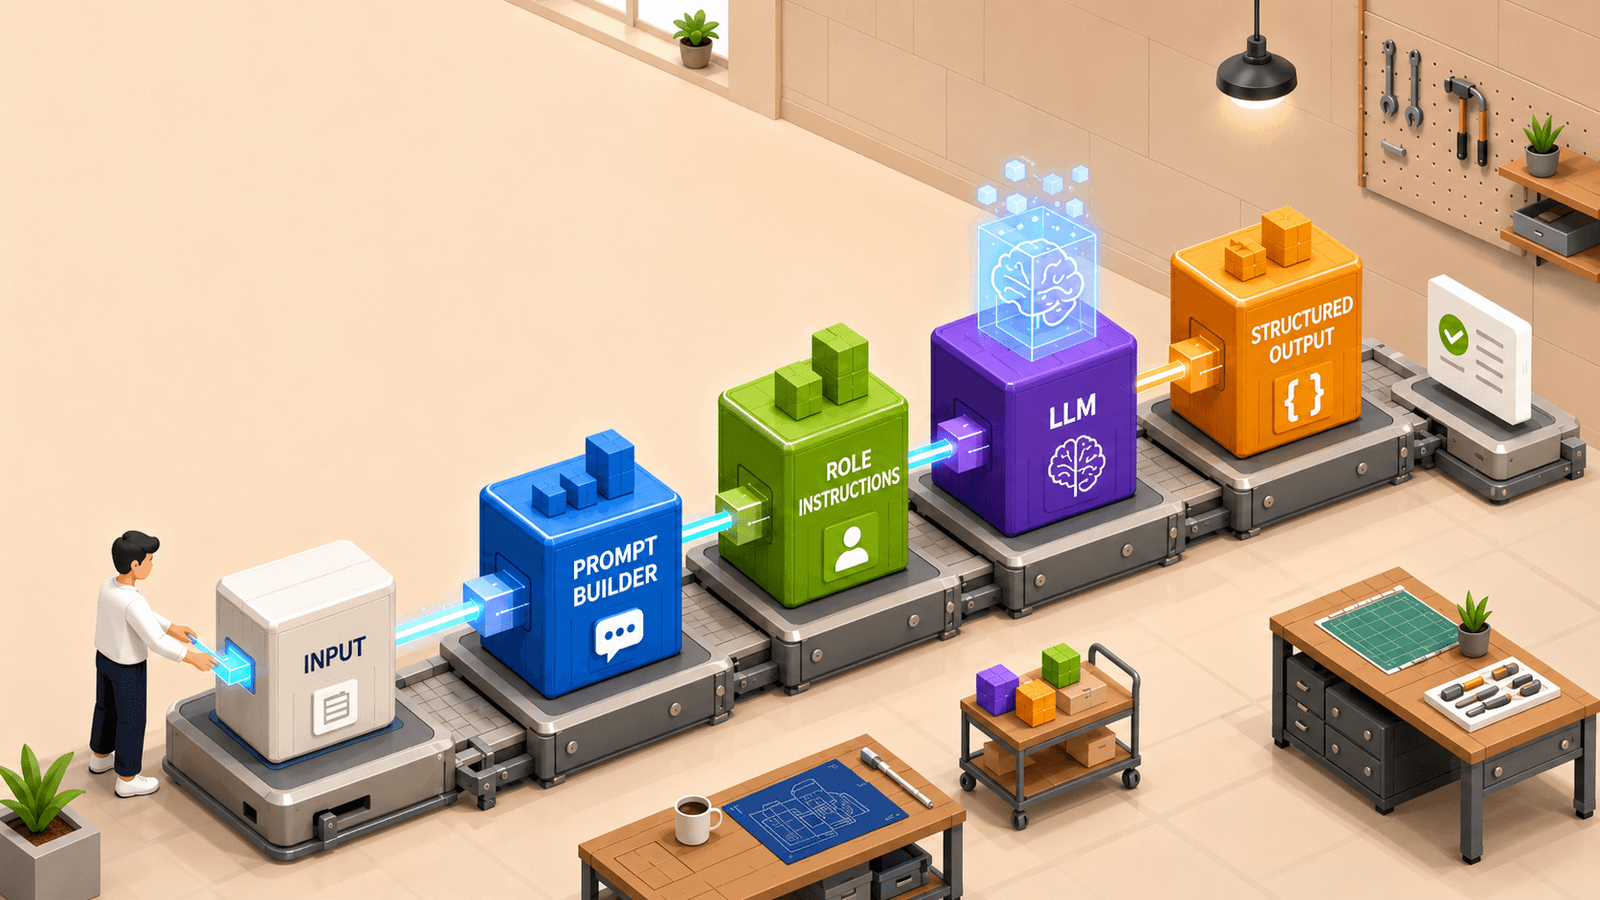
Most LLM Apps Need Workflows Not Agent Frameworks
Most LLM apps ship faster and more reliably as deterministic workflows than autonomous agents. Plain Python with structured outputs and local functions beats CrewAI and LangGraph for debugging. Map control flow in code before importing any agent framework.
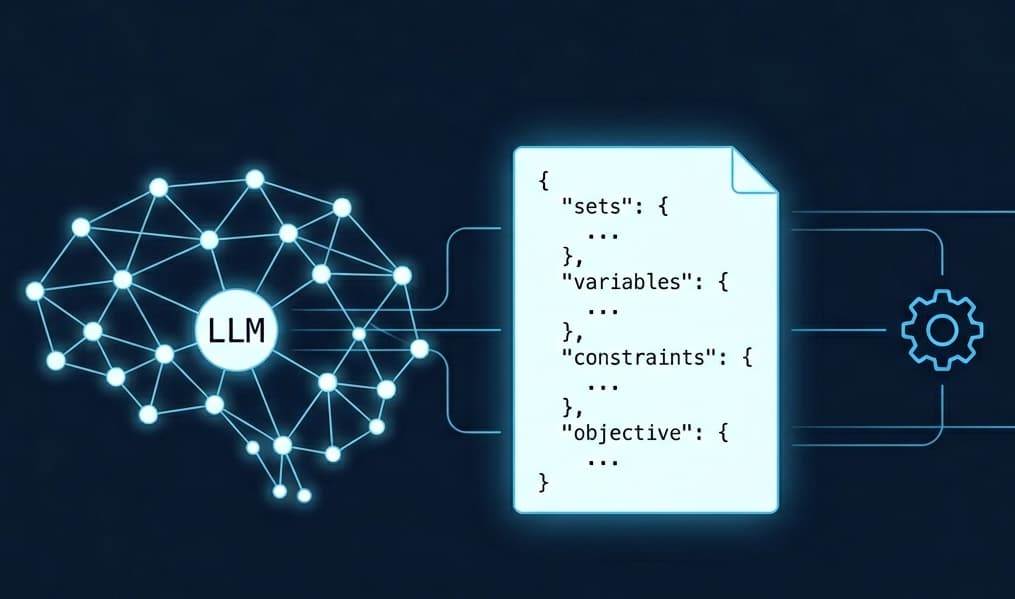
ORPilot JSON IR Ends Solver Lock-In
ORPilot's open-source IR captures optimization models as solver-agnostic JSON, letting teams swap solvers or update data without calling the LLM again. It separates model structure from solver syntax, making LLM-generated OR models reproducible in production.

Default Churn Thresholds Waste $86 per Customer
90% of 36 IBM Telco churn analyses use F1 and a 0.5 threshold, assuming equal costs for false positives and negatives. That is wrong by 13x, burning $86 per customer, or $8.6M at 100k subscribers. Swap accuracy for profit curves tied to LTV and CAC.
Design a cost-aware ML training platform for heterogeneous hardware
Tests hardware abstraction and cost-aware cross-accelerator scheduling. Strong answers cover a device-agnostic spec, a performance predictor, a cost-per-step model, and bin-packing against spot prices. Red flag: ignoring per-step cost and migration overhead.
How does a model registry differ from cloud storage like S3?
This tests model governance beyond raw storage. A strong answer contrasts storage with stage transitions, lineage, and ACLs, then lists metadata like metrics, dependencies, and schemas. A red flag is treating S3 folders with naming conventions as a registry.
Explain a model registry's purpose and what to store per version
Tests if you treat the registry as a governance bridge between training and production, not just storage. Strong answers cite versioned artifacts, lineage, metrics, dependencies, and approval gates. Red flag: calling it a file dump or experiment tracker.
How would you design drift detection for high-dimensional embeddings?
Tests distribution shift in latent spaces beyond per-feature stats. Strong answers use maximum mean discrepancy, k-NN two-sample tests, or domain-classifier AUC, plus windowing. Red flag: per-dimension KS tests or mean-difference thresholds.
How do you monitor model health with delayed ground truth labels?
Tests ML ops maturity beyond accuracy. A strong answer covers input drift via PSI or KS tests, prediction distribution shifts, proxy business metrics, and human spot-checking. A red flag is passively waiting for labels or retraining blindly without validation.
How do you configure Docker for host GPU access and CUDA libraries?
This tests GPU passthrough via the NVIDIA Container Toolkit. Strong answers use nvidia/cuda base images matching the host driver, pass GPUs with --gpus all, and avoid installing drivers inside the container.
Why avoid global Python dependencies for ML, and how do containers help?
This probes environment isolation and reproducibility in ML. A strong answer cites global dependency conflicts, system library skew, and brittle environments; then notes containers freeze the full stack for deterministic deployment.
Design a centralized model registry for a large enterprise
Tests ML artifact governance at scale. Strong answers cover immutable versioned artifacts with dependency manifests, a framework-agnostic API, and pluggable deployment targets. Red flag: treating models as opaque files without environment reproducibility.
Debug sudden model degradation using experiment tracking and model registry
Tests unified use of experiment tracking and registry lineage. Great answers verify the exact production artifact, inspect linked training data and hyperparameters, compare input distributions, and check dependency metadata.
Reproduce a six-month-old model using experiment tracking
Trace code commit, dataset version, feature pipeline, hyperparameters, dependency manifest, and random seeds through a model registry.
Describe a Model Registry and how it differs from versioned storage
It tests governance and lifecycle metadata beyond file storage. A strong answer covers lineage, stage transitions, approval gates, and artifact metadata, contrasting with buckets that only store file versions.
Why systematically track ML experiments and what should you log?
This tests reproducibility mindset over bookkeeping. A strong answer names three motivations—reproducibility, selection, debugging—and three logs: hyperparameters, metrics, and code versions.
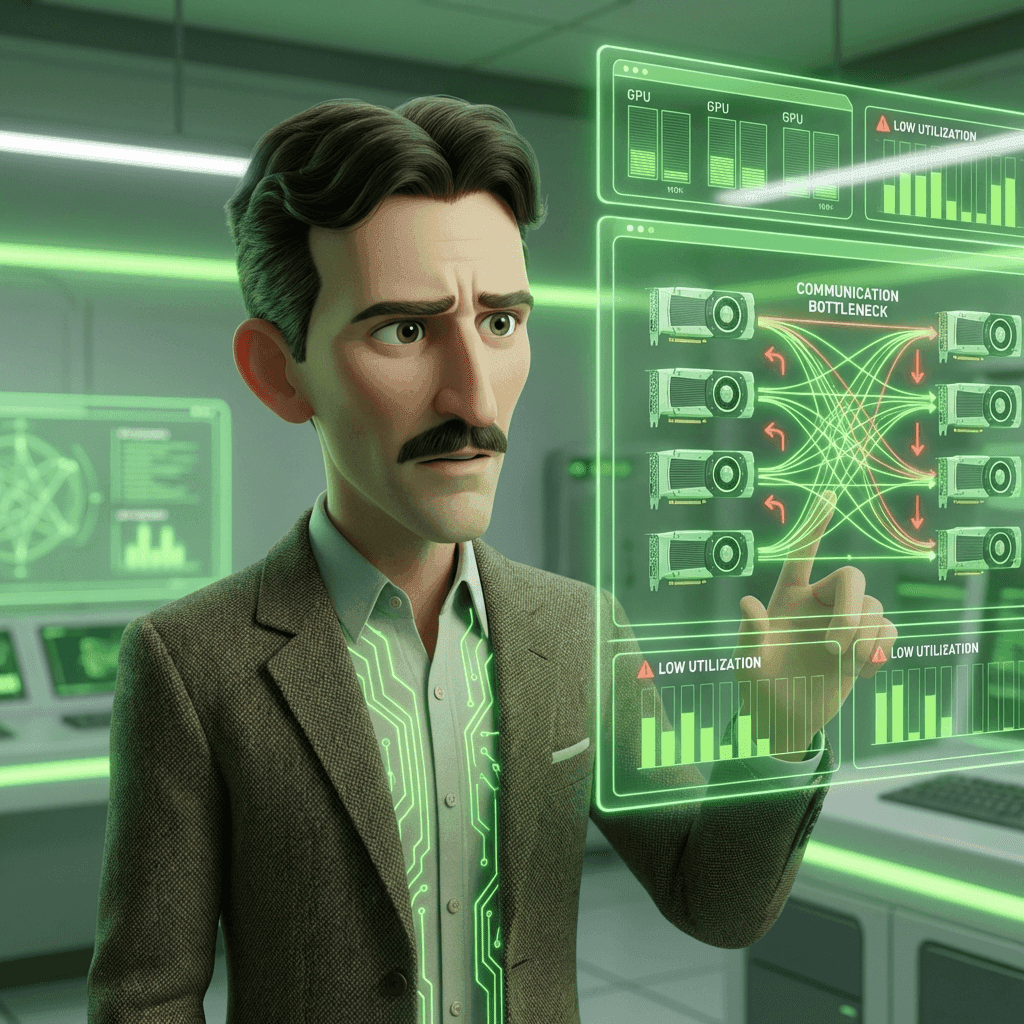
Low GPU utilization on multi-GPU instance: diagnose and right-size
Tests distributed bottleneck triage. Strong answers profile CPU/GPU/disk, compare gradient sync time to compute, validate per-GPU batch size, and check NVLink vs PCIe. Red flag: suggesting more GPUs before ruling out data starvation or all-reduce overhead.
Design an ML workflow that masks PII from scientists
This tests privacy-preserving pipeline design and least-privilege access for ML teams. Propose automated de-identification before experimentation, restrict re-identification to production jobs, and enforce role-based access with audit logs.

Compare and contrast Apache Airflow versus Kubeflow Pipelines for ML orchestration
This tests matching orchestrators to ML constraints. A strong answer contrasts Airflow's task scheduling and backfills with Kubeflow's K8s-native GPU scaling, choosing based on team skills.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles