Low GPU utilization on multi-GPU instance: diagnose and right-size
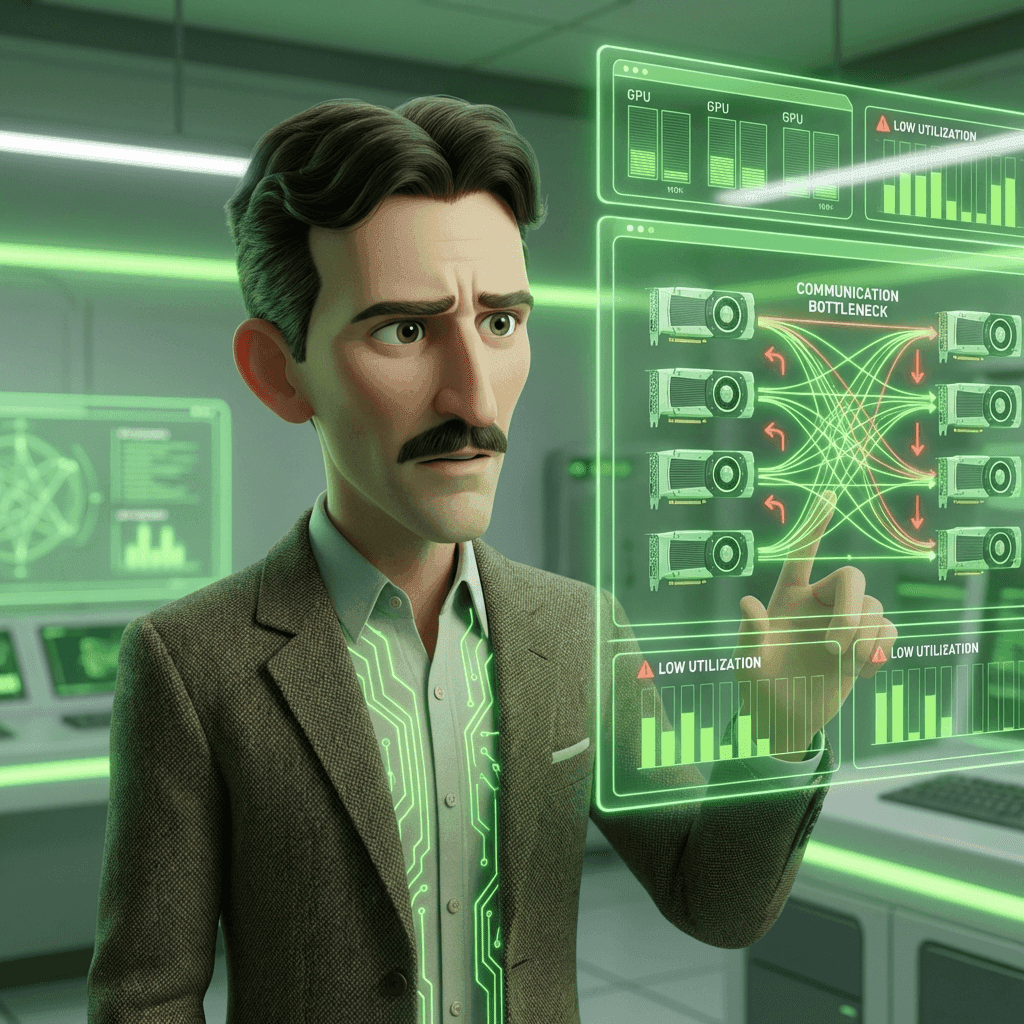
Tests distributed bottleneck triage. Strong answers profile CPU/GPU/disk, compare gradient sync time to compute, validate per-GPU batch size, and check NVLink vs PCIe. Red flag: suggesting more GPUs before ruling out data starvation or all-reduce overhead.
What's really being asked
This tests whether a senior engineer can reason about the full stack of distributed deep learning performance, from data ingestion through interconnect topology to framework-level parallelism strategy. The interviewer wants to see structured debugging, not guesswork.
The full answer
A good answer hits four things in order. First, establish a measurement baseline by profiling GPU kernels, CPU utilization, disk I/O, and network bandwidth to identify which resource is actually starved. Second, investigate the data pipeline because low utilization often means the GPU is waiting on CPU preprocessing or slow storage; solutions include increasing prefetch workers, moving augmentation to GPU, or using faster NVMe storage. Third, analyze communication overhead by comparing all-reduce time to compute time per step; if gradient synchronization dominates, the bottleneck is likely slow interconnects like PCIe instead of NVLink, or the model is too small to amortize communication. Fourth, examine the per-GPU batch size and parallelism mode; if splitting the global batch leaves each GPU with insufficient work, CUDA cores stay idle, and using DistributedDataParallel instead of DataParallel can reduce cross-GPU traffic. Right-sizing means reverting to fewer GPUs or a single GPU when communication exceeds computation.
The mistakes people make
A common wrong answer is immediately recommending more or bigger GPUs without profiling, which often worsens the bottleneck. Another red flag is blaming the framework without checking hardware topology, or suggesting DataParallel for multi-GPU setups when DDP is strictly more efficient. Candidates who ignore the data pipeline and focus only on math kernels miss the most frequent root cause in production.
What usually comes next
Interviewers often ask how you would interpret NCCL timeline traces, what batch size threshold justifies NVLink over PCIe for a specific model, or how mixed precision affects memory bandwidth and utilization. They may also probe whether pipeline or tensor parallelism would help more than data parallelism for the given model size.
A concrete example
Suppose a ResNet-50 training job on four A100s shows thirty percent utilization. You check dataloader workers and find CPU preprocessing is the bottleneck, so you move augmentation to the GPU and increase workers from two to eight, which raises utilization to seventy percent. You then measure all-reduce time and discover it equals compute time because the model is running over PCIe Gen4 without NVLink; since the per-GPU batch is already small, you consolidate to two GPUs and achieve higher throughput than four.
Interview question
Which set of symptoms best indicates that low GPU utilization on a multi-GPU instance is caused by communication overhead that should be solved by right-sizing to fewer GPUs rather than by pipeline optimization?
- a.The job runs DataParallel with high CPU overhead from gradient copying
- b.CPU preprocessing is the bottleneck and dataloader worker count is too low
- c.All-reduce time matches compute time, interconnect lacks NVLink, and per-GPU batches are already smallCorrect
- d.Disk I/O is saturated and prefetching cannot keep the GPUs fed
Why? this is the answer
When gradient synchronization equals compute time over a slow PCIe link and each GPU already has insufficient work, adding more GPUs worsens the all-reduce overhead, so consolidating raises throughput. Distractor A describes the most common root cause in production, but it should be fixed by tuning the data pipeline rather than removing GPUs.
Just read this? Test yourself on what you have been reading.
Read the original → itctshop.com
- #mlops
- #distributed-training
- #gpu-utilization
- #performance-debugging
- #deep-learning
You just looked this up. Could you explain it out loud?
That is the part interviews actually test. Tezvyn takes questions like this one and gives you what the interviewer is really checking, the answer that lands, and the mistake that ends the conversation, in the four minutes before your next meeting.
The iPhone app is on the way
We are building it. Until it lands, nothing here is held back from you: every interview card, your saved cards, streaks and the job board all work in Safari, plus hundreds of free practice quizzes of thirty questions each. Sign in and it all carries over to the app the day it arrives.
Want it as an icon? Tap Share at the bottom of Safari, then Add to Home Screen. It opens full screen and the cards you have read stay available offline.
We are hiring for this. Open roles that interview on mlops — each one lists the topics its interview covers.
See open roles