Multi-Armed Bandits: Balancing Exploration and Exploitation
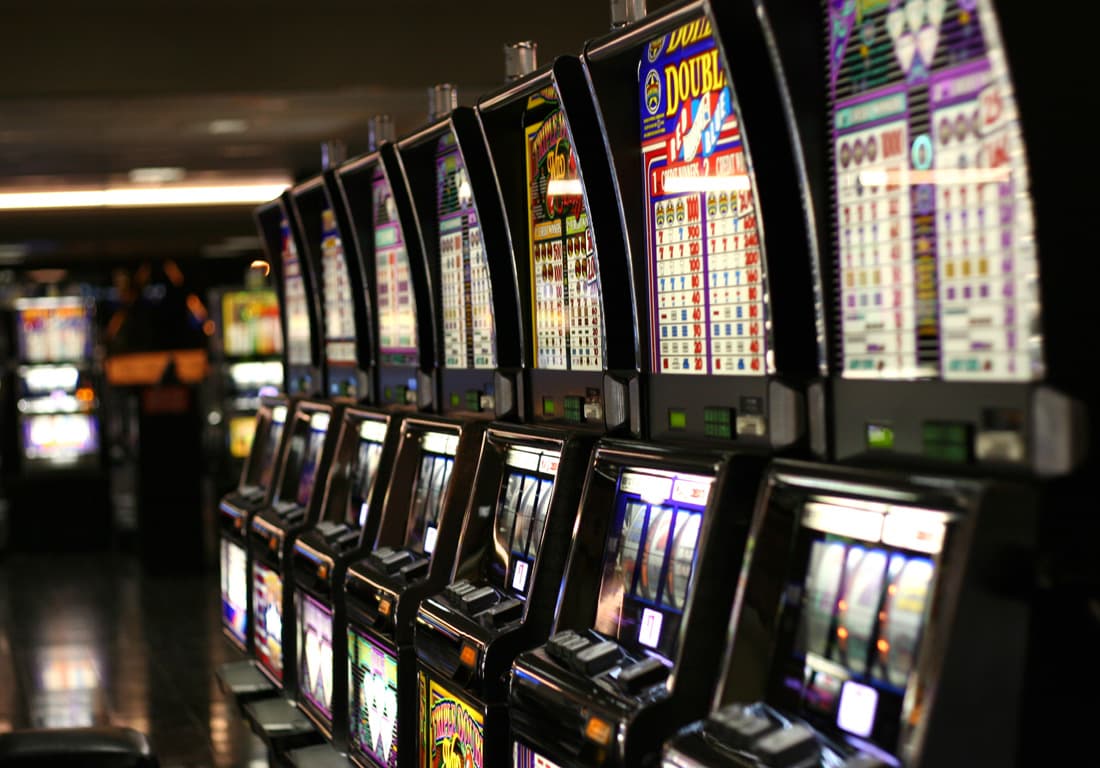
A multi-armed bandit algorithm balances exploiting a known winner with exploring new options to find a better one. It's used to dynamically test website headlines or ad copy, automatically shifting traffic to the best performer to maximize conversions.
Why it exists
Traditional A/B testing can be inefficient. You commit to a fixed test duration and sample size, knowingly sending half your traffic to a potentially inferior version. This costs you conversions. Multi-armed bandit algorithms were designed to solve this by minimizing "regret"—the lost value from not showing the best option—by dynamically optimizing during the test itself.
The mental model
Imagine you're at a casino with several slot machines, each a "one-armed bandit." Each has a different, hidden payout rate. Your goal is to maximize winnings. Do you keep playing the machine that has paid out the most so far (exploitation)? Or do you try other machines to see if they have a better payout rate (exploration)? A bandit algorithm is a formal strategy for making this decision at every step.
How it works
A bandit algorithm begins by distributing traffic evenly across all variants to gather initial data (pure exploration). As it collects results (clicks, signups, etc.), it updates its confidence about which variant is the best. It then starts sending more traffic to the current leader (exploitation) while still allocating a small percentage to the other options to continue learning. This allows it to adapt if a different variant proves better over time. Different strategies, like Epsilon-Greedy or Thompson Sampling, manage this trade-off in slightly different ways.
When to use it
Use a bandit approach for optimizing short-term campaigns, testing many variants at once (more than A/B), or for elements like headlines and ad copy where the goal is to maximize immediate performance. It finds a winner and exploits it quickly, rather than waiting for a formal test to conclude.
When not to use it
Stick with a classic A/B test when you need high statistical confidence about why a variant won and by how much. Bandits are great at picking a winner, but because they alter traffic allocation, they make it difficult to get a clean, statistically significant measure of performance lift. Avoid them if the goal is deep analysis for a permanent change.
One canonical example
A media site wants to find the best headline for a breaking news story. It tests five headlines using a bandit algorithm. Initially, each gets 20% of the traffic. After 30 minutes, headline C has a much higher click-through rate. The algorithm shifts traffic so headline C now gets 70%, while the other four share the remaining 30%. This maximizes clicks while the story is popular, instead of waiting hours for an A/B test to declare a winner.
Interview question
For which scenario would a traditional A/B test typically be preferred over a multi-armed bandit approach?
- a.Minimizing the "regret" or lost value from showing suboptimal content during an ongoing optimization process.
- b.Dynamically allocating traffic to the best-performing ad copy among ten variants in a live campaign.
- c.Optimizing a short-term landing page with five different headline options to maximize immediate conversions.
- d.Determining the precise statistical significance and underlying reasons for a new feature's long-term impact on user engagement.Correct
Why? this is the answer
Traditional A/B tests are preferred when the goal is to achieve high statistical confidence and understand the causal factors of a variant's performance, as bandits' dynamic traffic allocation makes such clean analysis difficult. Option A describes the core benefit of multi-armed bandits, not a reason to prefer A/B testing.
Just read this? Test yourself on what you have been reading.
Read the original → en.wikipedia.org
Put your scrolling time to good use
Learn one idea, try a quiz and save useful cards for revision. Tezvyn makes it easy to learn and stay current in your tech field, a few minutes at a time.
The iPhone app is on the way
We are building it. Until it lands, nothing here is held back from you: every interview card, your saved cards, streaks and the job board all work in Safari, plus hundreds of free practice quizzes of thirty questions each. Sign in and it all carries over to the app the day it arrives.
Want it as an icon? Tap Share at the bottom of Safari, then Add to Home Screen. It opens full screen and the cards you have read stay available offline.
We are hiring for this. Open roles that interview on optimization — each one lists the topics its interview covers.
See open roles