Advanced everything in Backend Dev, page 13
Rust's Arc<T>: Share Data Ownership Across Threads
Rust's Arc<T> lets multiple threads share ownership of heap data. It's a smart pointer that counts references atomically. Use it for shared caches or config. The footgun: Arc only makes sharing safe, not mutation—you still need a Mutex for that.
Rust's Rc<T>: Shared Ownership on a Single Thread
Rust's Rc<T> enables shared ownership within a single thread. Think of it as a counter on a heap-allocated resource: cloning an Rc increments the count, and the resource is freed only when the count hits zero. Use it for graph nodes with multiple owners.
Go's sync.Map: A Specialized Concurrent Map
Go's sync.Map is a concurrent map optimized for keys written once and read many times. It's ideal for long-lived caches, but it's not a generic replacement for a map with a mutex. The footgun is using it for frequent writes, which can be slower.
Using Box<T> for Heap Allocation in Rust
Rust's Box<T> is a smart pointer that moves data from the stack to the heap. It's essential for creating recursive types, like linked lists, whose size would otherwise be infinite. The main footgun is in FFI: never wrap a C-allocated pointer in a Box.
Rust's Turbofish (`::<>`): When the Compiler Needs Help
The turbofish (::<>) is your tool to resolve ambiguity when Rust's compiler can't infer a type or trait. Use it when a type implements multiple traits with same-named methods, forcing the compiler to pick the one you specify.
Zero-Cost Abstractions: Pay at Compile Time, Not Runtime
Zero-cost abstractions let you write high-level code that compiles to the same machine code as low-level optimizations. This is key in Rust for safe APIs without runtime overhead.
HNSW: Vector Search with a Graph Highway System
HNSW finds approximate nearest neighbors in huge datasets by building a multi-layered graph, like a highway system over local roads. It's the engine in vector databases for similarity search. The footgun: it trades perfect accuracy for massive speed gains.
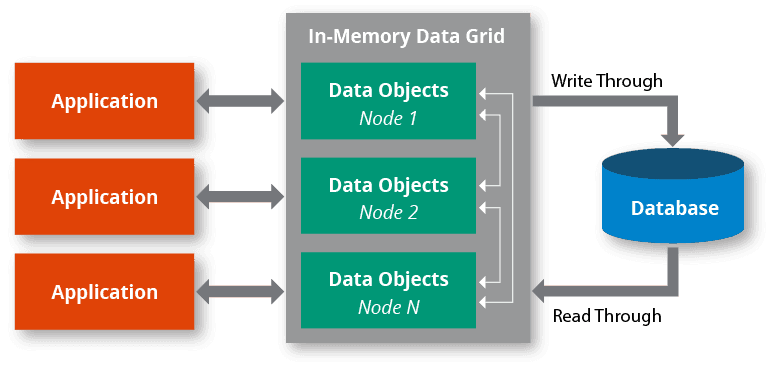
In-Memory Data Grid: A Shared RAM Pool for Your Cluster
An In-Memory Data Grid (IMDG) pools the RAM of multiple computers into one massive, shared data space. It's for high-speed processing on datasets too large for one machine. The footgun is mistaking it for a simple cache; it also provides parallel computation.

Continuous Queries: Automating Time-Series Aggregation
A continuous query automatically aggregates real-time data on a schedule. Use it to create downsampled rollups, like hourly averages from raw sensor data, storing results in a new series.
Approximate Nearest Neighbor (ANN) Search: Good Enough, Fast Enough
ANN search finds 'pretty close' neighbors in a massive dataset for a fraction of the cost of finding the exact closest one. It powers vector databases and semantic search.

CockroachDB: A SQL Database That Survives Disasters
CockroachDB is a distributed SQL database designed to be unkillable. Use it for global apps needing strong consistency and high availability, like financial ledgers or identity systems. The footgun: ignoring network latency between nodes can kill performance.
Google Cloud Spanner: A Globally Distributed SQL Database
Spanner is a globally distributed SQL database that scales like NoSQL but keeps the strong consistency of a relational database. Use it for global applications like financial ledgers that need ACID transactions across continents.
NewSQL: SQL Scalability Without Sacrificing ACID
NewSQL databases aim for NoSQL's horizontal scaling with the ACID guarantees of a traditional relational database. They suit high-throughput OLTP systems, like e-commerce, that must scale out. The footgun is assuming they are a simple drop-in replacement.
Database Proxies: A Manager for Your Database Traffic
A database proxy is a manager between your app and database, handling requests to improve performance and security. It pools connections, caches queries, and balances load, preventing any single server from being overwhelmed.
Data Mapper Pattern: Decoupling Your Domain from Your DB
A Data Mapper is a dedicated layer that moves data between in-memory objects and a database. This decouples your business logic from persistence, keeping domain objects clean and unaware of the database schema. It's the opposite of the Active Record pattern.
Active Record: Your Object is the Database Row
The Active Record pattern treats an object as a self-managing database row, bundling data with persistence logic. It's great for simple CRUD apps, but tightly couples your business logic to your database schema, making complex refactors difficult.
Database Parameter Tuning: Beyond the Defaults
Database defaults are a compromise. Parameter tuning tailors the database to your specific workload, hardware, and reliability needs. It's used to optimize memory, WAL settings, or query planning.
Database Disaster Recovery: Planning for Total Failure
Database Disaster Recovery (DR) assumes your primary site is gone for good, focusing on restoring service at a secondary location. It's for critical systems where regional outages are unacceptable. The footgun is confusing DR with High Availability (HA).
Database High Availability: Surviving Server Failure
High Availability (HA) means having a hot standby database ready to take over instantly upon failure. It's essential for critical systems like payment gateways where downtime is unacceptable.
Causal Consistency: A Memory Model for Concurrency
Causal consistency is a rulebook for concurrent systems, defining legal data access patterns. It's used to ensure correctness in distributed shared memory and transactions, preventing data corruption from simultaneous operations.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles