Intermediate everything in Backend Dev, page 24
Phantom Reads: When New Rows Appear Mid-Transaction
A phantom read occurs when a transaction repeats a query and finds new rows that match its search criteria, inserted by another committed transaction. It's common in reporting jobs that need a stable set of data.
Watermarks: Defining 'Done' in Event Streams
A watermark tells a stream processor when a time window is 'complete' for unordered events. It's a timestamped signal declaring 'no more data is expected before this point,' allowing aggregations to be finalized. The key footgun is balancing lateness vs.
Multi-Region Databases: Resilience, Latency, and Compliance
A multi-region database is a strategy for resilience, low latency, and data compliance. It's used to survive region outages, keep data in-country, and serve reads close to users. The footgun is managing low-level replica placement directly, which is complex.
Synchronous vs. Asynchronous Replication: A Trade-off
Replication is a trade-off: synchronous waits for all copies to confirm a write, guaranteeing consistency but risking availability. Asynchronous lets the primary move on immediately, prioritizing speed.
Vectorized Query Execution: Processing Batches, Not Rows
Vectorized execution processes data in batches of thousands of rows, not one at a time. This lets analytical databases like ClickHouse and Snowflake scan billions of rows in seconds by keeping data in CPU cache and using SIMD instructions.

Hash-Based Aggregation: Grouping Data Without Sorting
Hash-based aggregation uses a hash table to group data for functions like COUNT or SUM, avoiding a costly sort. It's used in database query engines for GROUP BY operations, especially when distinct groups fit in memory.

Multi-Leader Replication: Enabling Writes Across Datacenters
Multi-leader replication allows multiple nodes to accept writes, avoiding a single-leader bottleneck. It's used in multi-datacenter systems for low-latency local writes and in offline apps. The main footgun is resolving write conflicts from concurrent updates.
Single-Leader Replication: One Node to Rule Them All
Think of a single source of truth. One 'leader' server takes all writes, while 'follower' servers handle read traffic. This is the default for many databases like PostgreSQL and MongoDB to scale reads.

Buffer Manager: The Database's Memory Gatekeeper
The buffer manager acts as a database's private RAM cache, deciding which data pages to keep in memory versus fetching from slow disk. It's central to query performance, as it tries to serve all data requests from this fast cache.
Optimizer Hints: Backseat Driving Your Database
An optimizer hint lets you override the database's query plan, like telling a GPS which street to take. Use it as a last resort when you know more than the optimizer, but beware: hints can become performance traps when data or schemas change.
Semantic Search: Finding Meaning, Not Just Keywords
Semantic search finds meaning, not just keywords. It's like asking a librarian for 'books about space travel' and getting results for 'astronaut biographies,' not just titles with the exact words. It's used in search engines to find conceptually related items.
Downsampling: Trading Precision for Storage in Time Series Data
Downsampling trades precision for storage in aging time series data. It's like summarizing old notes: you keep key trends but discard granular details. This is vital for observability systems that need recent precision but only coarse historical views.
Faceted Search: Guided Drill-Down for Large Datasets
Faceted search turns a massive result list into an interactive drill-down experience, like the filters on a shopping site. It's used in e-commerce and document libraries where items have structured attributes.
Cache Eviction: Deciding What to Forget
A cache eviction policy is the rule for discarding data when fast-access memory is full. This is crucial for databases and CDNs. The common mistake is assuming one policy, like LRU, fits all workloads, which can cripple performance on certain access patterns.
Full-Text Search: Beyond Simple String Matching
Full-text search isn't just string matching; it's a search engine for your data that understands language. Use it for e-commerce search or log analysis. The footgun is thinking a simple LIKE query is a substitute for a real search engine like Elasticsearch.
Windowing: Taming Infinite Data Streams
Windowing chops infinite data streams into finite chunks for aggregation, like counting clicks per minute. It's essential for real-time dashboards, fraud detection, and IoT sensor analysis. The main footgun is mishandling late data by confusing event time vs.
Delta Lake: Database Reliability for Your Data Lake
Delta Lake adds a transaction log to your data lake, giving you database-like reliability over raw files. This enables ACID transactions, schema enforcement, and unified batch/streaming pipelines.
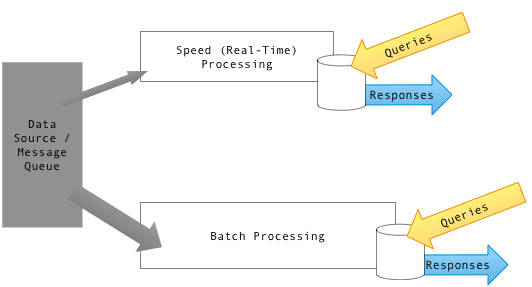
Lambda Architecture: Batch + Stream for Big Data
Lambda Architecture handles massive datasets by combining slow, accurate batch processing with fast, real-time stream processing. It's used for analytics needing both historical and live views.
Schema Evolution: Changing a Live Database Without Outages
Schema evolution is like renovating a house while you live in it: you must change your database's structure without breaking the live application. This is critical when adding or renaming columns.
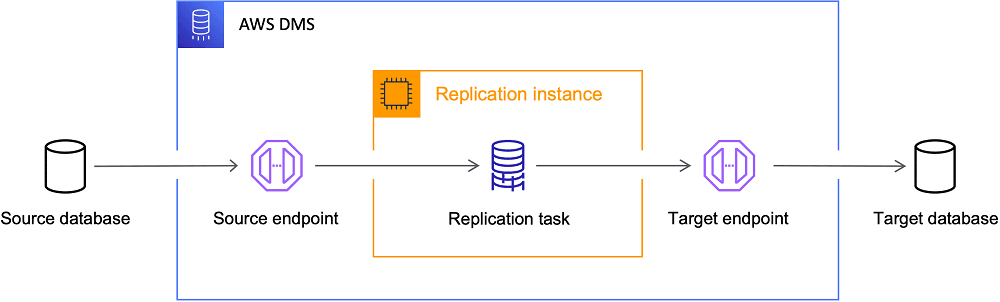
AWS DMS: Your Managed Database Migration Engine
AWS DMS is a managed service for migrating databases. It acts like a replication server you point at a source and target, handling the data transfer. It's used for one-time migrations to AWS or for continuous replication.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles