Concepts in Databases & Architecture, page 7
Delta Lake: Database Reliability for Your Data Lake
Delta Lake adds a transaction log to your data lake, giving you database-like reliability over raw files. This enables ACID transactions, schema enforcement, and unified batch/streaming pipelines.
Windowing: Taming Infinite Data Streams
Windowing chops infinite data streams into finite chunks for aggregation, like counting clicks per minute. It's essential for real-time dashboards, fraud detection, and IoT sensor analysis. The main footgun is mishandling late data by confusing event time vs.
Inverted Index: How Search Engines Find Your Keywords
An inverted index is like a book's index: it maps keywords to the documents containing them. This is the core of full-text search in search engines and databases, allowing instant lookups.

Cache-Aside Pattern: Your App Owns the Cache
The Cache-Aside pattern makes your application the gatekeeper for the cache. On a read, your code checks the cache first; on a miss, it fetches from the database and writes to the cache. This speeds up read-heavy apps. The key footgun is stale data.

Vector Embeddings: Turning Meaning into Math
Vector embeddings turn complex data like words or images into lists of numbers (vectors). This lets computers measure "similarity" by calculating the distance between these vectors, powering search and recommendations.
Data Retention Policy: Your Schedule for Deleting Data
A data retention policy is your company's official schedule for deleting data, not a plan to keep it forever. It's essential for legal compliance (like GDPR) and managing storage costs.
Full-Text Search: Beyond Simple String Matching
Full-text search isn't just string matching; it's a search engine for your data that understands language. Use it for e-commerce search or log analysis. The footgun is thinking a simple LIKE query is a substitute for a real search engine like Elasticsearch.
Cache Eviction: Deciding What to Forget
A cache eviction policy is the rule for discarding data when fast-access memory is full. This is crucial for databases and CDNs. The common mistake is assuming one policy, like LRU, fits all workloads, which can cripple performance on certain access patterns.
Faceted Search: Guided Drill-Down for Large Datasets
Faceted search turns a massive result list into an interactive drill-down experience, like the filters on a shopping site. It's used in e-commerce and document libraries where items have structured attributes.
Downsampling: Trading Precision for Storage in Time Series Data
Downsampling trades precision for storage in aging time series data. It's like summarizing old notes: you keep key trends but discard granular details. This is vital for observability systems that need recent precision but only coarse historical views.
Semantic Search: Finding Meaning, Not Just Keywords
Semantic search finds meaning, not just keywords. It's like asking a librarian for 'books about space travel' and getting results for 'astronaut biographies,' not just titles with the exact words. It's used in search engines to find conceptually related items.
Approximate Nearest Neighbor (ANN) Search: Good Enough, Fast Enough
ANN search finds 'pretty close' neighbors in a massive dataset for a fraction of the cost of finding the exact closest one. It powers vector databases and semantic search.

Continuous Queries: Automating Time-Series Aggregation
A continuous query automatically aggregates real-time data on a schedule. Use it to create downsampled rollups, like hourly averages from raw sensor data, storing results in a new series.
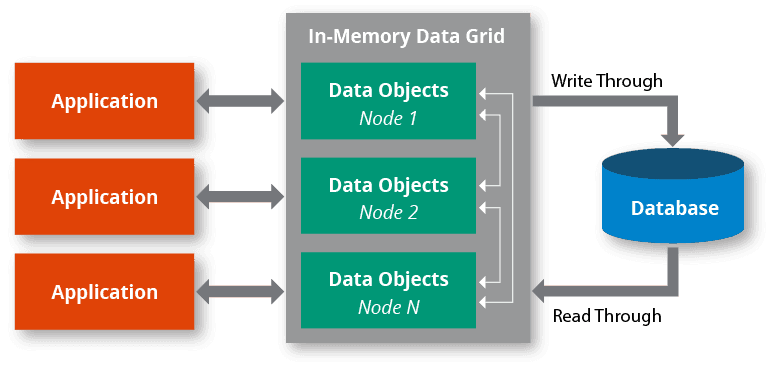
In-Memory Data Grid: A Shared RAM Pool for Your Cluster
An In-Memory Data Grid (IMDG) pools the RAM of multiple computers into one massive, shared data space. It's for high-speed processing on datasets too large for one machine. The footgun is mistaking it for a simple cache; it also provides parallel computation.
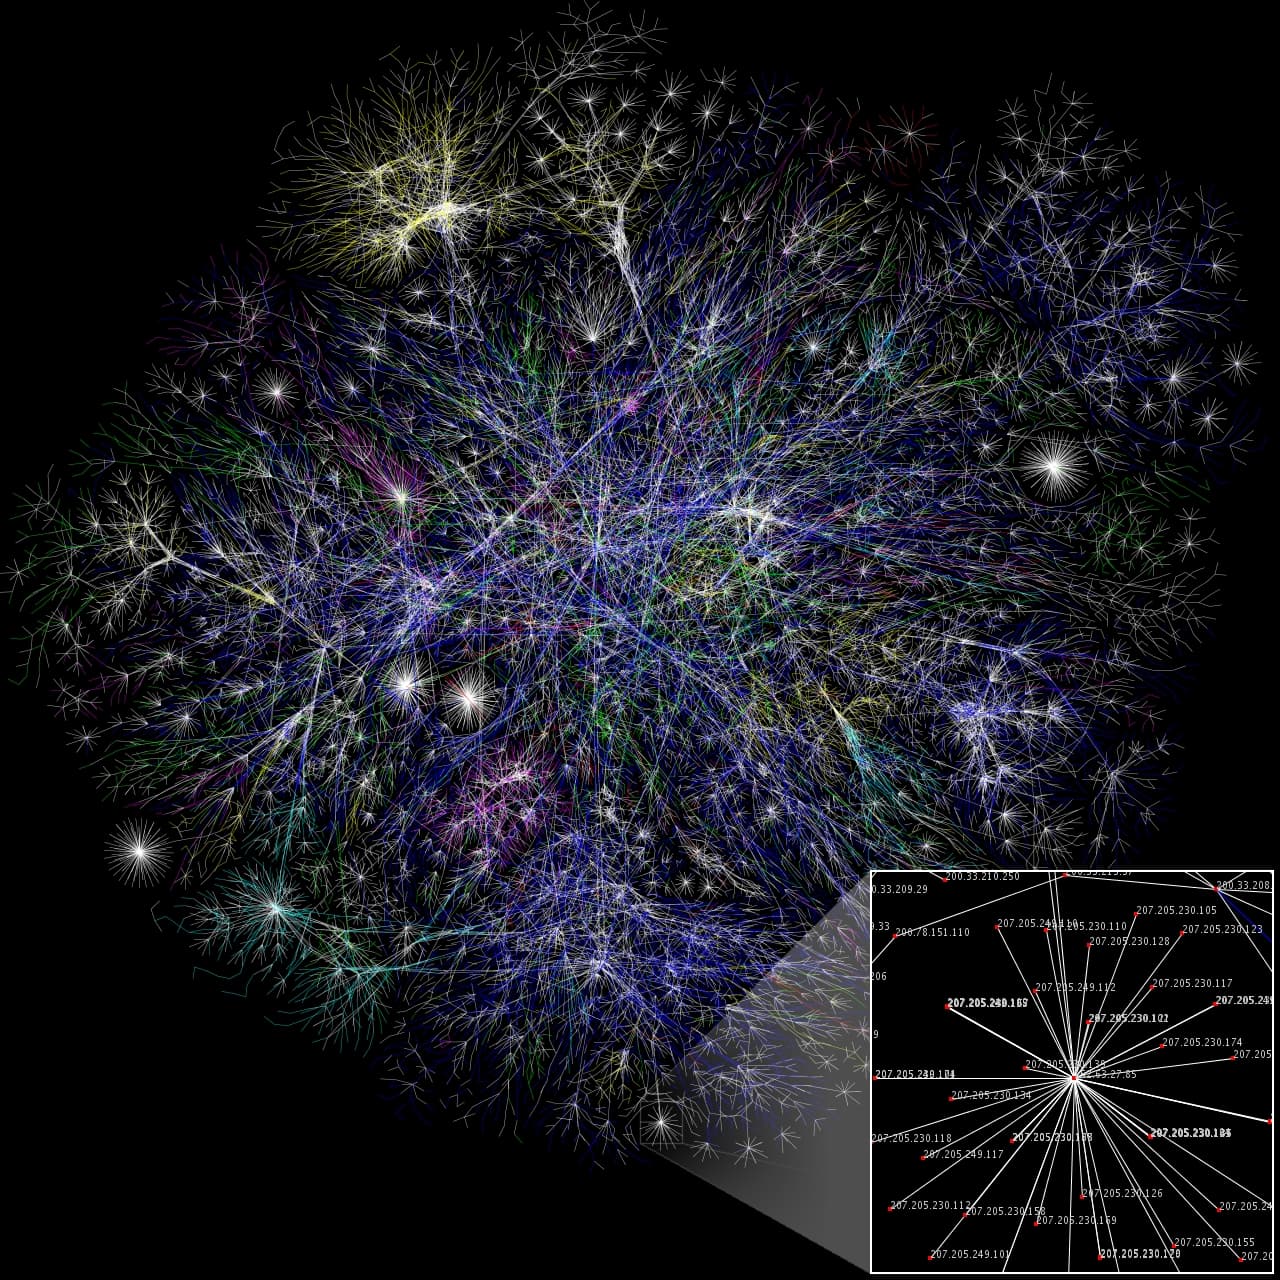
HNSW: Vector Search with a Graph Highway System
HNSW finds approximate nearest neighbors in huge datasets by building a multi-layered graph, like a highway system over local roads. It's the engine in vector databases for similarity search. The footgun: it trades perfect accuracy for massive speed gains.
Optimizer Hints: Backseat Driving Your Database
An optimizer hint lets you override the database's query plan, like telling a GPS which street to take. Use it as a last resort when you know more than the optimizer, but beware: hints can become performance traps when data or schemas change.

Buffer Manager: The Database's Memory Gatekeeper
The buffer manager acts as a database's private RAM cache, deciding which data pages to keep in memory versus fetching from slow disk. It's central to query performance, as it tries to serve all data requests from this fast cache.
Single-Leader Replication: One Node to Rule Them All
Think of a single source of truth. One 'leader' server takes all writes, while 'follower' servers handle read traffic. This is the default for many databases like PostgreSQL and MongoDB to scale reads.

Multi-Leader Replication: Enabling Writes Across Datacenters
Multi-leader replication allows multiple nodes to accept writes, avoiding a single-leader bottleneck. It's used in multi-datacenter systems for low-latency local writes and in offline apps. The main footgun is resolving write conflicts from concurrent updates.

Hash-Based Aggregation: Grouping Data Without Sorting
Hash-based aggregation uses a hash table to group data for functions like COUNT or SUM, avoiding a costly sort. It's used in database query engines for GROUP BY operations, especially when distinct groups fit in memory.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles