Intermediate everything in DevOps & Cloud, page 14
How would you add E2E tests to CI and what challenges arise?
This tests CI/CD pipeline design. Cover Dockerized environments, parallel runs, flaky-test retries, and selective execution such as critical tests per commit and full suites nightly. Red flag: running all tests on every commit without isolation or retries.
How do you keep one build artifact immutable across environments?
This tests separation of build and run stages. A strong answer packages one artifact with zero embedded config, then injects env vars or mounted secrets at deploy time via the platform. Red flags include per-stage rebuilds or config baked into the image.

How would you implement zero-downtime secrets rotation?
Inventory secrets and app caching; baseline monitoring; dual-phase rotation with overlapping secrets; verify before revoking old.

How would you design an automated artifact repository cleanup policy?
Balancing cost, compliance, and speed via tiered artifact retention. A strong answer covers age rules, deployment state, protected tags, and dry-run gates.
Compare monorepo and polyrepo strategies in CI/CD
Tests repo structure impact on builds, dependencies, and pipeline triggers. Contrast monorepo atomicity with polyrepo autonomy; cover monorepo change-detection versus polyrepo versioning and contract tests.
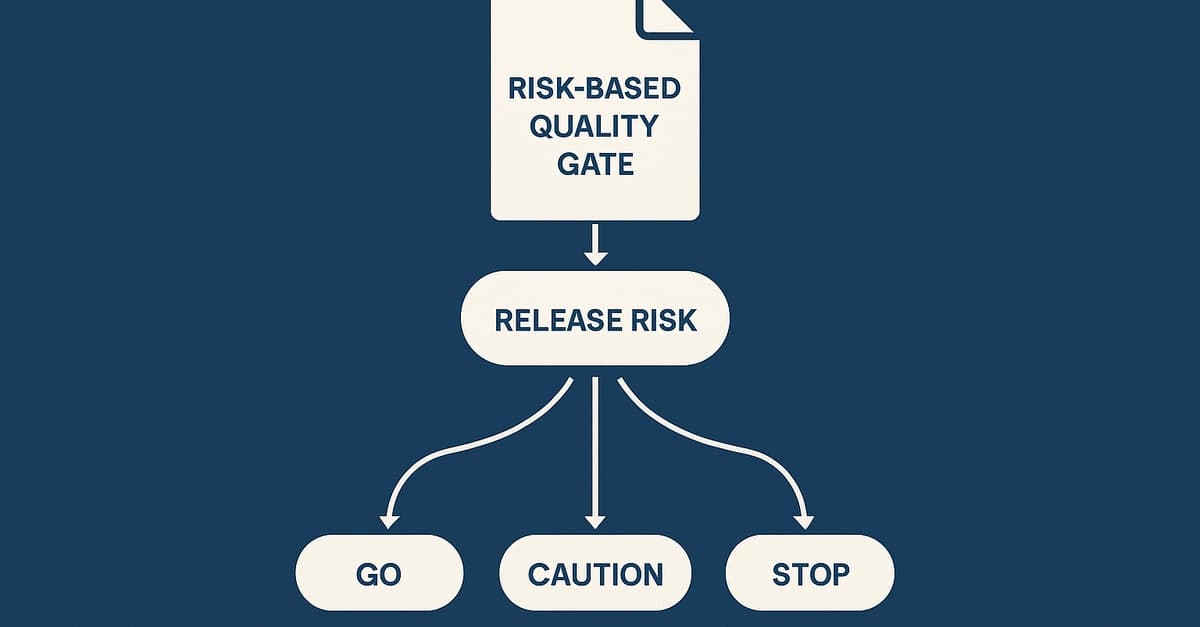
Design a dynamic, risk-based quality gate system
Tests if you can move CI/CD from binary pass/fail to contextual risk scoring. Strong answers define criticality tiers, weight signals by severity and blast radius, and emit GO/CAUTION/STOP states.
Design a Docker artifact system for cost, traceability, and speed
Tests cost-speed-auditability tradeoffs for artifacts at scale. Strong answers cover tiered storage with lifecycle policies,immutable build provenance,regional caching, and automated garbage collection. Red flag: infinite mutable storage with no cleanup rules.
How would you collect metrics and KPIs for your Internal Developer Platform?
This tests product-thinking: treating developers as customers, not captive users. Strong answers cover adoption (golden-path usage), developer experience (deploy speed, NPS), and business value. Red flag: tracking CPU or uptime without linking to adoption.
Diagnose CI/CD queue bottlenecks and propose three throughput improvements
This tests CI/CD scheduling and queuing theory. A strong answer profiles queue versus execution time, then proposes right-sizing parallelism, aggressive caching, and workload sharding. A red flag is jumping straight to adding agents without measuring first.
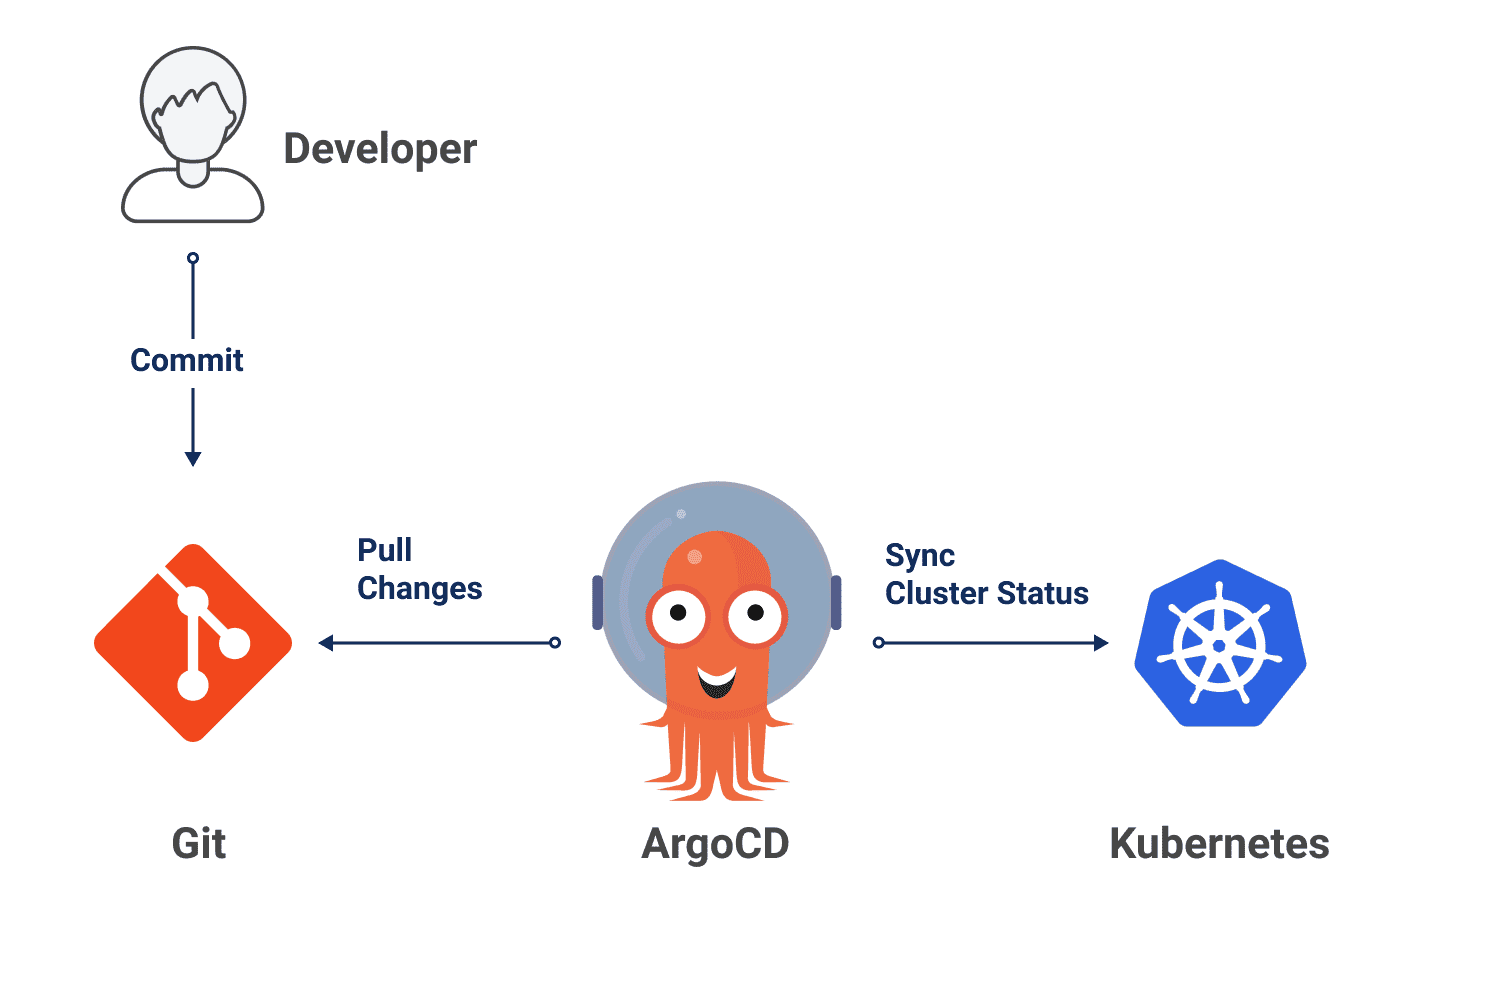
What is configuration drift in GitOps and how do tools handle it?
This tests declared and actual state and GitOps reconciliation. A strong answer defines drift as out-of-band changes, notes auditability, and contrasts self-healing sync with read-only detection. A red flag is suggesting manual patches rather than fixing Git.
Two common GitOps repository layouts for multiple environments
Tests GitOps state-store trade-offs beyond single-cluster demos. Contrast a monorepo with directory overlays against repo-per-env; weigh polling overhead, blast radius, and promotion flow. Recommending branch-per-env destroys immutability and invites drift.
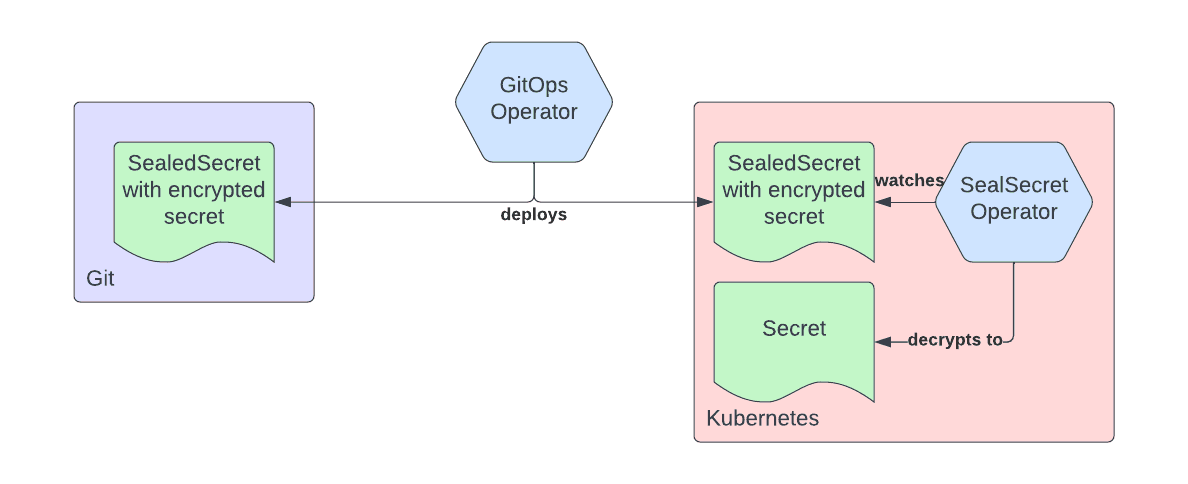
How do you secure secrets in a GitOps repository?
Tests whether you treat Git as source of truth while excluding plaintext credentials. A strong answer covers encrypting at rest with SOPS or Sealed Secrets, external stores like Vault, and operator workflows.
How would you instrument CI/CD to measure a DORA metric accurately?
Tests mapping DORA definitions to pipeline events. A strong answer picks one metric, defines exact boundaries from merge to production, and correlates deployments with incidents.
How would you use distributed tracing to debug a deployment latency issue?
This tests causal request-path analysis beyond aggregate metrics. A strong answer filters traces by the new version, finds the exact regressed span, and compares it to a pre-deployment baseline.
Design an automated rollback process when deployment error rates spike
Gate on error-rate and latency thresholds; use blue-green deploys to limit blast radius; require human approval for stateful rollbacks.
How do you diagnose a progressively slower CI pipeline?
Profile stage durations and critical path, audit runner CPU/memory/disk, flag flaky or late-failing tests.
How would you integrate automated security scanning for Terraform in CI/CD?
Run Checkov or TFLint in CI to block builds; catch open security groups, missing encryption, secrets in code, and bad IAM.

Compare SAST and DAST. Why use both, and their limits?
Tests whether you understand complementary security testing layers in CI/CD. A strong answer contrasts static source analysis without execution against dynamic runtime attack simulation and explains that relying on only one leaves applications vulnerable.
How do you investigate and resolve a critical transitive dependency vulnerability?
It tests transitive CVE triage. A strong answer reproduces the finding, traces the dependency path, upgrades the direct dependency if possible, and considers build-tool overrides otherwise. Red flag: ignoring it as transitive or blind upgrades without tests.
How can a service mesh facilitate canary or A/B testing?
Tests mesh-level traffic control decoupled from app releases. Strong answers name traffic shifting, request routing, ingress gateways, and telemetry-driven rollback. Red flag: citing mTLS alone and omitting observability automation.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles