Interview questions in Growth & Experimentation, page 4
How do you ensure consistent A/B test variants across sessions and devices?
Tests stable identity and delayed attribution. Fix: one stable user ID for SDK bucketing, persisted across devices via login or first-party cookies, attached to every conversion event. Never use per-device randomization or third-party cookies.
Design a system to handle subscription renewals
States include active, past_due, and cancelled; transitions are payment success, dunning exhaustion, and grace expiry; use idempotent webhooks.
How would you instrument an application to calculate Customer Lifetime Value?
Tests whether you tie revenue and cost events to persistent identity and model cohort retention. Outline: track purchases, CAC, and churn with persistent IDs; project value via retention curves.

What are the key architectural differences between freemium and free trial models?
Contrast tiered entitlements against trial timers and revocation; discuss free-user overhead and conversion tracking.
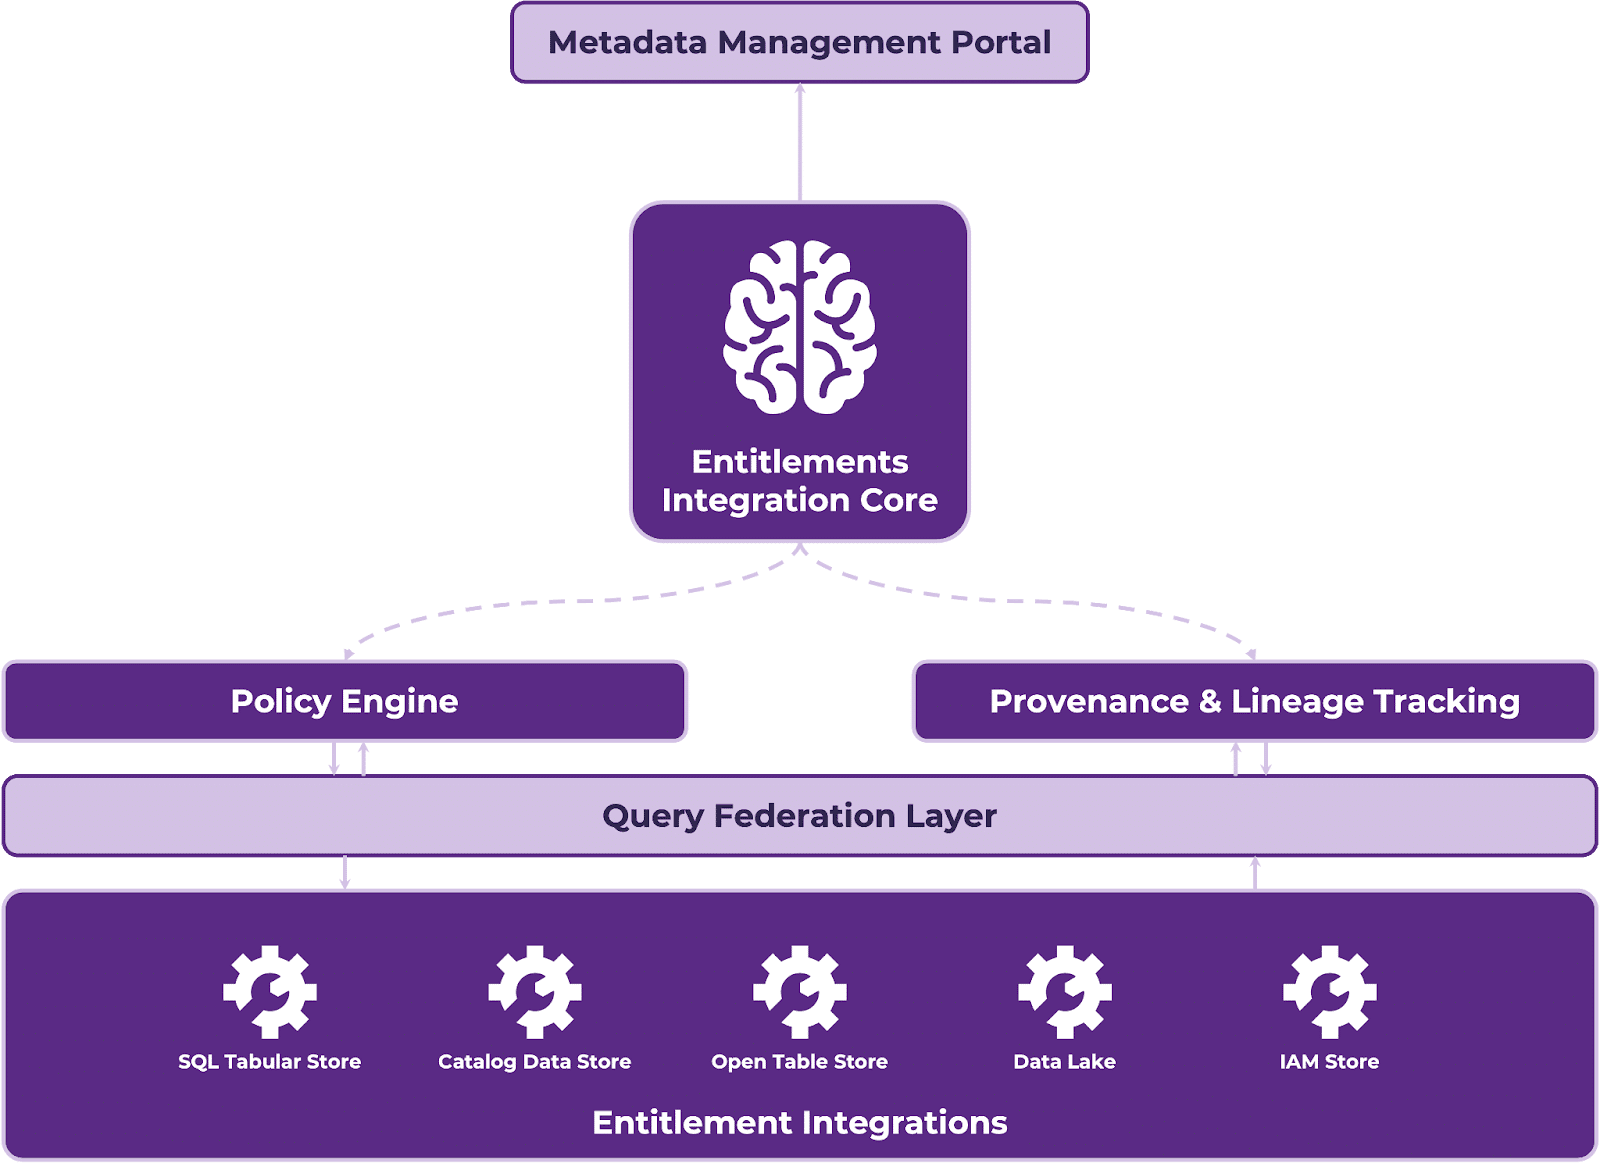
Design a highly available entitlements service with caching
This tests balancing read performance with consistency in access control. A strong answer proposes tiered caching with proactive invalidation, read-optimized hot paths, and event-sourced temporary grants.
How would you design international monetization with multi-currency and tax?
Localized pricing, jurisdictional tax, gateway routing, async reconciliation.
How would you instrument a key activation milestone event?
Tests schema design beyond a bare event name. A strong answer includes the event key, user ID, timestamp, and properties like project_id and is_first_project. Red flag: omitting the user ID or sending only a human-readable label without structured context.

Implement a 10% onboarding tutorial feature flag and track success
Tests lightweight experiment design and metric selection beyond vanity numbers. Strong answers cover user-ID bucketing, conversion tracking, and guardrail metrics like drop-off. Red flag: manual toggles or click-through without downstream outcomes.

Design referral tracking from invite to conversion
Tests data modeling for multi-stage conversion tracking. Strong answers separate codes from conversion events, model status transitions, and enforce unique constraints. Weak answers merge invite and reward into one table or store denormalized counts on users.
How would you enforce a 3-project freemium limit and handle upgrades?
Tests entitlement and growth tradeoffs. Strong answers use API-level enforcement, atomic checks to prevent concurrent overages, soft upsell prompts preserving context, and async billing webhooks. Red flag: UI checks or limits in the projects table.
Walk me through a magic link login system and its security considerations
Tests auth architecture and threat modeling for passwordless flows. Strong answers map request-token-email-verify-session, then harden with short expiry, single-use tokens, rate limits, and device binding.
Design a multivariate experimentation platform with collision-free concurrent bucketing and cross-device consistency
Tests orthogonal layers and cross-session assignment persistence. Cover: deterministic hashing per layer, a user profile service for sticky bucketing, and stable ID resolution across devices. Red flag: random bucketing or local storage breaking consistency.

Architect real-time usage-based billing for a PLG company
This tests event-driven metering, idempotent aggregation, and pricing decoupling at scale. A strong answer outlines real-time ingestion, stream processing for micro-events, a rules-based pricing engine, and dashboards with reconciliation.

What data pipelines and infrastructure feed a viral user acquisition model?
Tests causal attribution architecture. Great answers cover invite instrumentation with identity resolution, streaming pipelines that split organic and viral signups, and feature stores for network-state features.

What data and approach for a simple 30-day DAU forecast?
Tests forecasting from sessionized logs without overengineering. Cite timestamped events, a 30 min session rule, and a regression baseline with day-of-week, recent totals, scored with MAE. Red flag: deep learning before a baseline or ignoring privacy hashing.

Why is extrapolating 5% weekly growth naive for annual forecasting?
This tests knowledge of extrapolation limits. A strong answer cites market saturation, seasonality, and channel exhaustion as invalidating factors, and notes that compounding 5% over 52 weeks magnifies error.

What differentiates leading and lagging indicators for subscriptions?
Leading indicators forecast; lagging indicators confirm. Subscriptions: activation rate leads, MRR lags.

How would you model a 10% Day-1 retention improvement's impact on LTV?
Tests whether you model retention as a survival curve, not a single point. A strong answer builds a cohort curve, propagates D1 lift to D30/D90 via decay, and sums revenue. Red flag: claiming 10% D1 gain equals 10% LTV growth without curve assumptions.

How would you incorporate external events into a time-series forecast?
This tests exogenous regressor design. A strong answer proposes binary or continuous regressors for holidays and campaigns in Prophet or ARIMA, then validates lift via backtesting. A red flag is dropping outlier days or applying post-hoc manual adjustments.
Communicate forecast uncertainty with prediction intervals
A point estimate hides risk; produce a prediction interval via model error, simulation, or scenarios, and state assumptions.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles