How would you design architecture to sidestep a competitor's proprietary dataset?
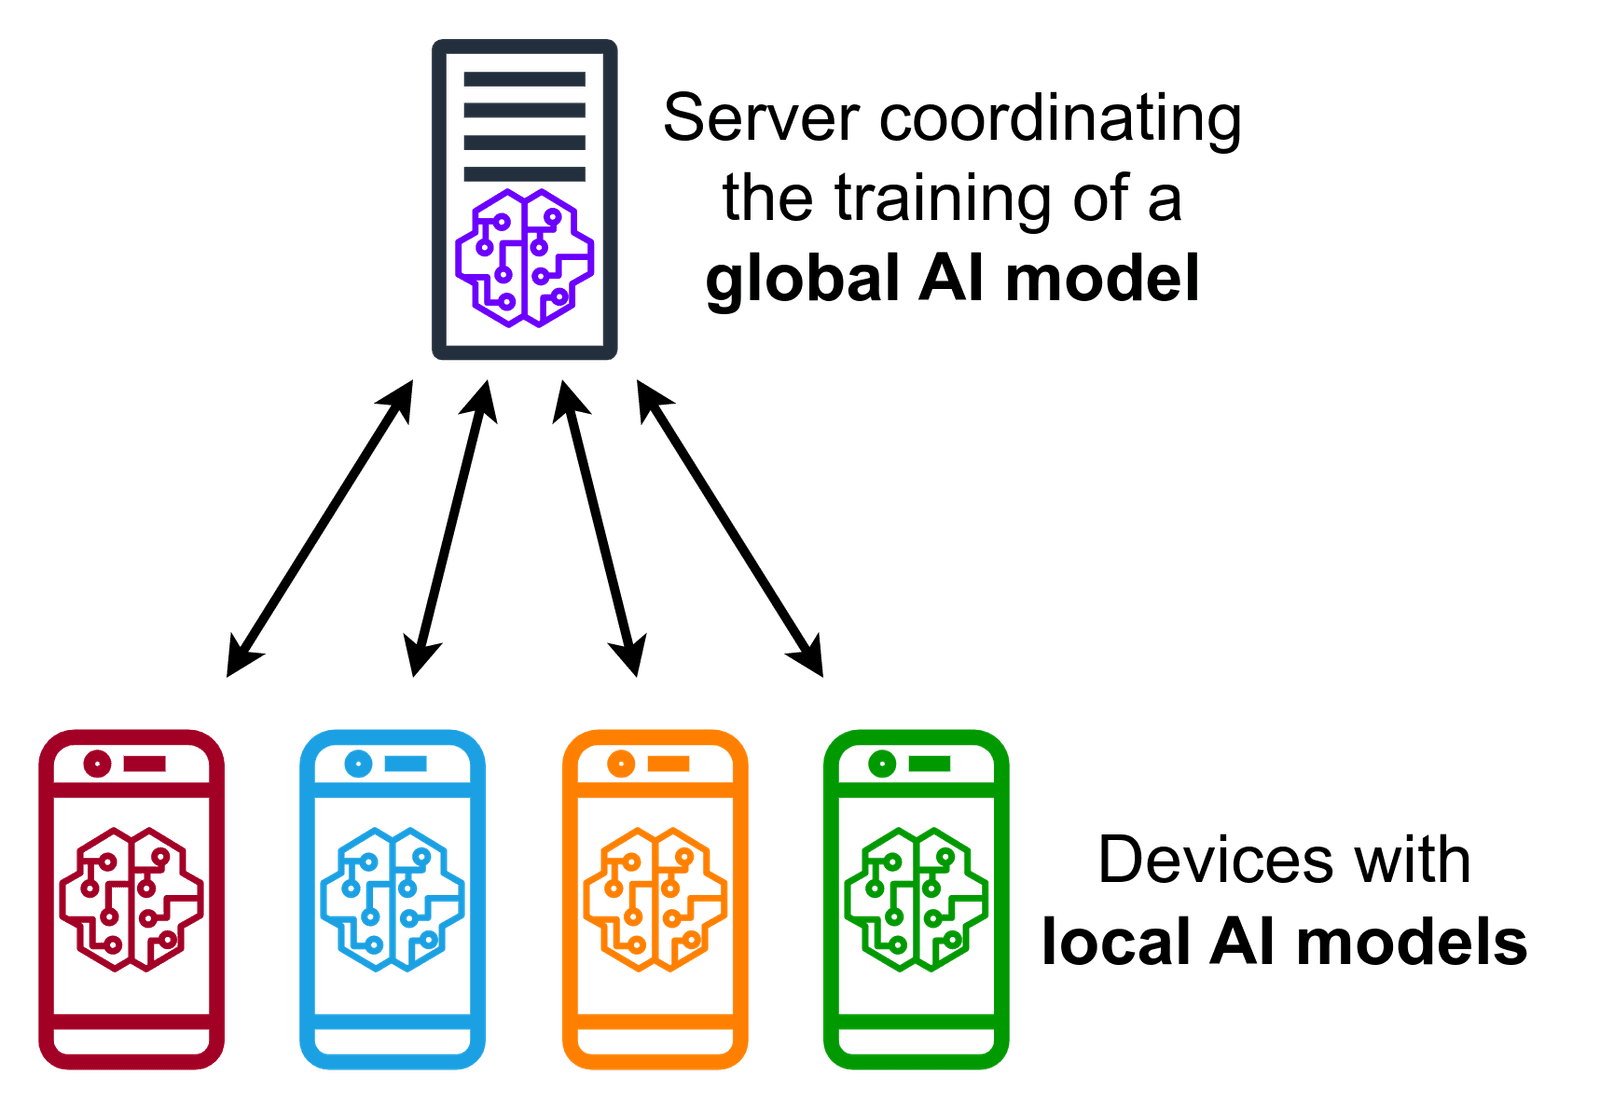
Tests architecture without data moats. Strong answers pick asymmetric plays like real-time loops, federated learning, or synthetic pipelines and link them to defensible design. Red flag: buying or copying the dataset.
What's really being asked
The interviewer wants to see if you can escape a zero-sum data arms race and design a system that creates value through architecture rather than asset ownership. They are looking for product-strategy thinking backed by technical depth, specifically how to turn a data disadvantage into a sustainable advantage via system design choices.
The full answer
First, a reframing of the competitive axis from data volume to data velocity or exclusivity, explaining why real-time processing, edge inference, or federated loops can outperform static batch datasets. Second, a concrete architecture sketch that decentralizes data collection, such as federated learning where multiple entities collaboratively train a model while keeping their data decentralized, leveraging the natural data heterogeneity and non-IID distributions across clients as a feature rather than a bug. Third, privacy-preserving or consent-based data mechanisms that competitors cannot legally replicate even if they wanted to, creating a regulatory moat. Fourth, a feedback loop that improves the product experience, which in turn generates more data, creating a structurally different flywheel that does not depend on the competitor's historical corpus.
The mistakes people make
Suggesting you will buy, scrape, or partner your way to parity on dataset size, which admits defeat on the competitor's home turf. Proposing synthetic data generation without explaining how it avoids garbage-in-garbage-out or how it maps to real user value. Describing federated learning purely as a privacy buzzword without addressing data heterogeneity, non-IID distributions, or the engineering cost of decentralized training. Ignoring the product implication entirely and treating the problem as a pure model-training exercise.
What usually comes next
How do you handle cold-start when decentralized nodes have sparse data? What is your unit economics for on-device inference versus cloud training? How do you prevent model poisoning or bias amplification across heterogeneous clients? If federated learning reduces your visibility into data, how do you debug and monitor model quality? How do you convince users or enterprises to join your decentralized network when the competitor offers a polished centralized product?
A concrete example
Imagine competing with a centralized transcription service that has ten million hours of labeled audio. You design a keyboard app that runs a tiny on-device model using federated learning. Users get instant predictions without uploading keystrokes. The model improves nightly via federated averaging across millions of phones, each with heterogeneous non-IID language patterns. Your product differentiates on privacy and latency, not accuracy on a static test set, and the architecture makes it illegal for the centralized competitor to copy your privacy guarantee without rebuilding their entire stack.
Interview question
When competing against a rival with a massive proprietary dataset, which architectural approach best transforms a data disadvantage into a sustainable system-level advantage?
- a.Launching a partnership program to acquire labeled datasets approaching the competitor's corpus within 18 months
- b.Designing a real-time federated loop that leverages non-IID client data and privacy-preserving constraints as structural moatsCorrect
- c.Implementing federated averaging as a privacy layer while centralizing raw data backups for debugging and monitoring
- d.Deploying a synthetic data pipeline to match the competitor's model accuracy on standard benchmarks
Why? this is the answer
The correct answer captures the advanced strategy of escaping a zero-sum data race by architecting for velocity, decentralization, and regulatory moats rather than volume parity. Option C is a tempting distractor because it uses federated terminology, yet centralizing raw data backups undermines the privacy guarantee and defensible architecture the interviewer seeks.
Just read this? Test yourself on what you have been reading.
Read the original → en.wikipedia.org
- #product-strategy
- #system-design
- #federated-learning
- #data-moats
- #competitive-architecture
You just looked this up. Could you explain it out loud?
That is the part interviews actually test. Tezvyn takes questions like this one and gives you what the interviewer is really checking, the answer that lands, and the mistake that ends the conversation, in the four minutes before your next meeting.
The iPhone app is on the way
We are building it. Until it lands, nothing here is held back from you: every interview card, your saved cards, streaks and the job board all work in Safari, plus hundreds of free practice quizzes of thirty questions each. Sign in and it all carries over to the app the day it arrives.
Want it as an icon? Tap Share at the bottom of Safari, then Add to Home Screen. It opens full screen and the cards you have read stay available offline.
We are hiring for this. Open roles that interview on product-strategy — each one lists the topics its interview covers.
See open roles