Advanced concepts in AI & ML, page 5
Text-to-Video Generation: From Prompt to Picture Show
Text-to-video models are like a film director in a box, turning written descriptions into moving pictures. This tech, powered by video diffusion models, is used for creating short-form content or prototyping visual ideas from a simple text prompt.
Panoptic Segmentation: A Unified View of a Scene
Panoptic segmentation unifies two tasks: it labels every pixel with a class ('stuff' like road, sky) and also identifies individual object instances ('things' like car 1, car 2). It provides a complete scene understanding for autonomous driving and robotics.
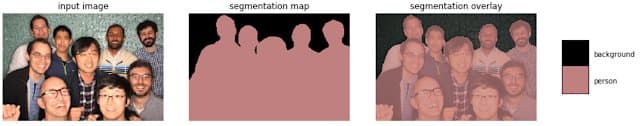
DeepLab: Pixel-Level Semantic Image Segmentation
DeepLab assigns a class label like 'road' or 'person' to every pixel in an image. This powers features like smartphone portrait mode by precisely outlining objects. The key challenge is achieving sharp object boundaries, not just coarse bounding boxes.
Mask R-CNN: Region-Based Detection
Mask R-CNN belongs to the R-CNN family core: selective search over CNN feature maps yields bounding boxes with object categories. Reusing convolutional features for localization, not just classification, is the win.
Conditional Random Fields: Labeling with Context
A Conditional Random Field (CRF) makes predictions that know their neighbors, enforcing that nearby pixels in an image get similar labels. It cleans up raw segmentation outputs by considering local context.
Model Pruning: Making ML Models Smaller and Faster
Model pruning is like trimming a bonsai tree; you remove the least important weights to create a smaller, faster model. It's essential for running large models on devices like smartphones, but over-pruning can irreversibly damage accuracy.

Regularization: Penalizing Complexity to Prevent Overfitting
Regularization is a complexity tax on a machine learning model, forcing it to favor simpler patterns over memorizing training data. It's used to prevent overfitting in models like neural networks, improving their performance on new, unseen data.
Model Compilation: Bridging Models and Hardware
An ML compiler translates a model's abstract math into optimized instructions for specific hardware. This lets you run the same model efficiently on cloud GPUs, mobile CPUs, or edge devices.
Random Forest: Many Weak Learners Make One Strong Model
A random forest asks a crowd of simple decision trees for a prediction and takes the majority vote. This ensemble approach is used for classification and regression, correcting for a single tree's tendency to overfit. The footgun is its lower interpretability.
Ensemble Learning: Bagging vs. Boosting
Ensemble methods combine multiple weak models into one strong one, like a committee outperforming a single expert. Bagging reduces variance; Boosting reduces bias. The footgun: Boosting can overfit noisy data by trying to model the noise itself.
Multi-Model Serving: Packing More Models into Less RAM
Multi-model serving is a carpool for your ML models. Instead of one server per model, you pack many into a single process to share resources and cut costs. It's ideal for serving many models with intermittent traffic.
BERTScore: Judging AI Text on Meaning, Not Just Words
BERTScore evaluates AI-generated text by comparing its meaning to a reference, not just matching words. It's used to score machine translation or summarization where phrasing can vary.
MMLU Benchmark
MMLU (Measuring Massive Multitask Language Understanding) is a popular benchmark for evaluating large language models. Its influence is shown by its many spin-offs, making it a foundational tool for comparing AI capabilities.
Why Elo Ratings for LLMs Can Be Misleading
Elo ranks LLMs like chess players, but models have fixed skills, not dynamic ones. This method powers leaderboards but produces volatile scores, meaning a model's rank can be an unstable estimate of its true, unchanging ability.
LLM-as-a-Judge: Using Models to Grade Models
Instead of paying humans to rate AI outputs, LLM-as-a-Judge uses a powerful 'judge' model to do it automatically. This is used to evaluate chatbot responses or summarization quality, but the main footgun is assuming the judge model is unbiased or perfectly…
SUTVA: The Assumption That Your Treatment Isn't Leaking
SUTVA assumes your treatment on one person doesn't spill over to affect others, and that the treatment is consistent for all. It's a key assumption for A/B tests, but is violated when one person's vaccine protects their unvaccinated neighbor.
HumanEval: Testing if AI-Generated Code Actually Works
HumanEval is a benchmark that tests if an LLM's generated code is functionally correct, not just syntactically valid. It's used to compare models like Codex by having them solve programming puzzles.
Propensity Score Matching: Simulating a Randomized Trial
Propensity Score Matching creates a 'fair' comparison from observational data, mimicking a randomized trial. It's used to estimate a treatment's effect by matching treated individuals with similar untreated ones.
Causal DAGs: A Map for Cause and Effect
A Causal DAG is a map of your assumptions about what causes what. It helps you spot hidden "confounder" variables that create misleading correlations. Use it before an analysis to decide which variables to control for, ensuring you measure a true effect.
Two-Stream ConvNets: Seeing What vs. How It Moves
Two-Stream ConvNets split video analysis into two paths: a spatial stream sees *what* is in a frame, and a temporal stream sees *how* it moves via optical flow. This is used for action recognition, like telling 'typing' from 'waving'.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles