Intermediate everything in AI & ML, page 24
Datasheets for Datasets: The Nutrition Label for Data
A datasheet is like a nutrition label for a dataset, documenting its origins, contents, and intended use. This is crucial for high-stakes ML systems where hidden biases could cause harm.
Fairness Metrics: Auditing Your AI for Bias
Fairness metrics are statistical checks to see if your model's decisions are biased against certain groups. They're crucial for automated systems in hiring or loan approvals.
AI Accountability: Who's Responsible When AI Fails?
AI accountability means someone is answerable for an AI's actions. It requires organizations to manage risks and trace decisions throughout the AI's lifecycle, ensuring systems function properly and align with human-centric values.
AI Transparency: Explaining the Black Box's 'Why'
AI transparency means seeing the 'why' behind an algorithm's decision, not just its code. It's vital for high-stakes systems like credit scoring or news feeds. The footgun is thinking open-sourcing the model is enough; true transparency explains the logic.
IaC for MLOps: Your ML Factory's Blueprint
Treat ML infrastructure—training clusters, model registries, serving endpoints—as code in version-controlled files. This ensures reproducible experiments and consistent deployments across environments.
Data Drift: Why Good Models Go Bad
Data drift is when a model's accuracy decays because the real-world data it was trained on has changed. This happens in fraud detection as scams evolve or in e-commerce as trends shift.

Model Monitoring: A Health Check for Production AI
Model monitoring is a smoke detector for your AI, alerting you when its performance degrades. It compares live data to training data to catch data drift or shifts in user behavior. The footgun is assuming a model, once deployed, performs well forever.

Pre-attentive Attributes: Your Brain on Autopilot
Pre-attentive attributes are visual properties your brain processes in milliseconds, before you consciously focus. They're the workhorses of data visualization, making outliers and patterns pop out of a dashboard. The biggest mistake is using too many at once.
Columnar Storage: Read Less Data, Analyze Faster
Columnar formats like Parquet store data by column, not by row. This makes analytical queries that select a few columns from a wide table incredibly fast by minimizing disk I/O. It's a poor fit for transactional workloads that need entire rows at once.
Apache Hive: SQL on Hadoop
Apache Hive translates SQL-like queries into Hadoop MapReduce jobs, letting you analyze huge datasets with familiar syntax. Don't mistake it for a real-time database; its power is in high-throughput batch processing, not low-latency queries.
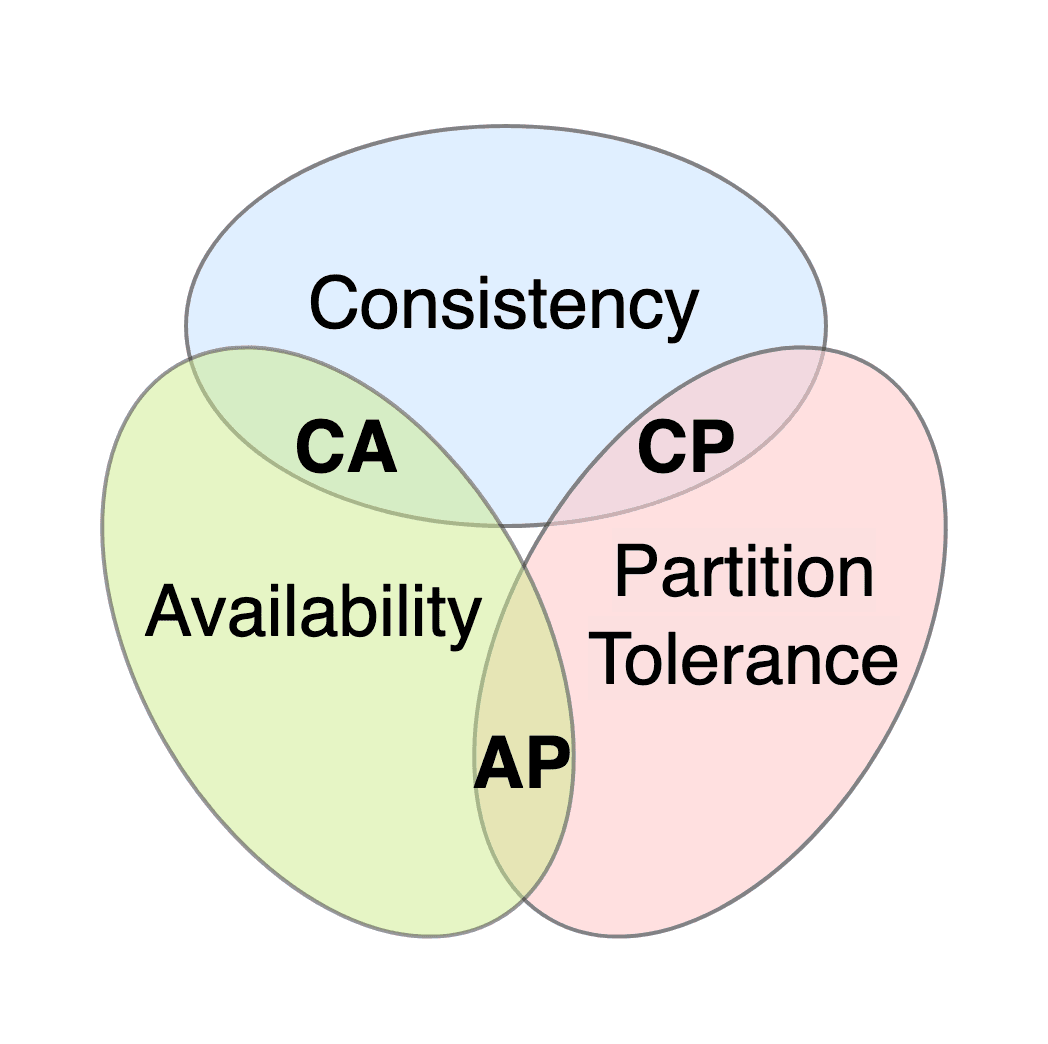
CAP Theorem: Pick Two of Three Guarantees
The CAP Theorem states a distributed system can only have two of three guarantees: Consistency, Availability, or Partition Tolerance. When the network fails (a partition), you must choose: stop responding to ensure data is consistent (CP) or keep responding…
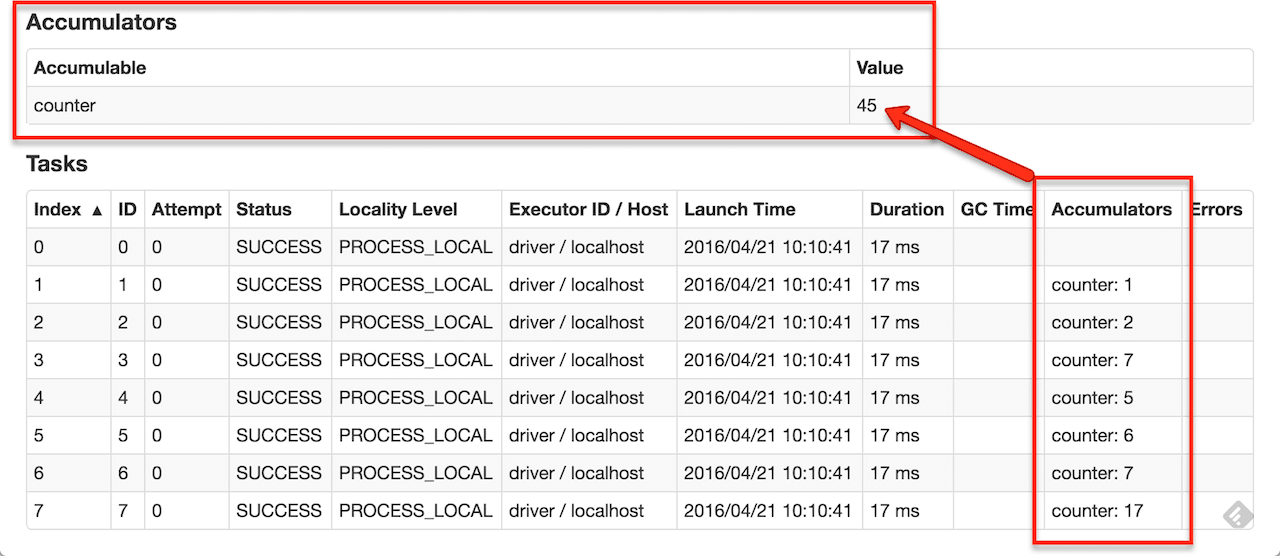
Spark RDDs: Immutable, Distributed Data Collections
An RDD is Spark's core abstraction: an immutable, partitioned collection of items processed in parallel. It's the go-to for low-level, unstructured data tasks. The main footgun is using RDDs when higher-level DataFrames offer better performance.
YARN: Hadoop's Cluster Operating System
YARN acts as the operating system for a Hadoop cluster, separating resource management from job processing. This allows multiple engines like Spark or MapReduce to run on the same hardware.
Markov Decision Process: A Map for Sequential Decisions
A Markov Decision Process models sequential choices with uncertain outcomes. Think of it as a game with states, actions, and rewards, but where your next move is probabilistic.
Q-Learning: Teaching an Agent by Trial and Error
Q-Learning teaches an agent the 'quality' of an action in a given state through trial and error, like training a pet with treats. It's used in robotics for navigation or in games where an AI learns optimal moves.
Named Entity Recognition: Finding the 'Who, What, Where' in Text
Named Entity Recognition (NER) is a smart highlighter for text, automatically finding and tagging nouns like people, places, and organizations. It powers search and extracts structured data from news or support tickets.
Topic Modeling: Finding Themes in Unstructured Text
Topic modeling automatically finds themes in text by grouping words that often appear together. It's used to analyze customer feedback or organize large document sets.
Recurrent Neural Networks: Networks with Memory
An RNN is a neural network with a memory loop, processing sequential data by feeding its own output back in as input. It's used for text generation or time-series analysis where context is key.
Hierarchical Clustering: Building a Family Tree for Data
Hierarchical clustering builds a family tree of your data, not just a single set of groups. It's used when you don't know the number of clusters beforehand, like in biology or market segmentation. The main footgun: early merges are final and can't be undone.
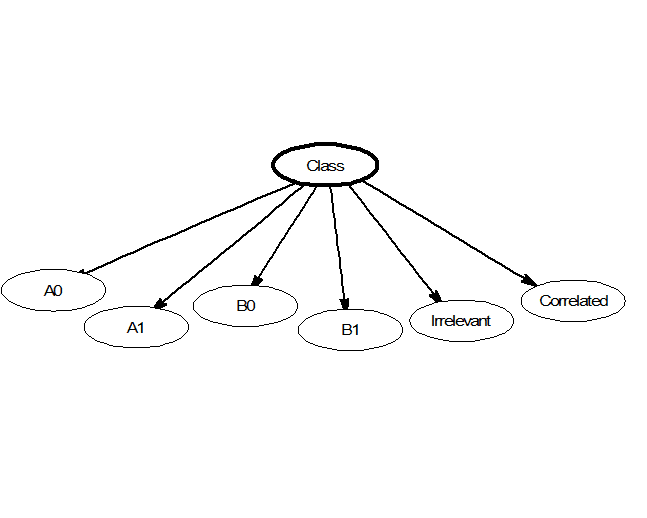
Naive Bayes: Fast Classification by Assuming Independence
Naive Bayes classifies data by assuming its features are unrelated, like judging a fruit's type by color and shape independently. This makes it fast for tasks like spam filtering or real-time predictions. Its core 'naive' assumption is almost always wrong.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles