Concepts in Data Science & Analytics, page 5
Random Forest: Many Weak Learners Make One Strong Model
A random forest asks a crowd of simple decision trees for a prediction and takes the majority vote. This ensemble approach is used for classification and regression, correcting for a single tree's tendency to overfit. The footgun is its lower interpretability.
Ensemble Learning: Bagging vs. Boosting
Ensemble methods combine multiple weak models into one strong one, like a committee outperforming a single expert. Bagging reduces variance; Boosting reduces bias. The footgun: Boosting can overfit noisy data by trying to model the noise itself.
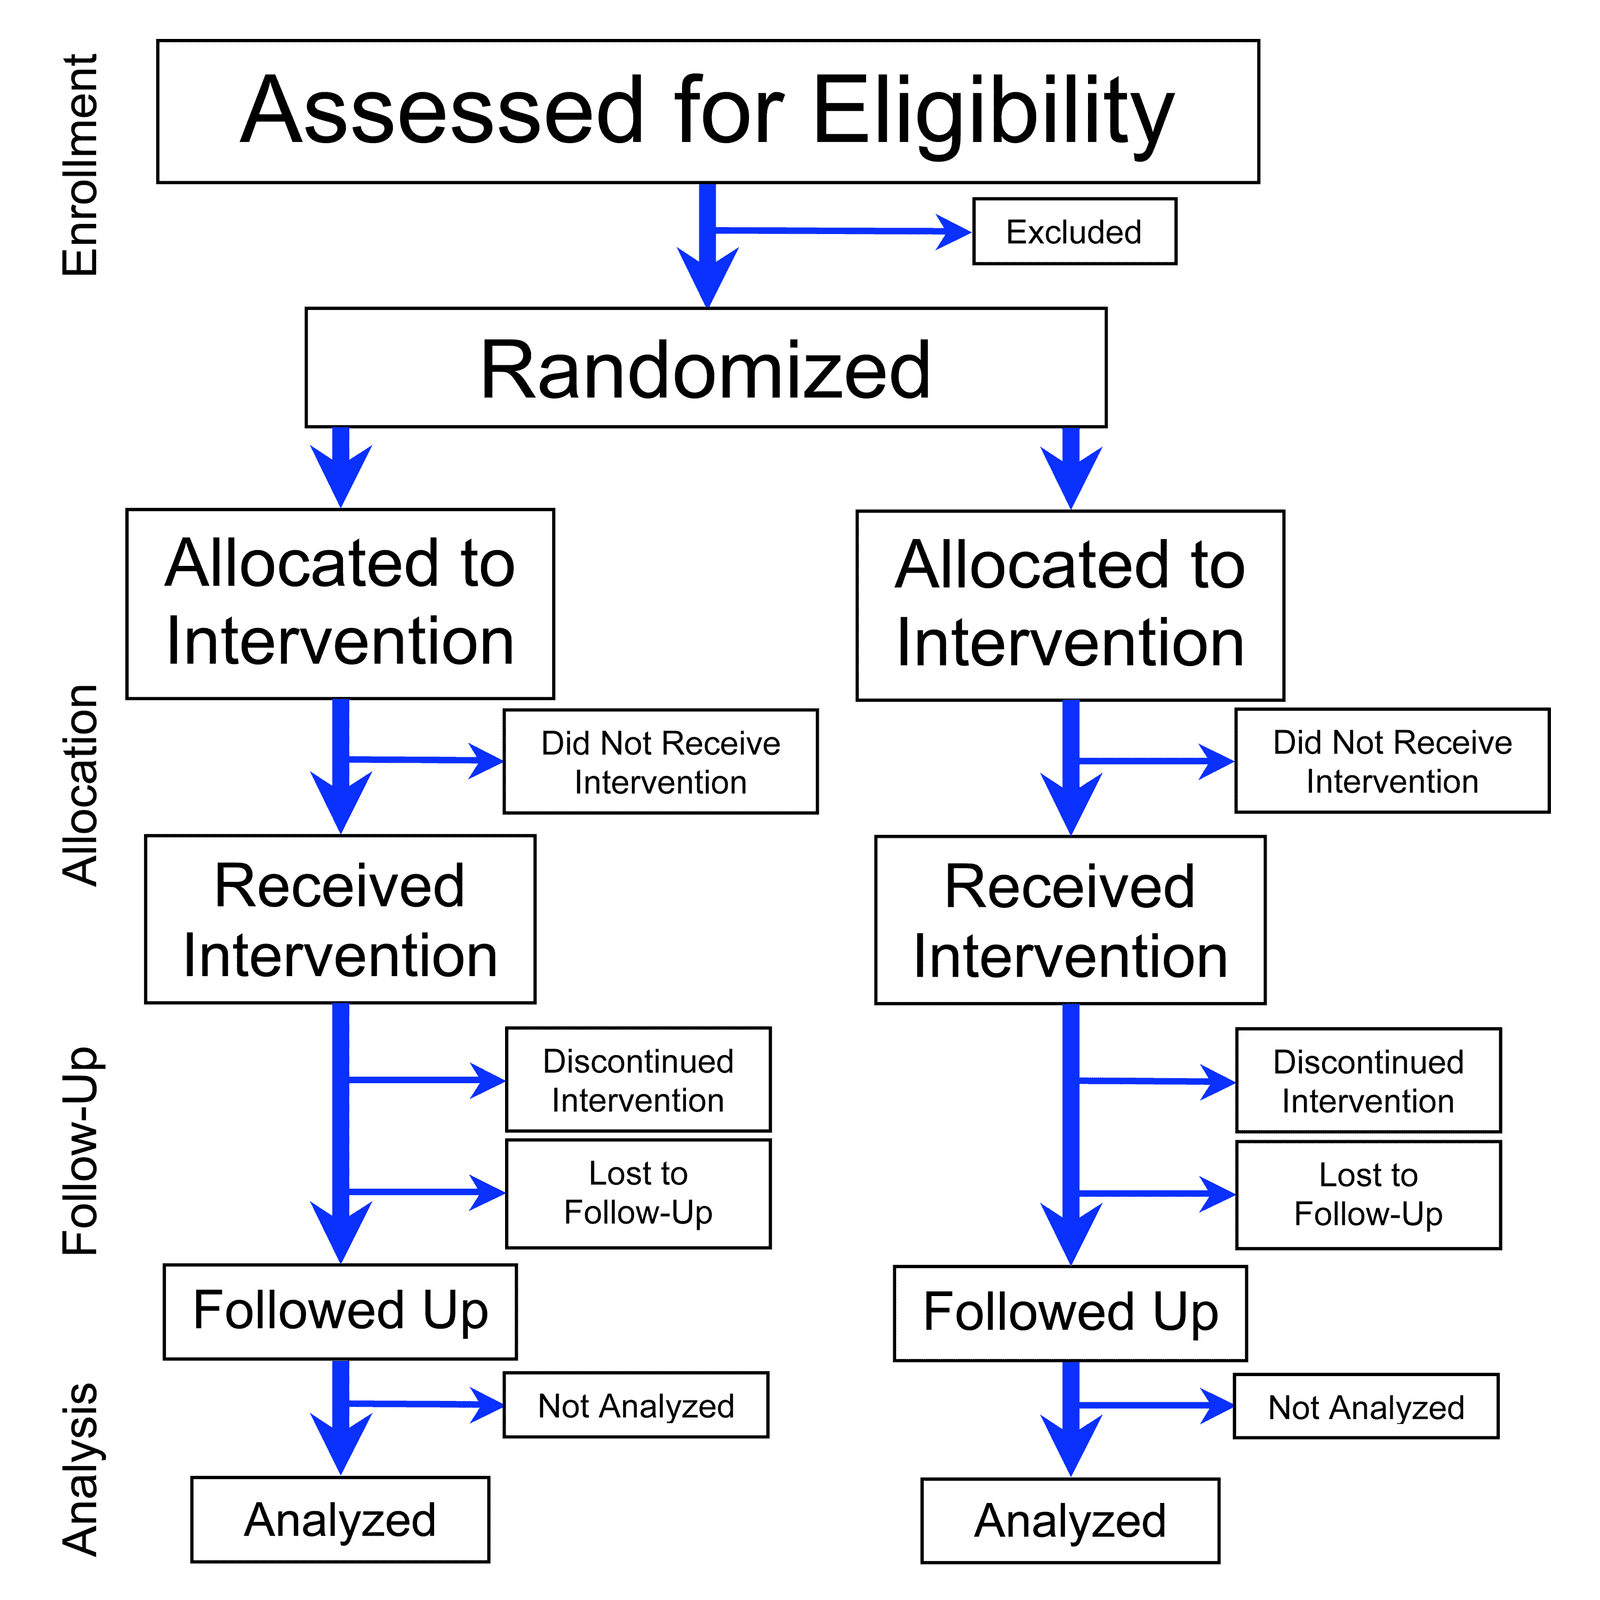
Randomization: Defeating Bias with Chance
Randomization uses chance to assign subjects to groups, isolating the effect you're testing from hidden variables. It's the foundation of A/B tests and clinical trials. The footgun is confusing 'haphazard' selection with true, unbiased randomization.

A/A Testing: Sanity-Checking Your Experiments
A/A testing is a fire drill for your A/B testing system. You run two identical versions of a page to ensure your tools are working correctly before a real experiment. The biggest footgun is panicking at a false positive; 1 in 20 tests will show.
Statistical Power: Is Your Test Strong Enough to Find a Real Effect?
Statistical power is your experiment's ability to detect a real effect. A low-power test is like a fishing net with holes too big—the fish swims right through. This is critical for A/B tests. The footgun is concluding "no effect" from a weak test.
SUTVA: The Assumption That Your Treatment Isn't Leaking
SUTVA assumes your treatment on one person doesn't spill over to affect others, and that the treatment is consistent for all. It's a key assumption for A/B tests, but is violated when one person's vaccine protects their unvaccinated neighbor.
Propensity Score Matching: Simulating a Randomized Trial
Propensity Score Matching creates a 'fair' comparison from observational data, mimicking a randomized trial. It's used to estimate a treatment's effect by matching treated individuals with similar untreated ones.
Causal DAGs: A Map for Cause and Effect
A Causal DAG is a map of your assumptions about what causes what. It helps you spot hidden "confounder" variables that create misleading correlations. Use it before an analysis to decide which variables to control for, ensuring you measure a true effect.

Artificial Neural Networks: Learning from Examples
Think of an ANN as a digital brain that learns from examples, not explicit code. It's a network of simple nodes that adjust their connections to spot patterns. They power image recognition and language translation, but are only as good as their training data.

Word Embeddings: Turning Words into Math
Word embeddings turn words into vectors, where distance equals a difference in meaning. They power features like search relevance and text classification by letting algorithms 'understand' context.
Convolutional Neural Networks: Finding Patterns with Filters
A CNN learns to spot features by sliding optimized filters over data like images, audio, or text. It's the go-to for computer vision, but a common mistake is thinking it's the only modern tool, as transformers sometimes replace it.

Transfer Learning: Don't Train Models from Scratch
Transfer learning means not training a model from zero. You start with a model pre-trained on a large, general dataset, then fine-tune it for your specific task. This is common in image recognition, using a general model to learn a niche classification.
Recurrent Neural Networks: Networks with Memory
An RNN is a neural network with a memory loop, processing sequential data by feeding its own output back in as input. It's used for text generation or time-series analysis where context is key.
Generative Adversarial Network (GAN)
A GAN trains two networks in competition: a generator that fabricates fake samples and a discriminator that judges real versus fake. Their adversarial game pushes the generator toward realistic outputs, enabling image synthesis and data generation without…
Topic Modeling: Finding Themes in Unstructured Text
Topic modeling automatically finds themes in text by grouping words that often appear together. It's used to analyze customer feedback or organize large document sets.
Named Entity Recognition: Finding the 'Who, What, Where' in Text
Named Entity Recognition (NER) is a smart highlighter for text, automatically finding and tagging nouns like people, places, and organizations. It powers search and extracts structured data from news or support tickets.
Q-Learning: Teaching an Agent by Trial and Error
Q-Learning teaches an agent the 'quality' of an action in a given state through trial and error, like training a pet with treats. It's used in robotics for navigation or in games where an AI learns optimal moves.
Markov Decision Process: A Map for Sequential Decisions
A Markov Decision Process models sequential choices with uncertain outcomes. Think of it as a game with states, actions, and rewards, but where your next move is probabilistic.
Transformer Architecture
The Transformer replaces recurrence with self-attention, letting every token directly attend to every other token in parallel. This enables long-range context and fast training on GPUs, making it the backbone of modern large language models and much of…
Large Language Models (LLMs)
An LLM is a massive neural network trained on vast text datasets to perform language tasks. It powers modern chatbots by generating, summarizing, and translating text. The key footgun: biased or inaccurate training data makes its output unreliable.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles