Interview questions in Data Science & Analytics, page 3
How would you evade an advanced anti-bot system while scraping?
Discuss JA3/TLS spoofing, CDP-based browser automation, human-like mouse paths and delays, and session consistency.
Design a scalable, fault-tolerant real-time IoT data ingestion system
This tests separation of edge connectivity, buffering, and processing. A strong answer names an edge gateway, Kafka as the backplane, stream processing, and cold storage, plus backpressure and partitioning.
Handling missing numerical values
Dropping rows is simple but loses data and can bias if missingness is non-random; mean or median imputation keeps rows but shrinks variance and ignores correlations; model-based imputation is…
What is data leakage in preprocessing and cross-validation?
This tests recognition of data leakage through preprocessing statistics. A strong answer defines leakage, describes scaling using global statistics before CV splits, and states transformers must be fit per training fold.
Why is scaling unnecessary for trees but critical for SVM or K-Means?
Tests whether you understand model internals. Trees split on rank order, so scale is irrelevant. SVM and K-Means rely on distance or margin geometry, making magnitude dominate.
How do you prevent future leakage in time-series preprocessing?
This tests temporal causality in feature engineering and validation. Use only past data for lags and rolling windows and enforce a rolling validation split without shuffling. Red flags are random k-fold CV and global standardization leaking future information.
How would you standardize a 500GB dataset that does not fit in RAM?
This tests two-pass statistics for out-of-core scaling. A good answer outlines: first compute mean and variance via sums and counts; second apply z = (x - mean) / std; mention Dask-ML or PySpark. A red flag is averaging chunk-wise means without weighting.
Stemming versus lemmatization in text preprocessing
Stemming chops affixes fast but crudely, yielding non-words; lemmatization maps to real dictionary base forms using POS, slower but accurate; skip both for embedding or transformer models.

Describe the difference between ETL and ELT and when to choose each
Tests transform timing and compute location. ETL cleans data before loading via external engines; ELT loads raw data first, then transforms in the warehouse. Pick ETL when pre-load cleansing is needed, ELT when warehouse compute is cheaper.
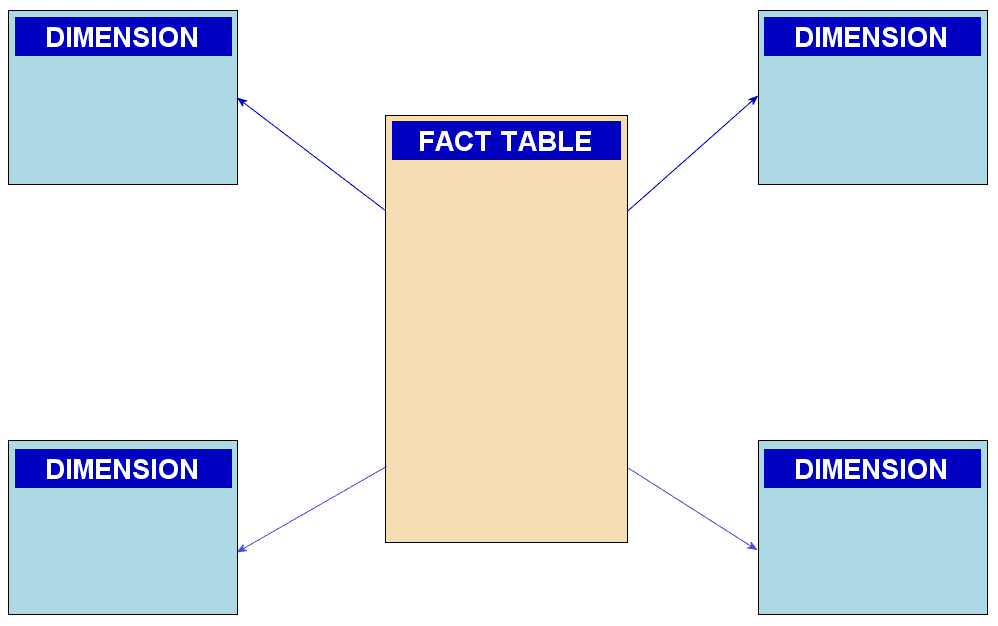
Star schema vs snowflake schema: differences and trade-offs
Tests dimensional modeling: star schemas flatten dimensions for fast joins and simple queries, while snowflakes normalize them to cut redundancy at the cost of extra joins. Red flag: praising snowflake storage savings without admitting query overhead.

What is data pipeline idempotency and how do you design for it?
This tests resilient pipeline design under failure. A strong answer defines idempotency as identical output on repeated runs, highlights safe retries and partial failure recovery, and proposes idempotency keys with atomic writes for daily API loads.
How would you partition a massive user events table?
Tests whether you map query patterns to storage layout to cut bytes scanned. Strong answers pick time-based partitioning for range pruning, cluster by high-cardinality filters, and justify against WHERE clauses.

When is streaming better than batch, and what are its infrastructure challenges?
Tests if you separate low-latency decisions from analytics and know ops pain. Good answer: fraud detection vs batch; cite exactly-once, state recovery, backpressure, schema drift. Red flag: calling streaming faster batch while ignoring backpressure or state.

How would you monitor data quality for a C-level dashboard pipeline?
Designing production data observability for executive dashboards. A strong answer maps freshness SLAs, completeness checks, and distribution drift detection to business impact.
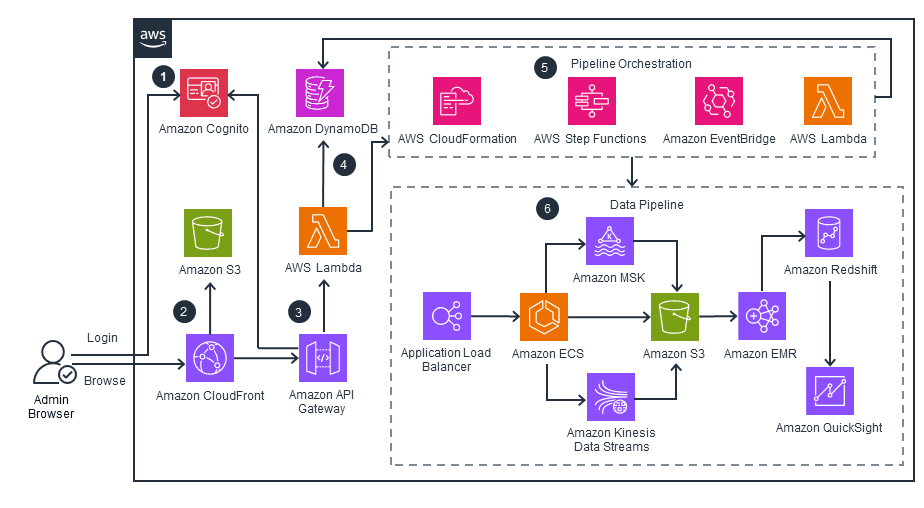
Design a clickstream pipeline from ingestion to data warehouse
Tests data pipeline design under load: buffering, idempotent transform, and warehouse modeling. A strong answer orders ingestion via Kinesis or MSK, Spark EMR sessionization, and Redshift star schemas. Red flag: no buffer and direct warehouse writes.
First steps to identify and handle missing values
Tests systematic diagnosis before imputation. Strong answers visualize nulls, classify MCAR/MAR/MNAR, and contrast mean imputation with KNN, weighing bias versus complexity.
How do you detect and handle outliers in multivariate datasets?
This tests statistical judgment beyond univariate thresholds. A strong answer names multivariate methods like Mahalanobis distance or isolation forests, PCA or pair plots for visualization, and checks for measurement error before removal.

How do you visualize clusters in 100-dimensional numerical data?
Tests PCA versus t-SNE tradeoffs for high-dimensional visualization. Strong answers use PCA first for global variance and outliers, then t-SNE with perplexities 5-50 run to stability. Red flag: interpreting t-SNE cluster sizes or distances as literal metrics.
How does a U-shaped EDA pattern influence feature engineering?
Add age squared or splines; trees handle splits but explicit terms aid linear models.
How would you visualize high-cardinality categorical relationships?
This tests dimensionality reduction when categories exceed roughly fifty levels. A strong answer proposes top-N aggregation with an other bucket and density or hierarchy plots like heatmaps or treemaps. A red flag is scrolling a bar chart or sampling rows.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles