Interview questions in Data Science & Analytics, page 4

Describe your systematic approach to interpreting an 8-feature pair plot
Check 8 diagonals for skew; scan 28 off-diagonals for nonlinear trends, variance patterns, and hue clusters; flag redundancy; spot outliers.
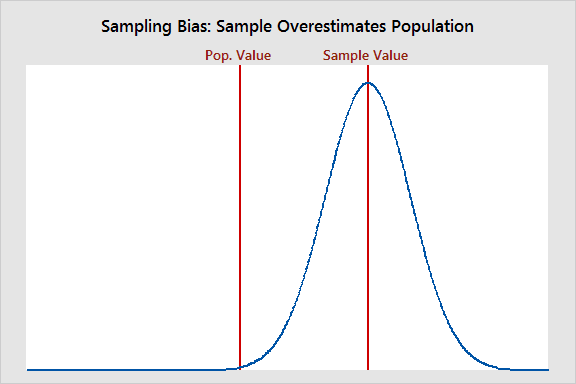
How can EDA and visualization identify dataset bias before modeling?
Tests operationalizing bias detection before modeling. Strong answers compare sample distributions to population norms, audit feature coverage with heatmaps, and track missingness by subgroup. Red flag: citing only class imbalance or ignoring sampling frame.

Explain bias-variance tradeoff and how regularization or tree depth manage it
Tests understanding of generalization error decomposition. Define bias as underfitting and variance as sensitivity to training noise; show regularization and shallow trees trade excess variance for slightly higher bias. Red flag: claiming both can hit zero.

How would feature engineering for categoricals differ for logistic regression versus LightGBM?
It tests model-specific encoding decisions. Logistic regression needs one-hot to avoid false ordinality; tree models like LightGBM use ordinal encoding since splits rely on thresholds, not distance.
Random Forest versus Gradient Boosting
Random Forest trains deep trees in parallel and averages to cut variance; boosting builds shallow trees sequentially, each correcting prior errors to cut bias, often higher accuracy but…

What is cross-validation and why is it more robust than a holdout split?
A single split is noisy and wastes data; k-fold rotates each fold as test, averages scores, and trains on all data.

High ROC-AUC but low PR-AUC: what does this imply?
Tests if ROC-AUC hides imbalance while PR-AUC exposes it. Severe imbalance dilutes FPR across many negatives, inflating ROC-AUC, but precision crashes. Critical for rare positives with costly false positives. Praising the model on ROC-AUC alone fails.
K-Means vs DBSCAN: which for geospatial hotspots?
Tests matching algorithmic assumptions to data structure. K-Means needs K and assumes spheres; DBSCAN discovers arbitrary density shapes and labels noise. Choose DBSCAN for geospatial hotspots because density is irregular.
Interpreting a black-box gradient boosting model
Global tools like permutation importance or aggregated SHAP rank overall feature influence; local tools like per-instance SHAP or LIME explain one prediction; SHAP unifies both via additive…
How do you determine required sample size for an A/B test?
Tests statistical power and experimental design. Name four inputs: baseline conversion rate, minimum detectable effect, alpha (5%), and power (80%), then solve for N. Red flag: "test until significant" or fixed guesses like 1000 users without effect size.
P-value vs confidence interval in an A/B test
A p-value gauges evidence against the null; a 95% CI shows plausible effect sizes and precision.
A/B test: 0.1% lift. Statistical vs practical significance?
Statistical significance says the 0.1% is real; practical significance asks if revenue exceeds engineering cost. Frame with CIs and ROI.
Why not stop an A/B test when it looks significant early?
Tests whether you understand repeated looks inflate false positives. The term is peeking: checking daily can turn a 5% Type I error rate into roughly 15% by day 3. Red flag: citing "low sample size" without stating that early stopping invalidates the p-value.
How do network effects violate A/B tests and how to mitigate them?
Tests SUTVA violations and network experiment design. Answers note treated users alter control outcomes, then propose social-graph cluster randomization to isolate spillovers. Red flag: ignoring peer-to-peer spillover and using user-level randomization.
Analyzing skewed revenue-per-user experiments
Heavy tails inflate variance and slow significance, and the mean is dominated by whales; mitigate via winsorization or capping, log transforms, CUPED variance reduction, or bootstrap and rank tests.

What is Simpson's Paradox and how can it bias A/B tests?
Tests whether you recognize that aggregate trends can reverse within subgroups. A strong answer defines the paradox, gives an A/B example where treatment wins overall but loses in every segment due to skewed allocation, and prescribes stratified analysis.
How would you estimate causal impact using a quasi-experimental method?
DiD with Canada versus Australia; assert parallel trends; validate with pre-period plots and placebo tests.
Explain Regression Discontinuity Design and propose a real-world scenario
Compare units just above and below a threshold for local effects; propose scenario with forcing variable.
Explain vanishing and exploding gradients and common mitigation techniques.
Why deep backpropagation causes diverging gradient magnitudes. Repeated multiplication across layers shrinks or explodes gradients; cite tanh [0,1] range; list ReLU, batch norm, and gradient clipping. Blaming activation choice alone without citing depth.
What is overfitting and how does Dropout prevent it?
Tests generalization intuition: overfitting is low train error but high test error. Good answers say dropout randomly zeros hidden units during training to stop co-adaptation. Bad answers say dropout permanently deletes neurons or just reduces capacity.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles