Intermediate everything in Databases & Architecture, page 6
Delta Lake: Database Reliability for Your Data Lake
Delta Lake adds a transaction log to your data lake, giving you database-like reliability over raw files. This enables ACID transactions, schema enforcement, and unified batch/streaming pipelines.
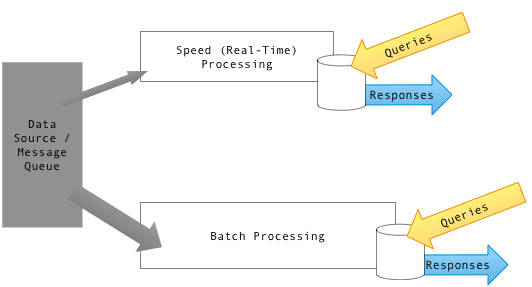
Lambda Architecture: Batch + Stream for Big Data
Lambda Architecture handles massive datasets by combining slow, accurate batch processing with fast, real-time stream processing. It's used for analytics needing both historical and live views.
Schema Evolution: Changing a Live Database Without Outages
Schema evolution is like renovating a house while you live in it: you must change your database's structure without breaking the live application. This is critical when adding or renaming columns.
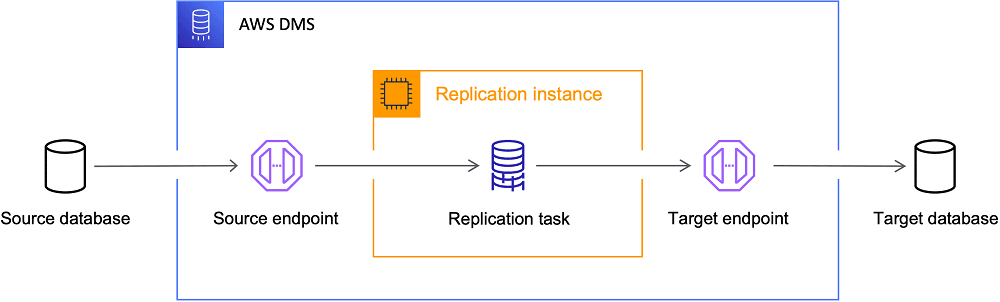
AWS DMS: Your Managed Database Migration Engine
AWS DMS is a managed service for migrating databases. It acts like a replication server you point at a source and target, handling the data transfer. It's used for one-time migrations to AWS or for continuous replication.
Amazon DynamoDB: Scalable NoSQL as a Service
Think of DynamoDB as a database where you trade complex queries for near-infinite, hands-off scaling. It's a managed NoSQL service from AWS for key-value and document data, built for high-performance applications.
Amazon Aurora: AWS's Proprietary Relational Database
Amazon Aurora is a proprietary relational database from AWS, offered as part of the Amazon Relational Database Service (RDS). It provides a managed database solution within the AWS cloud ecosystem, available since October 2014.

Compute & Storage Separation: Scale One Without the Other
This architecture treats your data warehouse (cheap storage) and query engine (expensive compute) as separate services. You can scale compute for peak demand without overprovisioning storage.
ORM Lazy Loading: Defer Queries Until Needed
An ORM's lazy loading fetches related data only when you access it, not with the initial query. This speeds up the first query if you don't need related objects. The footgun is the N+1 problem, where a loop triggers many hidden, slow database queries.
Database Cursors: Row-by-Row Result Processing
A database cursor is an iterator for a query's results, letting you process a large dataset one row at a time. It's for batch jobs on huge record sets that would otherwise crash your app.
SQL Query Builders: Write SQL Without Writing SQL
An SQL query builder is a translator for your database, converting visual clicks or chained code methods into raw SQL. It's used to write safer, database-agnostic code or to let non-technical users build queries. The footgun is generating inefficient queries.
The Object-Relational Impedance Mismatch
The Object-Relational Impedance Mismatch is the friction between how SQL databases see data (tables, rows) and how OO code sees it (objects, inheritance). It's the core problem ORMs solve. The footgun is thinking an ORM makes the database disappear.
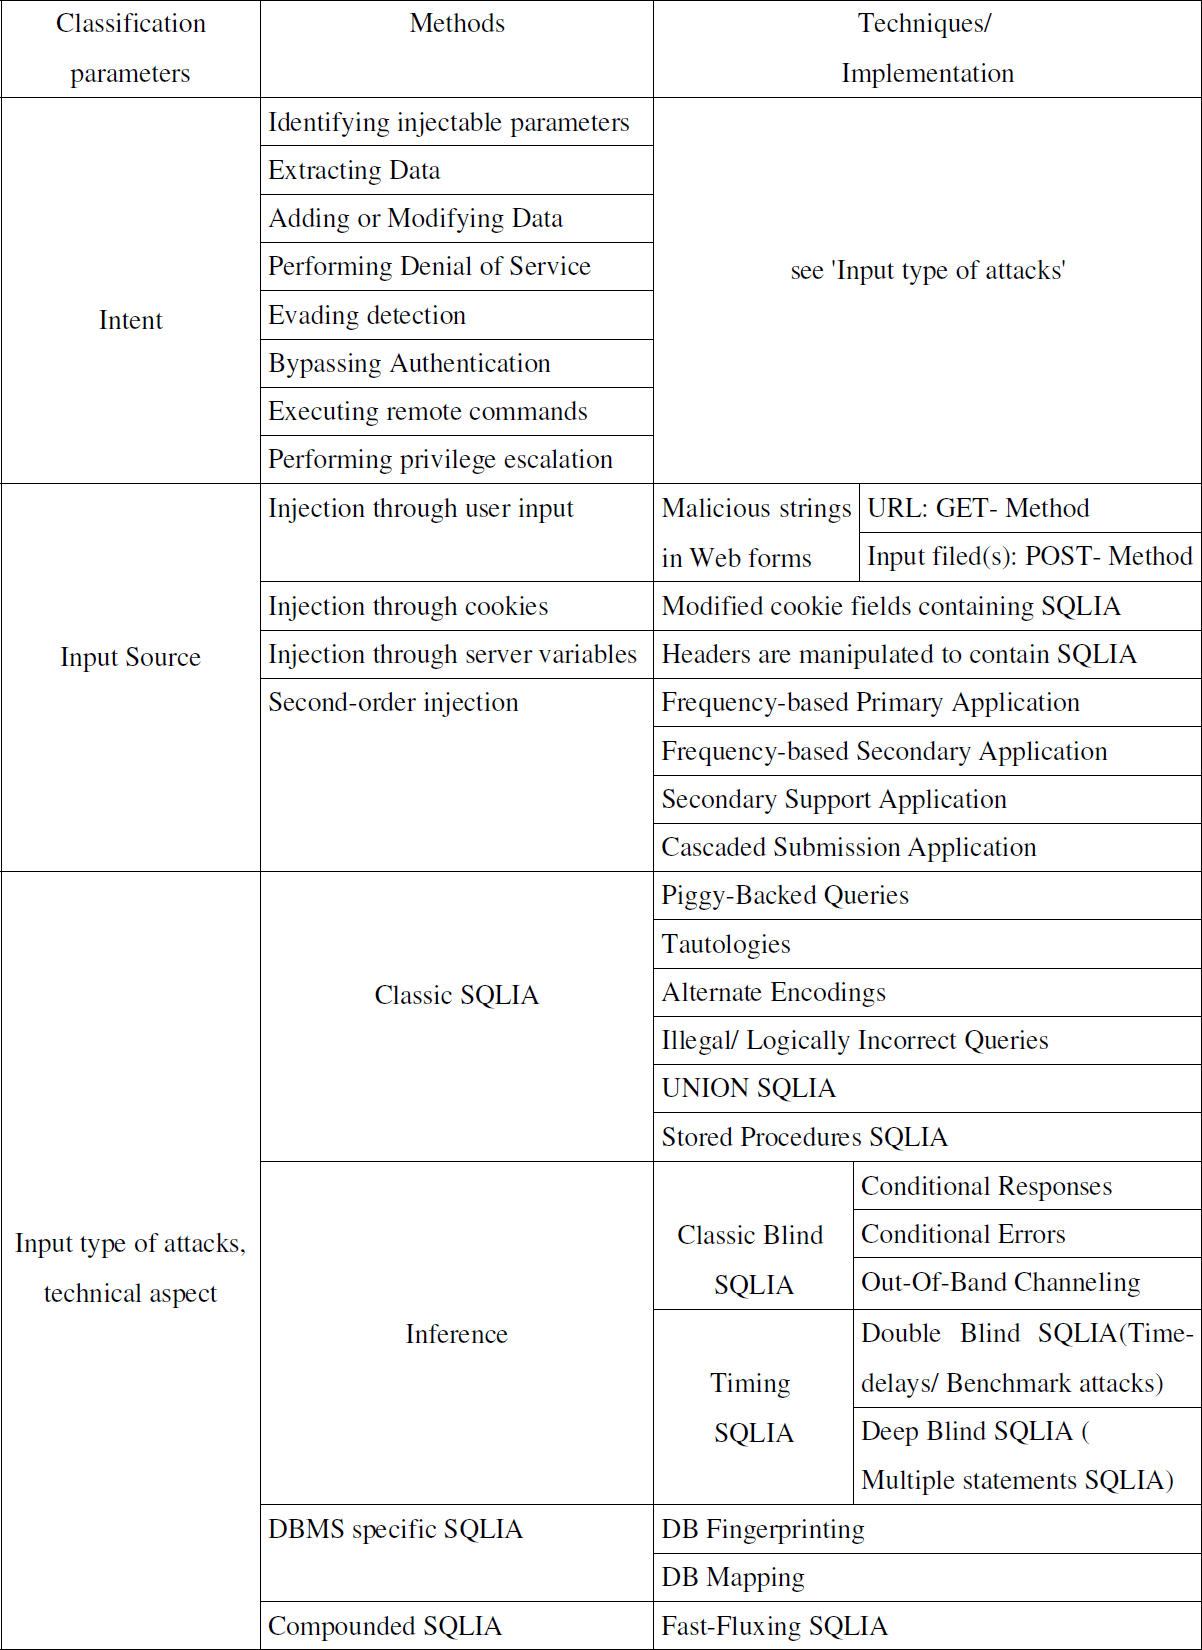
SQL Injection: When User Input Becomes a Command
SQL injection tricks a database into running unintended commands by sneaking them into user input. It's a common attack on websites where user data is directly stitched into SQL queries. The footgun is trusting input; always use prepared statements instead.
Database Encryption: Protecting Data at Rest
Database encryption turns your data into useless gibberish for anyone without the key. It protects sensitive data at rest, like PII or financial records, from direct theft of the database files.
Database Auditing: Your Database's Security Camera
Think of database auditing as a security camera for your data, recording who did what and when. It's essential for security investigations and compliance, but the footgun is treating it as a substitute for access control—it only records a breach, it doesn't…

How Database Indexes Rot and How to Fix Them
Your database indexes rot over time, making queries slower. Frequent writes cause fragmentation (disordered pages) and low page density (half-empty pages), forcing more disk I/O.
Point-in-Time Recovery: Rewind Your Database to a Specific Second
Point-in-Time Recovery (PITR) is a database time machine, restoring data to a specific second, not just the last snapshot. It's crucial for reversing application-level errors.
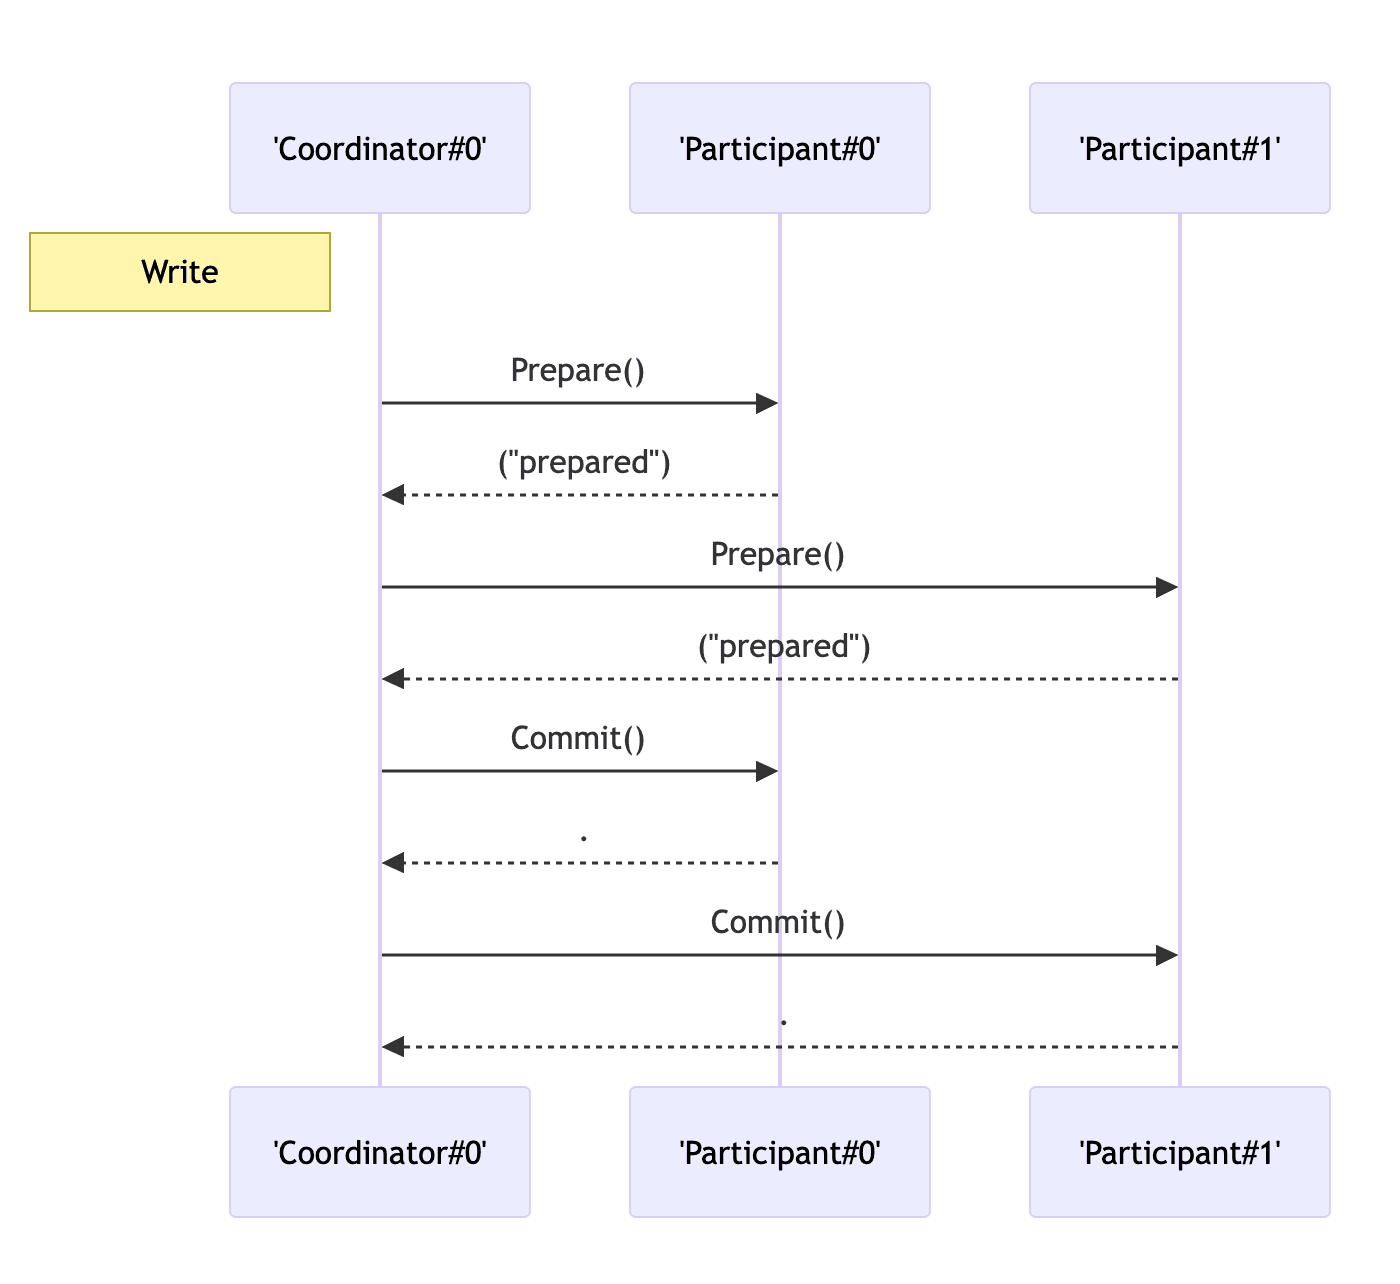
Two-Phase Commit (2PC): All or Nothing, Together
Two-Phase Commit (2PC) ensures a distributed transaction is atomic: all participants either commit or abort together. A coordinator first asks all nodes to prepare (vote), then issues a final commit or abort.
Quorum: How Distributed Systems Agree Without Unanimity
A quorum is a majority vote for distributed systems, letting them operate without waiting for every node. It's used in databases and consensus algorithms to ensure consistent writes. The footgun is setting the quorum too low, risking conflicting decisions.
Consistent Hashing: Resizing Distributed Systems Gracefully
Consistent hashing prevents mass data reshuffling when servers are added or removed. It maps keys to servers on a logical ring, so only a fraction of keys need remapping during a resize. This is crucial for distributed caches to avoid stampedes.
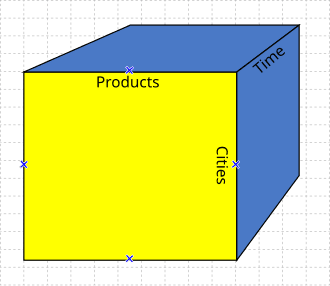
OLAP Cube Operations
OLAP cube operations let you analyze data like a multi-dimensional spreadsheet. Instead of just rows and columns, you navigate dimensions like time and location. Used in business intelligence to answer complex analytical questions.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles