Advanced interview questions in DevOps & Cloud, page 5
Fixing an unmanaged post-mortem action backlog
Generate fewer, higher-leverage items targeting systemic risk; assign owners and dates; integrate into normal planning with explicit prioritization.
What do immutable ConfigMaps and Secrets solve?
Setting immutable true blocks data edits, preventing accidental updates and letting the kubelet skip watches, reducing API server load.

How do you diagnose and fix a Kubernetes OOMKilled application?
Tests cgroup enforcement versus scheduling. A strong answer verifies OOMKilled, compares limits to usage, then rightsizes requests to baseline and limits with headroom. Red flag: confusing requests with caps or blindly raising limits.
Measuring post-incident review effectiveness
Track action-item completion and age, repeat-incident rate, time-to-publish, and MTTR trend.
How do Sealed Secrets enable GitOps for secrets?
Kubeseal encrypts a Secret with the controller's public key into a SealedSecret CR safe for Git; only the in-cluster controller's private key can decrypt it into a real Secret.
Design a zero-downtime Kubernetes Deployment strategy for a stateless microservice
Set RollingUpdate with maxSurge 1 and maxUnavailable 0; use readiness probes to gate traffic; set terminationGracePeriodSeconds and preStop to drain requests.
Reviewing a large-scale cascading outage
Dedicated facilitator, cross-team timeline reconciliation, map cascade chains and multiple contributing factors, layered action items.
Serverless functions with a relational database
Concurrent function instances each open connections and exhaust the database's bounded pool; fix with a connection proxy or pooler, init-phase reuse, or capped concurrency.
High-throughput serverless stream processing
Partition by key for per-user ordering, use a sharded log with batched consumers for backpressure, and tune batch size and shards for cost.

Canary vs shadow deployments: use cases and requirements
This tests whether you distinguish user-facing rollouts from invisible duplication. Canary routes some real users to new code to limit blast radius; shadow mirrors traffic to an isolated clone to test performance without user impact.
Design a centralized auto-remediation platform
Event ingestion, a rules engine mapping alerts to playbooks, a sandboxed execution runtime, and guardrails like dry-run, rate limits, and rollback.
Why is a Pod with a PVC stuck Pending?
PVC may be unbound from missing StorageClass, no matching PV, mismatched access mode or size, zone or capacity limits, or WaitForFirstConsumer; diagnose with describe on Pod and PVC plus events.
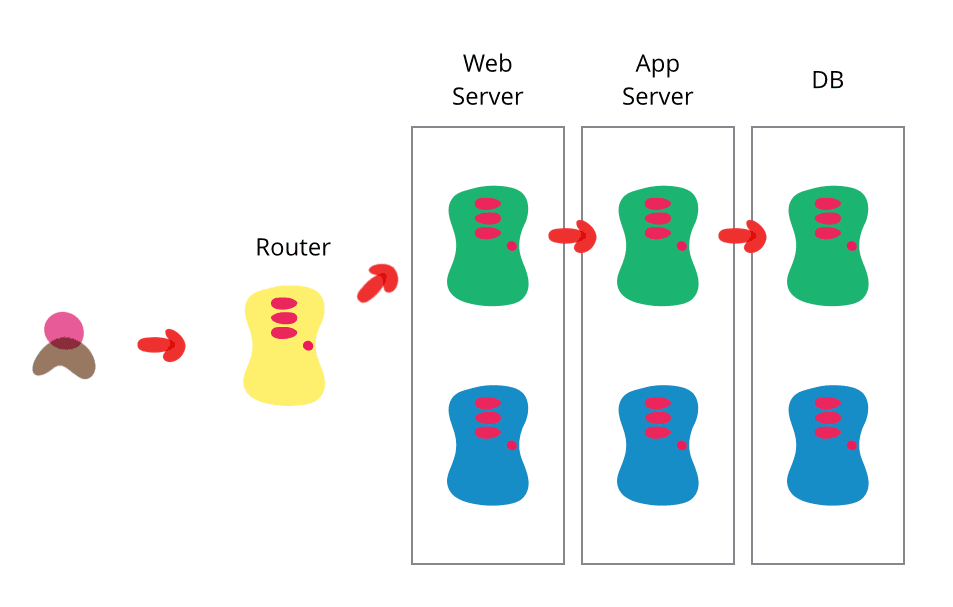
Blue/green deployment fails during switch-over with partial decommissioning; recovery and process changes?
Tests whether you can recover when a blue/green rollback path is compromised. Strong answers stop the bleed, revive blue if possible, and mandate keeping blue fully warm until green is stable. Red flag: "just roll back" ignoring partial decommissioning.
Measure ROI of toil reduction efforts
Track toil hours, percent of time on toil, incidents auto-resolved, and engineer cost saved, then frame as ROI and risk reduction.
How does a StatefulSet recover a Pod after node failure?
Node goes NotReady, Pod is marked for deletion, the same-ordinal Pod is recreated and reattaches its existing PVC from volumeClaimTemplates, preserving data; safety needs the old Pod confirmed…

How do you deploy a hotfix during a multi-stage canary release?
Dark-launch the fix to the canary cohort, preserve metrics, then jointly promote.
How do you resize a live PersistentVolume?
Edit the PVC's requested size upward; the StorageClass must set allowVolumeExpansion true and the CSI driver must support expansion, ideally online so no Pod restart is needed; shrinking is not allowed.
Strategy for large multi-team IaC projects
Versioned reusable modules, state split per environment and component, promotion of identical code via variables, and externalized secrets.
Monitoring with SLOs and error budgets
Define SLIs from the user's view, set SLO targets, derive an error budget, and alert on burn rate rather than raw thresholds.
Auto-rollback on failed blue-green cutover
Shift traffic gradually behind a smart router, use deep health checks plus real SLI monitoring, and auto-revert to blue on breach while blue stays warm.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles