Intermediate interview questions in DevOps & Cloud, page 9
Partitioning order events in a data lake
Partition by the columns queries filter on, typically date hierarchy and category, balancing granularity to avoid too many tiny files.
Mitigating risk from an unproven external dependency?
Timeouts and circuit breakers to fail fast, bulkheads to isolate resources, fallbacks or cached/degraded responses.
Diagnosing and fixing data skew in Spark
This is data skew, caused by uneven key distribution concentrating rows on few partitions; mitigate with salting, broadcast joins, repartitioning, or adaptive execution.
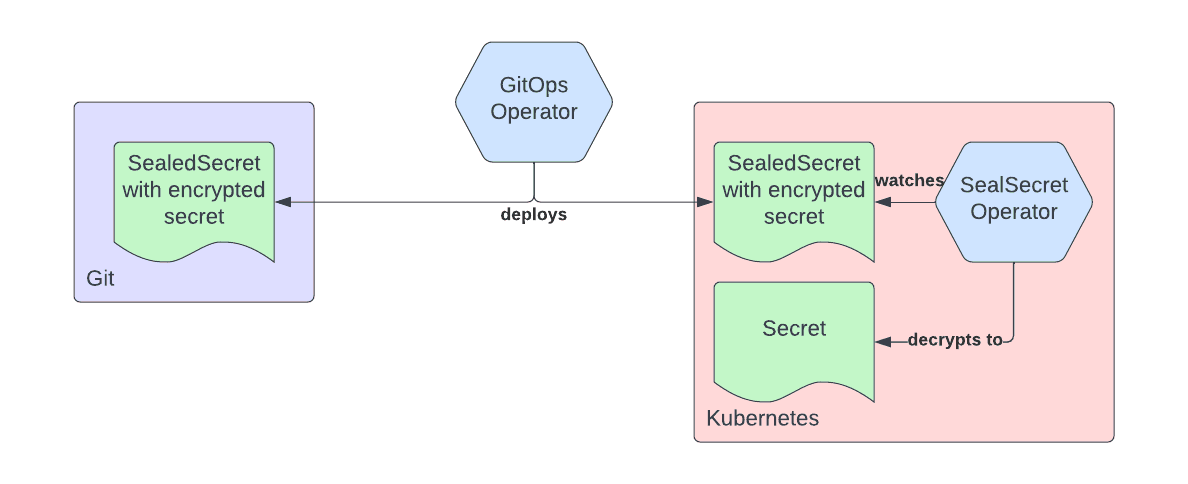
How do you secure secrets in a GitOps repository?
Tests whether you treat Git as source of truth while excluding plaintext credentials. A strong answer covers encrypting at rest with SOPS or Sealed Secrets, external stores like Vault, and operator workflows.
Zero-downtime index migration on a hot table?
Build the index concurrently to avoid table locks, run off-peak with monitoring, and keep it reversible since dropping an index is cheap.
Handling late data in streaming windows
Use event-time windows with watermarks to bound lateness, allow a grace period before finalizing, and route data later than that to a side output.
Two common GitOps repository layouts for multiple environments
Tests GitOps state-store trade-offs beyond single-cluster demos. Contrast a monorepo with directory overlays against repo-per-env; weigh polling overhead, blast radius, and promotion flow. Recommending branch-per-env destroys immutability and invites drift.
Idempotency in data ingestion pipelines
Idempotency means re-running a step yields the same result with no duplicates; it matters because retries and at-least-once delivery are inevitable; achieve it with deduplication keys or upserts.
Automate a canary release with a 1% 5xx error threshold
This tests wiring an SLO into an automated canary loop. A strong answer covers traffic splitting via a mesh or ingress, an analysis query to Prometheus for 5xx rate, and auto-promote or abort logic.
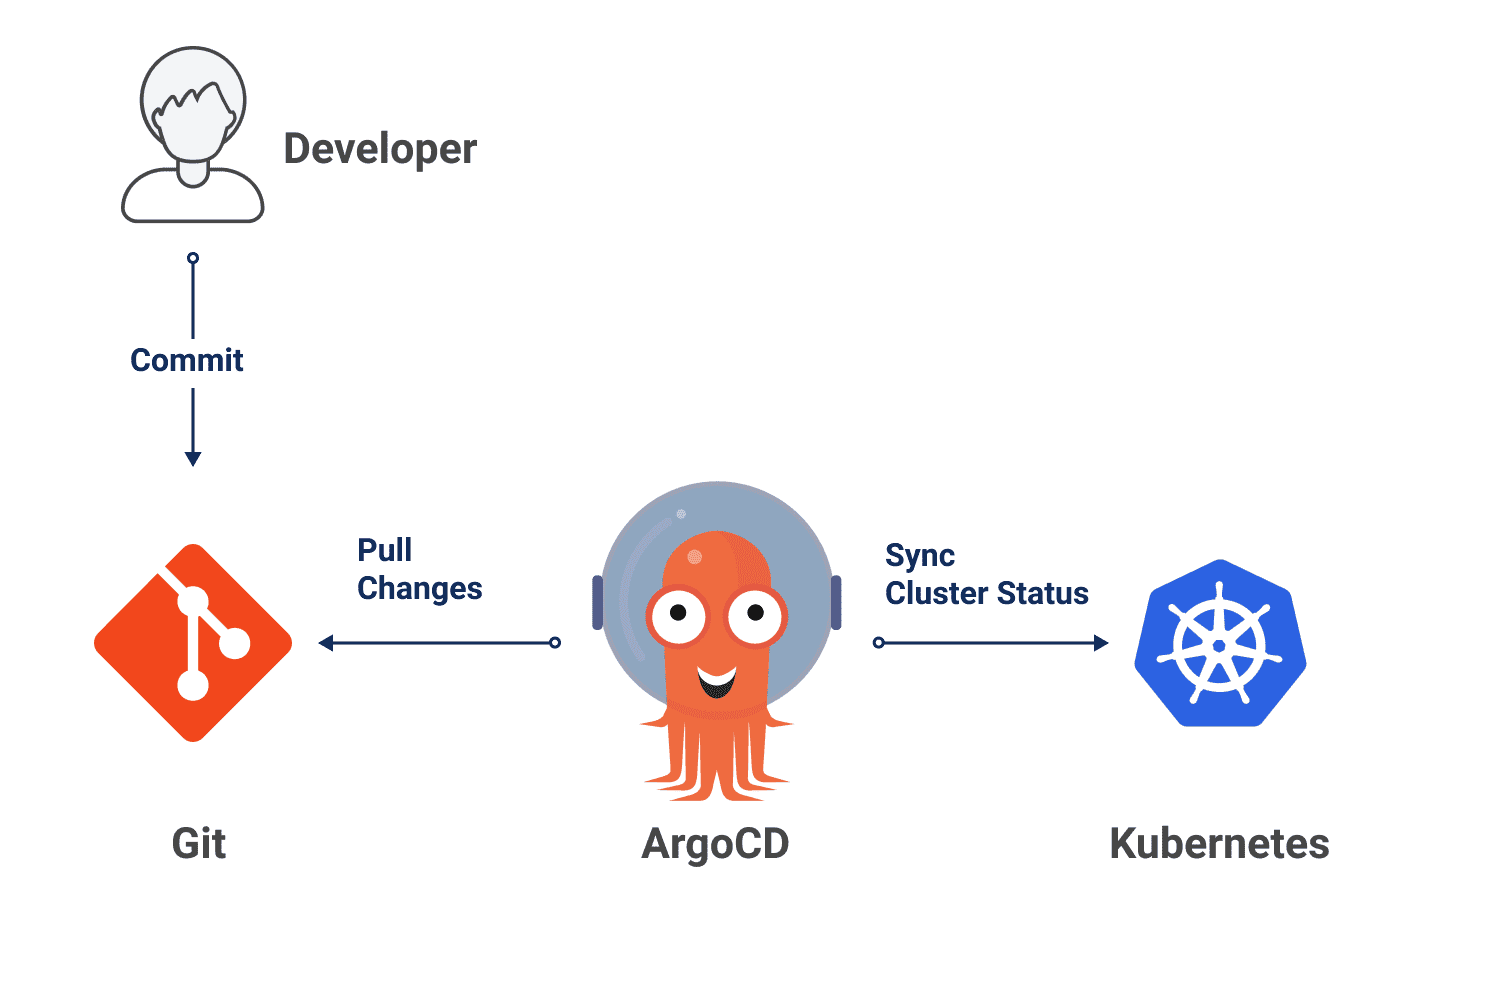
What is configuration drift in GitOps and how do tools handle it?
This tests declared and actual state and GitOps reconciliation. A strong answer defines drift as out-of-band changes, notes auditability, and contrasts self-healing sync with read-only detection. A red flag is suggesting manual patches rather than fixing Git.
Auto-discovering app pods for Prometheus scraping
Use kubernetes_sd_configs with role pod, relabel on pod annotations like prometheus.io/scrape to filter, and set path and port; with the Operator use a PodMonitor or ServiceMonitor.
EFK centralized logging architecture
Fluentd runs as a DaemonSet collecting node container logs, parses and forwards to Elasticsearch for indexed storage, and Kibana queries and visualizes them.
PromQL for top 5 CPU-consuming pods
Apply rate() to the counter over 15m, sum by pod to combine containers, then wrap in topk(5); rate handles counter resets.
Alerting on under-replicated Deployments
Write an alerting rule comparing kube_state_metrics available vs desired replicas with for: 5m, Prometheus evaluates and fires to Alertmanager, which dedupes/routes/notifies.
Deploying a real-time inference endpoint
Package the model artifact and inference code in a container, choose instance type and autoscaling, configure the endpoint with health checks, and plan safe rollout like canary plus monitoring.
How do you run your first production chaos experiment?
Pick a low-risk known weakness, define a measurable hypothesis, brief stakeholders and on-call, run small with an abort, then analyze and fix.
Inference performance bottlenecks on Lambda
Cold starts loading the model, memory and CPU limits, no GPU, and package size dominate; mitigate with provisioned concurrency, loading the model once outside the handler, smaller models, and right-sized…
What is distributed tracing in microservices?
A trace is a tree of spans tied by trace and span IDs, propagated via headers like W3C traceparent.
Why does 200ms latency drop requests? Diagnose it.
Little's Law shows added latency raises in-flight requests, exhausting the thread or connection pool; check pool saturation, timeouts, and retries.
How would you build CI/CD for an ML model?
Data and model versioning, automated training plus evaluation gates, model registry, deployment with monitoring and retraining triggers.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles