Intermediate everything in DevOps & Cloud, page 17
Git Tags: Immutable Milestones for Release History
A Git tag is a permanent bookmark on a commit, usually marking releases like v2.0. Annotated tags store author, date, and GPG signatures to anchor deploy pipelines.
Load Balancing Algorithms: How to Pick a Server
Load balancing algorithms are the rules a client uses to pick one server from a pool of identical backends. They're used by web proxies routing user traffic and by microservices calling each other.
Post-Incident Review: Learning from Failure, Blamelessly
A Post-Incident Review (PIR) is a blameless process to learn from an outage, not to assign blame. Use it after a production incident to identify systemic flaws and create action items to prevent repeats.
Escalation Policy: When to Stop Shipping and Start Fixing
An escalation policy is a pre-agreed plan for when to divert engineers from feature work to fix reliability. When a service's error budget burns too fast, the policy's thresholds trigger specific actions. The footgun is thinking a quick rollback is enough.
Time-Series Compression: Storing More with Less
Time-series compression stores data more efficiently by saving the *difference* between consecutive points, not the full values. It's key for managing terabyte-scale monitoring and IoT data, often saving over 90% on storage.
Service Maps: A Live Blueprint of Your Architecture
A service map is a live blueprint of your distributed system, generated from telemetry data. It visualizes service dependencies and health, letting you instantly see an incident's blast radius instead of hunting through Slack for tribal knowledge.
Capacity Planning: Don't Run Out of Room
Capacity planning matches your system's resources to user demand, crucial for handling traffic spikes or budgeting cloud spend. The main footgun is planning for theoretical 'design capacity' instead of realistic 'effective capacity' which accounts for…
Shared Ownership Model: Bridging the Dev/Ops Divide
The shared ownership model ends the tug-of-war between developers wanting to ship and operations teams wanting stability. Both teams share responsibility for service quality, using SLOs as a common language.
SRE Team Topologies: Organizing for Fast Flow
Team Topologies structure teams to speed up value delivery by organizing around the software itself. This model helps scale product organizations, adopt cloud-native architectures, or build a platform engineering function.
Chaos Mesh: Orchestrated Failure for Resilient Systems
Chaos Mesh is a disaster-as-a-service for Kubernetes. It lets you inject failures like network latency or pod kills to test system resilience. Use it to find weaknesses before they impact users, but be warned: its job is to break things, so scope experiments…
Resource Exhaustion: Starving a System to Death
A resource exhaustion attack is a denial-of-service tactic that starves a system by consuming all of a finite resource like CPU or database connections. It exploits missing rate limits or quotas.
Latency Injection: Testing How Your System Handles Slowdown
Latency injection intentionally slows down parts of your system to test its resilience. Use it to validate timeout configurations and circuit breakers before a real network lag causes a cascading failure. The footgun is injecting unrealistic delays.
N+1 Redundancy: One Spare for the Whole System
N+1 redundancy is like having one spare tire for your whole car. You have N active components and one shared, passive backup. It's used in server racks or power supplies for high availability without doubling costs.
Service Discovery: How Services Find Each Other
Instead of hardcoding IP addresses, services ask a central registry for the live address of other services they need to call. This is crucial in dynamic microservice environments where IPs change constantly.
Failover: Automatic Recovery When Things Go Wrong
Failover is your system's automatic plan B. When a primary component fails, a standby takes over instantly without human intervention. It's essential for high-availability systems. The footgun is assuming the standby is perfectly in sync; it might not be.
Rate Limiting: Your API's Bouncer
Rate limiting acts as a bouncer for your API, controlling traffic to protect your service. It's used on public APIs to prevent abuse, ensure fair usage, and defend against denial-of-service attacks.
Graceful Degradation: Failing Better, Not All at Once
Instead of total failure, graceful degradation lets a system shed non-essential features to stay partially available. It's a fault tolerance strategy for when a component fails, ensuring core functions survive. The footgun is not defining what's 'core.'

Performance Budgets: Set Limits to Stay Fast
A performance budget is a hard limit on metrics like bundle size or load time, acting as a guardrail against regressions. It's used in CI/CD to fail builds that exceed size limits or in monitoring to alert when load times degrade.
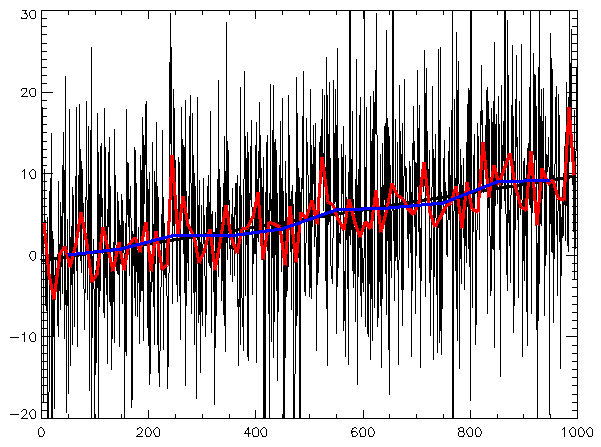
Time-Series Forecasting: Predicting the Future from the Past
Time-series forecasting uses past data points, ordered by time, to predict future values. It's used for capacity planning and financial modeling. The footgun is assuming past trends will hold, as sudden system changes can invalidate all predictions.
Scalability Testing: Will More Hardware Fix It?
Scalability testing answers 'Will more hardware fix it?' by measuring how performance improves when you add resources. The common footgun is confusing it with load testing, which just finds the breaking point under a given load.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles