Intermediate everything in DevOps & Cloud, page 18
Soak Testing: Finding Bugs That Only Time Reveals
Soak testing is like running a marathon, not a sprint, to find bugs that only time reveals. It applies a typical production load over a long period to uncover slow memory leaks or resource exhaustion. The footgun is confusing it with stress testing.
Quality Gates: Your Automated Release Checklist
A quality gate is an automated checklist that decides if code is ready for release. It runs in your CI pipeline, blocking merges or failing builds if metrics like code coverage or bug counts don't meet predefined standards.
Feature Flags: Ship Code Now, Release It Later
Feature flags are like light switches for your code, letting you turn features on or off in production without a new deployment. This enables canary releases and A/B tests. The main footgun is letting old flags accumulate, creating a maze of dead code.
Continuous Delivery: Ship Reliably, Anytime
Continuous Delivery (CD) makes software releases a boring, routine event. Your codebase is always in a deployable state, allowing you to ship small, incremental updates reliably and at any time. The footgun is confusing it with Continuous Deployment.
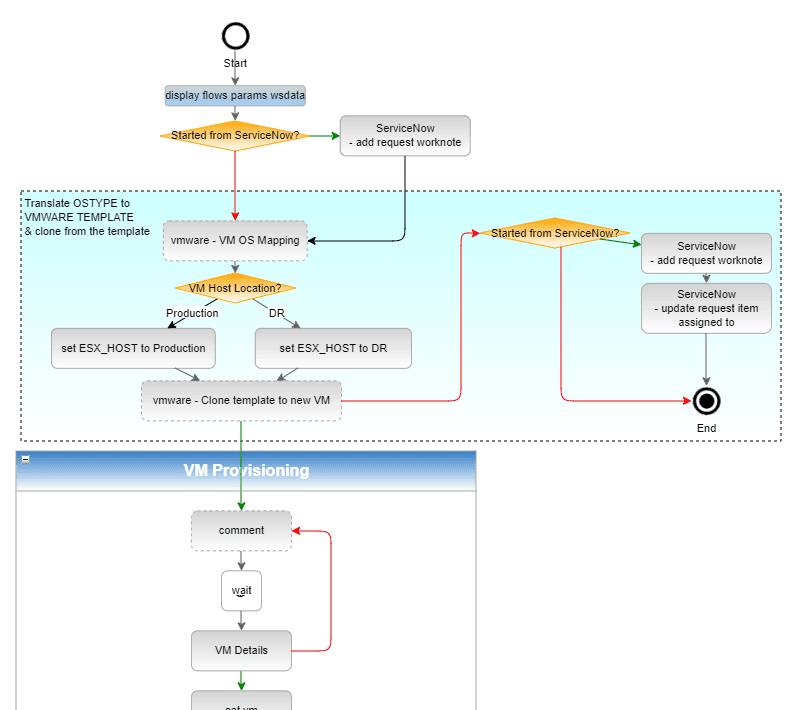
Executable Runbooks: Code, Not Just Checklists
An executable runbook turns a procedural document into an automated script. Instead of reading steps, you run them. It's used for incident response or maintenance, ensuring consistency. The footgun is not making them idempotent, which can worsen an outage.
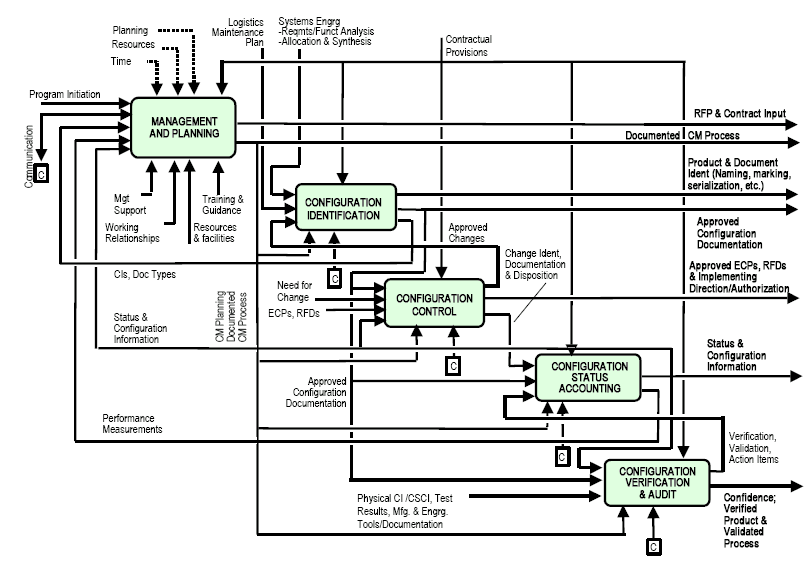
Configuration Management: Enforcing Desired State
Configuration Management treats your system's setup as code to prevent "configuration drift." It's used to reliably provision servers, deploy apps, and manage fleets, ensuring every component matches its intended design and is reproducible.
Hindsight Bias: The 'Knew-It-All-Along' Postmortem Trap
Hindsight bias makes past failures seem obvious. In postmortems, this leads to blaming engineers for not seeing what's now clear, instead of fixing the system. The footgun is judging past decisions with present knowledge, which hides real systemic flaws.

Swiss Cheese Model: Layered Defenses Against Failure
Think of system defenses as slices of Swiss cheese. An accident happens only when the holes—weaknesses in each layer—align. It's used in post-mortems to see how small failures combine into a major outage.
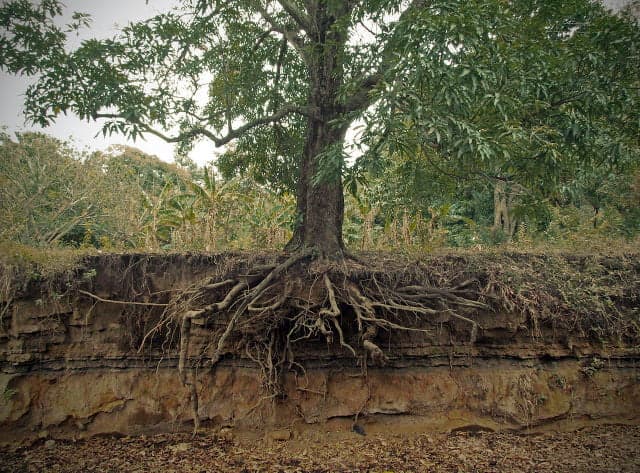
Beyond 'Root Cause': Proximate vs. Contributing Factors
A proximate cause is an incident's final trigger, while contributing factors are the conditions that made it possible. This helps post-mortems move beyond blame to find systemic risks.
5 Whys: Find the Root Cause, Not Just the Symptom
The 5 Whys technique digs past symptoms to find a problem's true root cause. It's used in postmortems to understand system failures by repeatedly asking "Why?". The footgun is stopping too early or blaming people instead of broken processes.
Public Status Page: Your System's Voice During an Outage
A public status page is a dedicated site for communicating your service's health, turning "is it down?" support tickets into a single source of truth. It's used to report outages, degradation, and scheduled maintenance for public-facing services.
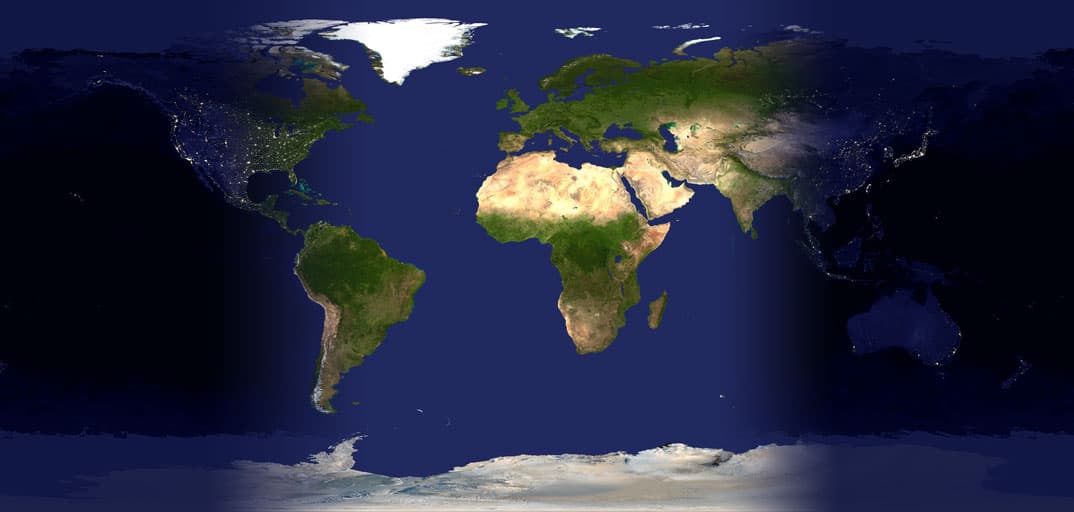
Follow-the-Sun: A Global Relay Race for Work
Follow-the-sun is a global relay race for work. Teams hand off tasks to the next timezone as their day ends, enabling 24/7 coverage without requiring overnight shifts. The footgun is a poor handoff, where lost context erases all the time savings.
ChatOps: Your CLI Inside Your Chat Room
ChatOps moves your command-line tools into your team's chat, making operations a spectator sport. Instead of a solo SSH session, you run commands via a bot for all to see. Use it for deployments and status checks. The biggest footgun is security.
The Incident Commander: Direct the Response, Don't Debug
The Incident Commander (IC) is a conductor, not a soloist. During an outage, they coordinate the response, delegate tasks, and manage communication, not fix the bug themselves. This prevents chaos from uncoordinated heroics.
Mean Time To Repair (MTTR): Measuring Your Fix Velocity
MTTR measures how quickly your team can fix a problem once active work begins. It's the 'wrench time' of incident response, not total outage duration. SREs track it to gauge runbook and diagnostic effectiveness.
Mean Time to Acknowledge (MTTA): Your First Response Clock
MTTA measures the time from an alert firing to a human acknowledging it. It's about reaction speed, not fix time. On-call teams use this to ensure issues are seen quickly, minimizing downtime.
Telemetry Correlation: Connecting Dots in Distributed Systems
Telemetry correlation links logs, metrics, and traces from a single user request into one coherent story. It works by propagating a shared context, like a unique ID, across all services involved.
Downsampling: Trading Granularity for Speed in Time Series Data
Downsampling trades resolution for speed by summarizing old, high-granularity metrics into coarser ones. This makes long-range queries faster and cheaper, common in systems like Thanos for long-term Prometheus data.
Elasticsearch: The Search Engine in the ELK Stack
Elasticsearch is a distributed search engine for querying massive, schema-free JSON datasets via an HTTP API. It's the core of log analysis platforms like the ELK stack, enabling fast search over terabytes of logs.
OpenTelemetry Resource: The 'Who' of Your Telemetry
An OpenTelemetry Resource is the return address for your telemetry, describing the service instance that produced it. It attaches stable context like service name and version to every signal, enabling filtering.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles