Advanced interview questions in LLMs & Generative AI
Explain positional encodings in Transformers and their necessity
Explain encodings inject order into embeddings; cite sinusoidal or learned vectors.
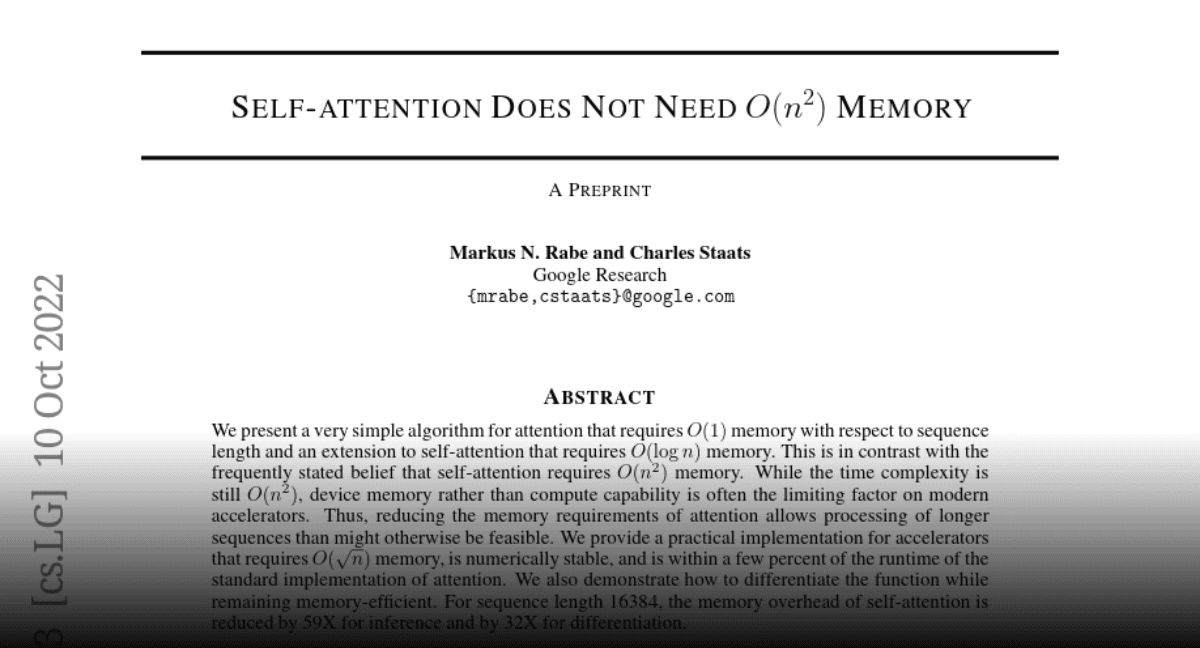
Why is self-attention O(n^2) and what are the implications?
Tests the attention matrix bottleneck. Strong answers note QK^T yields an N×N matrix, creating quadratic compute and memory that blocks long documents and high-res images. Red flag: confusing model size with activation memory.
Layer Norm and Residuals in Transformer Blocks
Residuals preserve gradient flow, layer norm stabilizes activations per token, and it beats batch norm because it is independent of batch and sequence length.
FlashAttention and IO-Aware Attention
FlashAttention is IO-aware, tiling and fusing attention in fast SRAM to avoid materializing the n-by-n matrix in slow HBM.
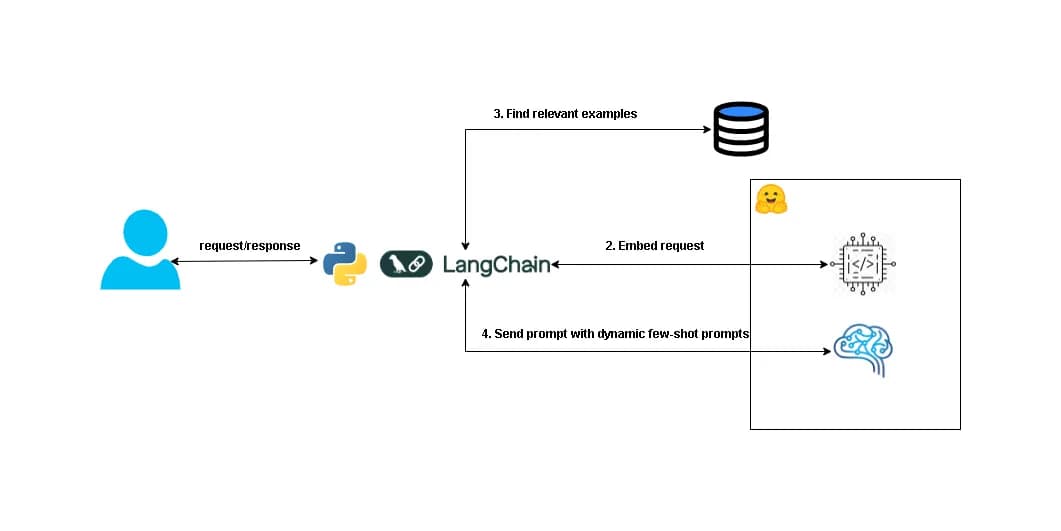
Design dynamic few-shot example retrieval from a vector database
Tests RAG-style prompt engineering with semantic retrieval and latency. Use shared embeddings, approximate nearest neighbors with metadata filters, diversity reranking, and token-bounded prompt templates.

What does the KL-divergence penalty do in RLHF PPO, and if zeroed?
It tests RLHF reward hacking awareness. The KL penalty anchors PPO to the reference model to stop mode collapse; zeroing it causes over-optimization against the proxy reward model, yielding incoherent outputs.
Direct Preference Optimization explained
DPO reparameterizes the RLHF reward in terms of the policy itself, turning alignment into a simple classification loss on preference pairs with no separate reward model or PPO.
Hybrid search and re-ranking for retrieval
Hybrid search fuses dense semantic and sparse keyword signals to catch exact terms dense misses; a cross-encoder re-ranker rescoring top-k boosts precision.
Identify RAG latency bottlenecks and propose optimizations
This tests systems thinking across the RAG pipeline. A strong answer names four bottlenecks—embedding, search, chunking, and generation—and pairs each with caching, index tuning, and distillation. Red flag: GPU scaling without indexing fixes.
How would you architect a multi-turn conversational RAG system?
This tests memory and query reformulation design beyond single-turn RAG. A strong answer covers 5-10 turn windows, LLM-based rewriting with coreference resolution, hybrid fallbacks, and summarized memory.
Securing tool-using LLM agents
Name indirect prompt injection, data exfiltration, and unsafe tool execution, then defend with sandboxing, least-privilege scoped tools, input/output filtering, and human-in-the-loop on risky actions.
Designing an agent that resolves ambiguity
Detect ambiguity, gather evidence with the contact API, resolve relative time deterministically, ask the user only when genuinely uncertain, then confirm before the irreversible booking.
DDIM: faster diffusion sampling
DDIM defines a non-Markovian deterministic process sharing DDPM's training, letting you skip steps and sample in far fewer iterations.
Diffusion-based image inpainting design
At each denoising step keep the known region by replacing it with the noised original, let the model generate only the masked area, condition on prompt and mask.
Temporal consistency in video diffusion
Add temporal layers, such as temporal attention or 3D convolutions across frames, so the model attends across time and frames denoise jointly rather than independently.
LLaVA versus Flamingo vision-LLM design
LLaVA projects image features into the LLM input space and feeds them as tokens, keeping the LLM mostly intact; Flamingo inserts gated cross-attention layers inside a frozen LLM.
Batching strategy for multimodal training
Control dataset mixing ratios, use balanced sampling and per-source weighting, keep enough text-only data to avoid forgetting, and handle variable shapes via grouping or padding.
Setting up an LLM-as-a-judge evaluation
Define rubric, prefer pairwise comparison, randomize order, calibrate against humans; control position, verbosity, and self-preference bias.
Tensor versus pipeline parallelism for large models
Tensor parallelism splits individual layers across GPUs needing fast interconnect; pipeline parallelism splits layers into stages across GPUs.
Core insight behind GPTQ and AWQ
Not all weights matter equally; GPTQ minimizes layer output error using second-order info, AWQ protects salient weight channels tied to large activations.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles