Intermediate interview questions in LLMs & Generative AI, page 5
Explain prompt injection and how to defend against it
This question tests your understanding of LLM security vulnerabilities and how untrusted user input can manipulate model behavior. A strong answer defines prompt injection as hijacking the model's instructions, then outlines a layered defense including input sanitization, instruction-tuned models, and separating user input from system prompts. A common red flag is confusing it with traditional SQL injection or suggesting simple input filtering is a sufficient solution.
How does positional encoding work in transformers?
This tests your understanding of why Transformers need explicit position data. A great answer explains that self-attention is permutation-invariant, meaning it sees inputs as an unordered set. Positional encodings—vectors derived from sine and cosine functions—are then added to the input embeddings to inject sequence order. A red flag is simply saying 'it adds position' without explaining why this is necessary or how it's done.
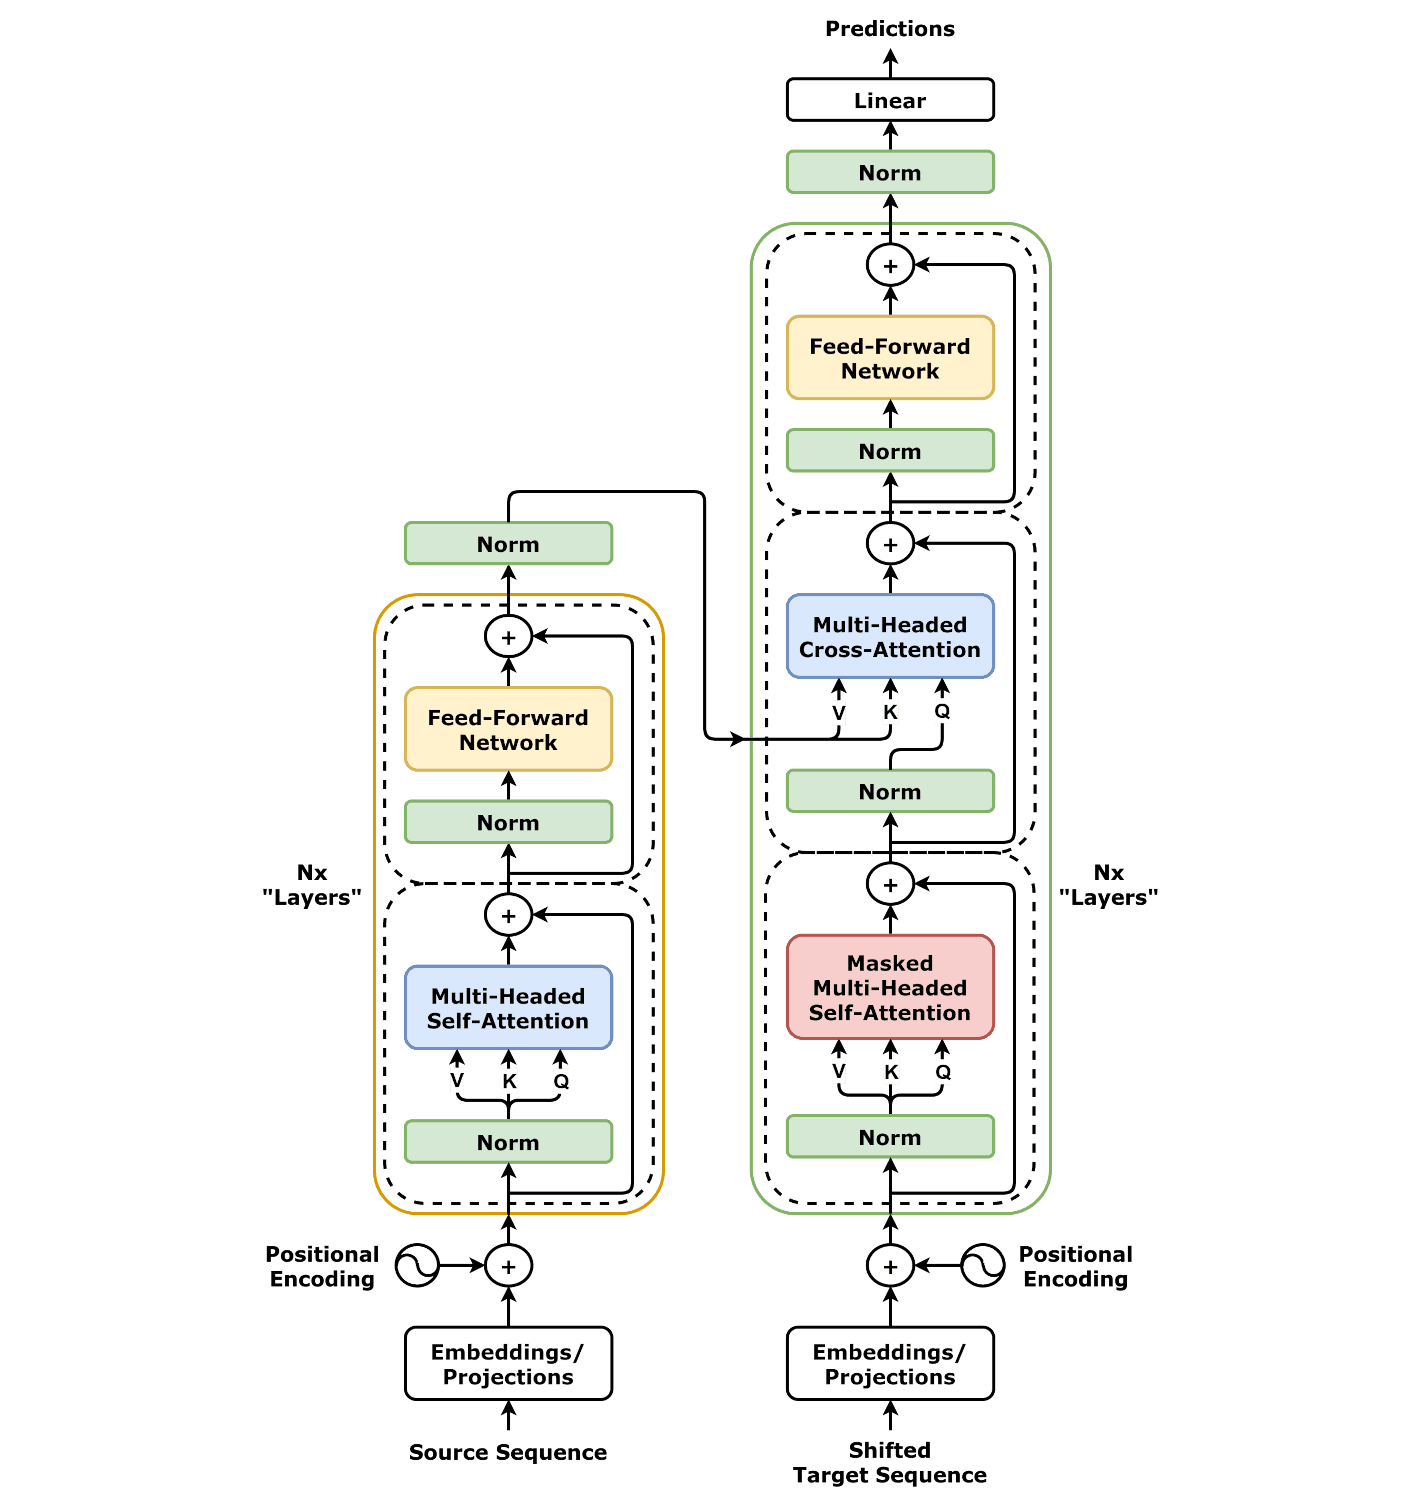
Encoder-Only vs. Decoder-Only vs. Encoder-Decoder Transformers?
This tests your ability to connect transformer architecture to specific NLP tasks. A great answer explains how each model's attention mechanism dictates its use: encoder-only (bidirectional attention) for understanding content, decoder-only (causal attention) for text generation, and encoder-decoder for sequence-to-sequence tasks like translation. The key red flag is failing to explain the *why* behind the task suitability—the attention mechanism.
RAG vs. Fine-Tuning: Key Differences
This tests your understanding of how LLMs incorporate knowledge, specifically the trade-offs between embedding it in model weights versus retrieving it at runtime. A great answer defines RAG as runtime retrieval from an external source and fine-tuning as baking knowledge into model parameters, then contrasts their approaches to knowledge updates, cost, and providing citations. A red flag is stating one is always better, or failing to explain that they solve different problems and can be used tog
What is the trade-off between top-k and top-p sampling?
This tests your practical knowledge of tuning LLM output for the creativity vs. coherence trade-off. A strong answer defines top-k (static token count) and top-p (dynamic probability mass), then explains that top-p's adaptive window is generally more robust than top-k's fixed window. A red flag is failing to contrast the static nature of top-k with the dynamic nature of top-p, which is the core of the trade-off.

Explain the concept of self-attention
This tests your ability to explain the core mechanism of Transformers. A strong answer defines self-attention as a process for relating positions of a single sequence, explains the Query-Key-Value (QKV) model where a token's Query is compared to all Keys to generate weights, and describes how these weights create a weighted sum of Values. A red flag is vaguely describing 'importance' without mentioning the QKV mechanism.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles