Interview questions in LLMs & Generative AI, page 7
CLIP's contrastive objective and zero-shot classification
Train image and text encoders to align matched pairs and repel mismatched ones in a shared space; classify zero-shot by comparing an image to text prompts of class names.
Evaluating faithfulness and compositionality in multimodal models
Use targeted probes with hard negatives, attribute-relation binding tests, and structured grounding checks; note BLEU rewards surface overlap not correctness.
Red teaming a generative model
Deliberately probe for harmful outputs across categories, document jailbreaks, and automate with adversarial prompt generators plus classifier-based judging.
Preventing PII in LLM outputs: curation, fine-tuning, or guardrails
Favor post-processing guardrails as the enforceable last line, backed by data curation; note each layer's tradeoffs and that defense-in-depth is best.
Constitutional AI versus standard RLHF
A written principle set guides self-critique and revision, plus AI feedback (RLAIF) replaces human preference labels.
Penalizing sycophancy in a reward model
Sycophancy is reward proxy gaming where agreeableness substitutes for correctness; counter it with truth-anchored labels, perturbed-premise pairs, and consistency checks.
The alignment tax and capability trade-offs
Alignment tax is capability lost from safety tuning, measured as benchmark or task-success deltas before and after; a product decision weighs over-refusal against harm risk.
Scalable oversight of superhuman models
Humans cannot judge outputs beyond their expertise, so feedback degrades; techniques like AI debate or recursive reward modeling decompose judgment.
Designing an LLM red-teaming framework
Taxonomy of harms, automated adversarial prompt generation via attacker models and mutation, a classifier to triage outputs, and severity-by-likelihood prioritization.
AWS Bedrock versus a direct provider API
Bedrock unifies many models with IAM, VPC, and cloud integration; a direct provider API gives earliest models, full feature parity, and simpler vendor terms.
How do agents use tool-calling and what can go wrong?
This tests your grasp of practical agentic architectures and their real-world trade-offs. A great answer distinguishes between predefined "workflows" and dynamic "agents," explains how an augmented LLM selects tools, and then details failure modes like framework obfuscation, debugging complexity, and the high latency/cost of multi-step processes. A red flag is vaguely describing agents without separating these patterns or ignoring the significant debugging and cost challenges.
Trade-offs between dense and sparse retrieval in RAG?
This question tests your grasp of information retrieval fundamentals and their practical trade-offs in a modern RAG system. A strong answer first defines dense (semantic) and sparse (keyword) retrieval, then contrasts their performance on different query types, and finally analyzes their operational costs (compute, storage, latency). A common red flag is declaring dense retrieval universally superior without acknowledging its weaknesses, particularly with keywords and identifiers.
Explain prompt injection and how to defend against it
This question tests your understanding of LLM security vulnerabilities and how untrusted user input can manipulate model behavior. A strong answer defines prompt injection as hijacking the model's instructions, then outlines a layered defense including input sanitization, instruction-tuned models, and separating user input from system prompts. A common red flag is confusing it with traditional SQL injection or suggesting simple input filtering is a sufficient solution.
What is the KV cache and why does it matter for serving LLMs?
This question tests your understanding of performance bottlenecks in autoregressive LLM inference. A great answer first explains that the attention mechanism computes Key (K) and Value (V) tensors for all input tokens. Then, it highlights the redundancy of recomputing these for past tokens at each new generation step. The KV cache solves this by storing these tensors, drastically reducing latency. A red flag is vaguely calling it a 'cache' without connecting it to K/V tensors.
How does positional encoding work in transformers?
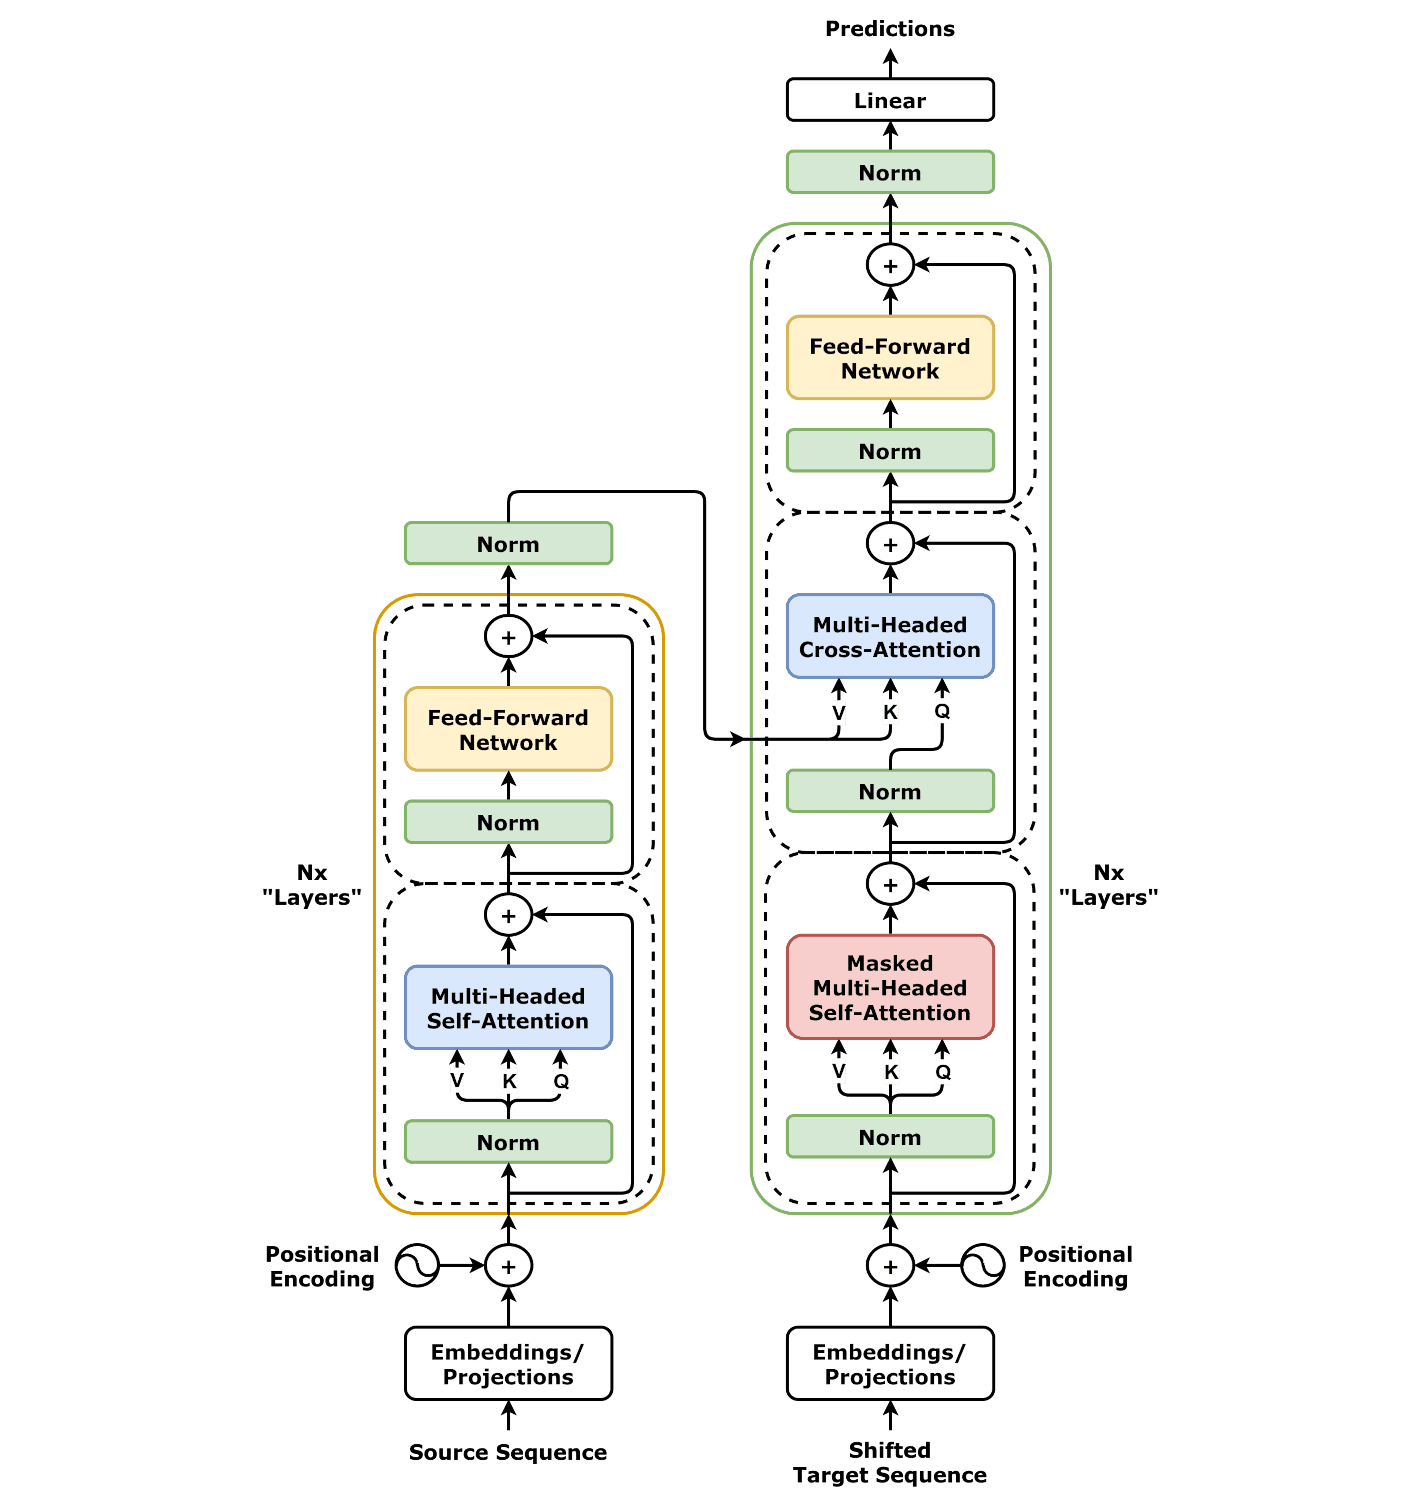
This tests your understanding of why Transformers need explicit position data. A great answer explains that self-attention is permutation-invariant, meaning it sees inputs as an unordered set. Positional encodings—vectors derived from sine and cosine functions—are then added to the input embeddings to inject sequence order. A red flag is simply saying 'it adds position' without explaining why this is necessary or how it's done.
Encoder-Only vs. Decoder-Only vs. Encoder-Decoder Transformers?
This tests your ability to connect transformer architecture to specific NLP tasks. A great answer explains how each model's attention mechanism dictates its use: encoder-only (bidirectional attention) for understanding content, decoder-only (causal attention) for text generation, and encoder-decoder for sequence-to-sequence tasks like translation. The key red flag is failing to explain the *why* behind the task suitability—the attention mechanism.
Why are MoE models larger but cheaper to run?
This tests your understanding of sparse activation versus dense models. A great answer defines Mixture-of-Experts (MoE) as a system with a router and multiple expert sub-networks, explaining that only a fraction of the total parameters are activated for any given token, which drastically reduces computational cost (FLOPs) during inference. A red flag is describing MoE as a simple ensemble without mentioning the sparse routing mechanism that enables its efficiency.
When would you use LoRA vs full fine-tuning?
This tests your grasp of practical trade-offs in ML systems, specifically training cost versus model customization. A great answer explains that LoRA is a parameter-efficient method ideal for resource-constrained scenarios, reducing trainable parameters by 10,000x and GPU memory by 3x. Full fine-tuning is for high-budget projects requiring deep model changes. A red flag is vaguely saying LoRA is 'cheaper' without quantifying the resource savings or explaining the mechanism.
What is the role of temperature in token sampling?
This tests your understanding of how to control the creativity and randomness of a language model's output. A great answer explains that temperature is a divisor applied to the model's logits before the softmax function. Low temperature makes the output more deterministic by sharpening the probability distribution, while high temperature increases randomness by flattening it. A common red flag is vaguely saying it 'controls randomness' without explaining the underlying softmax mechanism.

How to reduce hallucination in a production LLM application?
This tests your ability to design a robust, multi-layered system for AI safety, not just your model knowledge. A great answer starts with data-level grounding (RAG), moves to model-level tuning (temperature, fine-tuning), and finishes with application-level safeguards (validation, feedback loops). A red flag is focusing only on prompt engineering or stating it's an unsolvable problem without offering concrete mitigation strategies.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles