All bites
The whole library, newest first. Filter by what you are here for, or pick a topic if you already know.
8667 bites
Page 358
NoSQL: Databases Beyond Rigid Tables
NoSQL databases trade rigid tables for flexible models like documents or key-value pairs. This allows them to scale for massive, unstructured datasets from social media or IoT.
Query Rewriting: Your Database's Unseen Optimizer
A database's query rewriter is like a smart GPS, finding a faster route (execution plan) to the same destination (your query result). It happens automatically to speed up joins and filters. The footgun: your handwritten query isn't what actually runs.
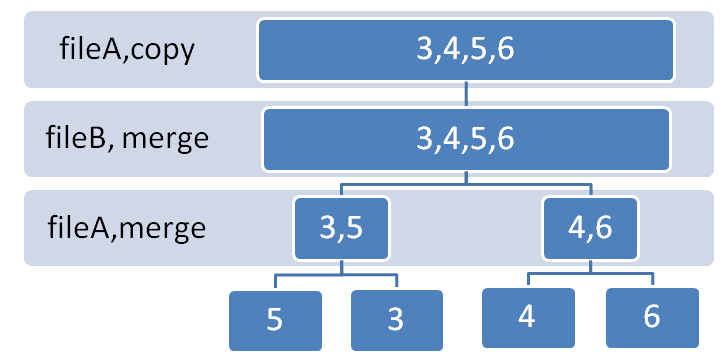
External Merge Sort: Sorting Data Bigger Than RAM
External merge sort handles datasets too big for RAM. It sorts the data in memory-sized chunks, writes them to disk, then merges the sorted chunks back together. It's crucial for database indexing, but its speed is limited by disk I/O, not CPU.
Sort-Merge Join: The 'Line Up and Walk' Join
A sort-merge join is like merging two sorted lines of people. It's efficient when tables are already sorted on the join key or memory is tight. The footgun: if data isn't pre-sorted, the initial sort can make it slower than other join methods.
Hash Join: Faster Database Joins with Hash Tables
A hash join speeds up database joins by building an in-memory lookup table (a hash table) for the smaller table, then streaming the larger one past it to find matches. It's ideal for large, unsorted equijoins.
Nested Loop Join: The Brute-Force Database Join
A nested loop join is the brute-force way to match two tables. For each row in the first table, it scans every row in the second. It's simple and effective for small tables but its performance degrades quadratically on large datasets.
PostgreSQL's Free Space Map: Finding Room to Write
A Free Space Map is a table of contents for empty space in a Postgres table. It lets Postgres quickly find a page with enough room for a new row or index entry, avoiding a slow scan. It's used on every INSERT/UPDATE.
ARIES Recovery Algorithm
ARIES is a widely-used database recovery algorithm, found in systems like IBM Db2 and SQL Server. It enables high performance by supporting a 'no-force, steal' policy, ensuring data integrity after a crash. The main footgun is not understanding this policy.
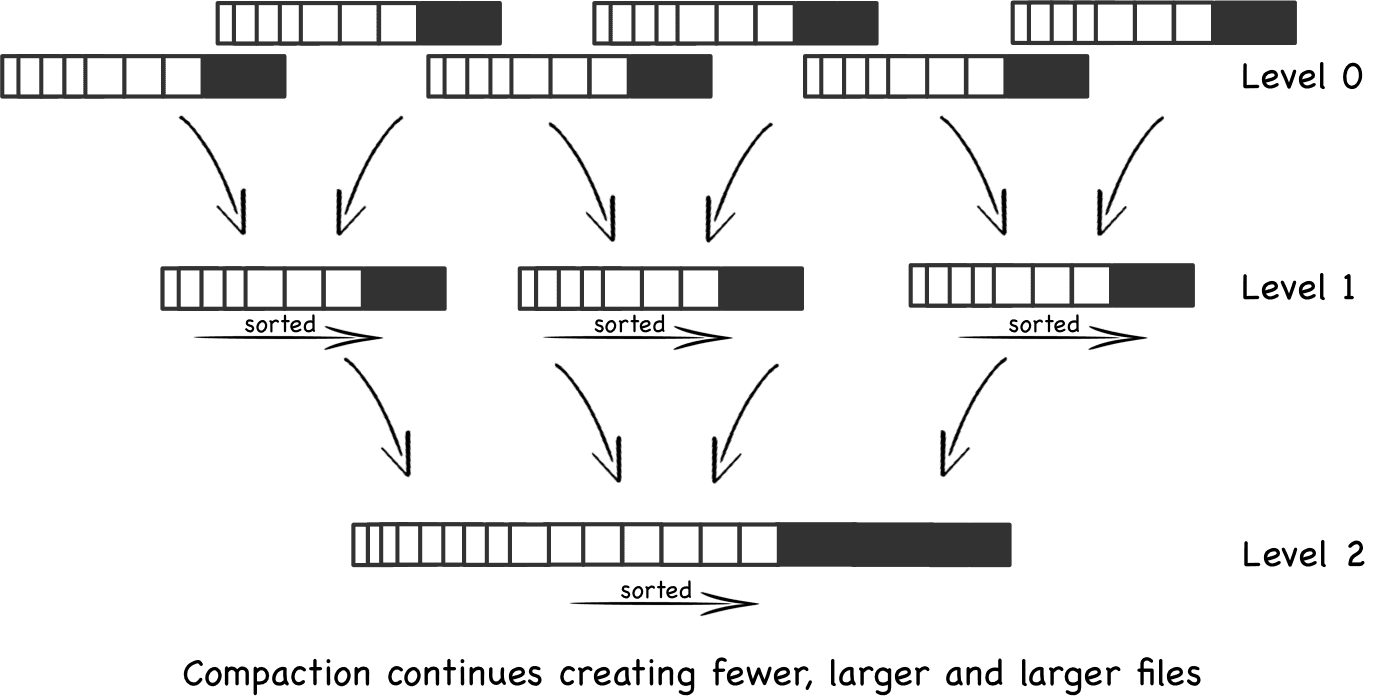
LSM-Tree: Fast Writes, Later Merges
An LSM-tree optimizes for high-volume writes by batching them in memory before flushing to disk, like a notepad for a busy filing cabinet. It's used in databases like Cassandra for write-heavy tasks. The footgun is unpredictable read latency.
Page Replacement Algorithms: Evicting Data from Memory
A page replacement algorithm is a bouncer for your RAM. When memory is full and a new page is needed, it decides which existing page to evict to disk. This is crucial in virtual memory systems.

Database Checkpoints: Faster Recovery After a Crash
A database checkpoint creates a known good point for faster crash recovery. Instead of writing every change to disk, it periodically flushes modified data from memory, reducing the amount of log data to process.
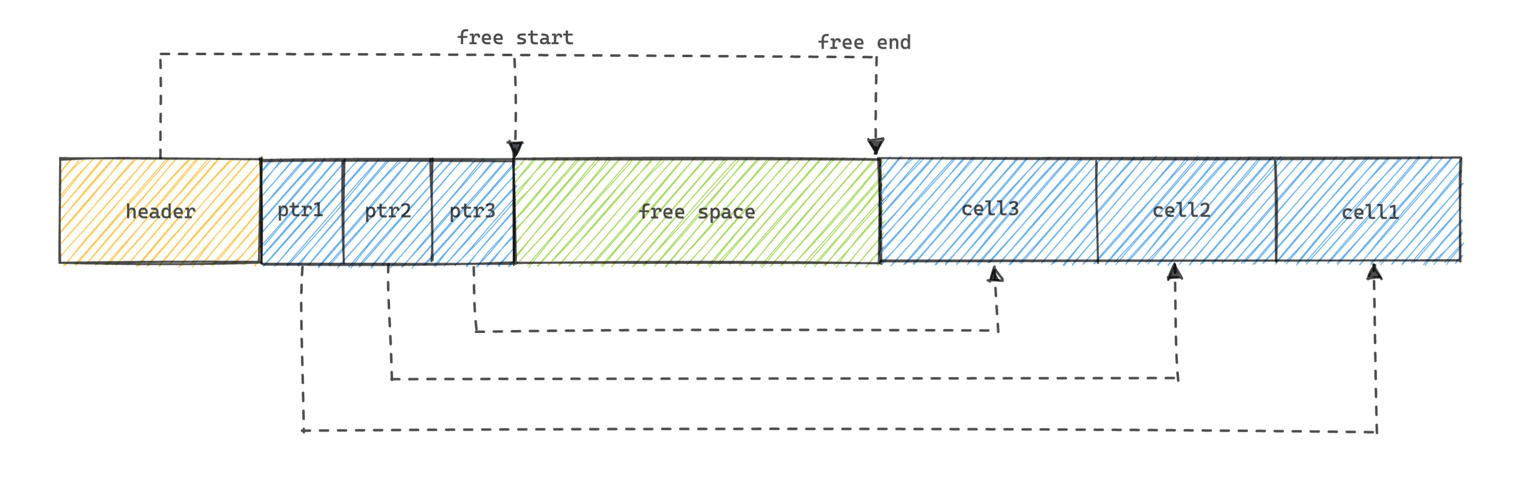
Slotted Page Structure: Stable Pointers on Disk
A slotted page organizes data by growing records from the end of the page and pointers from the beginning. This allows databases to handle variable-sized records without costly reshuffling, keeping pointers stable.

Heap File Organization: Fast Writes, Slow Reads
Heap file organization is like tossing records into a box in no particular order. It's great for bulk-loading data quickly, but searching requires a full table scan. The footgun is using it for frequently queried tables, which kills performance.
Database Pages: The Building Blocks of Your Data
A database page is the fundamental 8KB block for all storage. The database engine reads and writes entire pages, not single rows, for user data, indexes, and metadata. The key footgun: the physical order of rows on a page is not guaranteed.
Row vs. Columnar Storage: Organizing Data for Speed
Row stores group data by record, like a phone book entry. Column stores group by attribute, like separate lists for all names. Use row stores for transactions (OLTP), but for analytics (OLAP), they force you to read unneeded data from disk.
Storage Engine: The Database's Filing System
A database's storage engine is its specialized filing system, handling how data is physically written to and read from disk. Different engines optimize for different tasks, from fast writes to complex queries.
Predicate Pushdown: Filter Data at the Source
Predicate pushdown tells the database to filter data at the source, not after fetching it. This speeds up queries in data warehouses and lakehouses by reducing network traffic. The main footgun: not all data sources can execute all types of filters.
Cardinality Estimation: How Databases Guess Query Costs
A database's query optimizer guesses how many rows each part of a query will return to pick the fastest execution plan. This guess, cardinality estimation, is key for choosing join strategies.
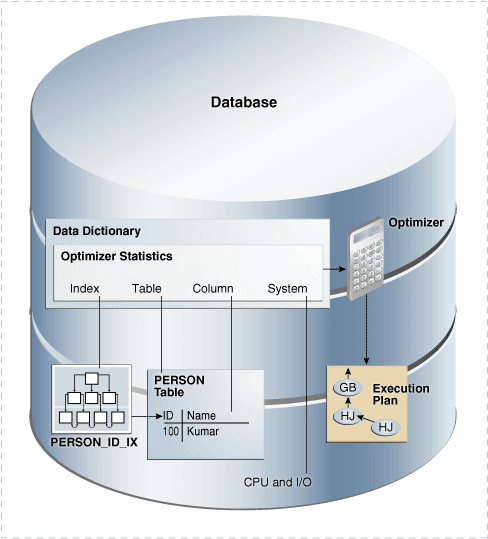
Database Statistics: The Query Optimizer's Internal Map
Database statistics are the raw data the query optimizer uses to guess the cheapest way to run your query. It uses stats like row counts and value distribution to decide between a full table scan and an index seek.
Composite Indexes: One Index for Multiple Columns
A composite index is like a phone book sorted by last name, then first name. It's for queries filtering on multiple columns, like finding a specific person. The footgun is creating separate indexes, which is far less efficient than a single composite one.