All bites
The whole library, newest first. Filter by what you are here for, or pick a topic if you already know.
8667 bites
Page 357

Vector Clocks: Tracking Causality in Distributed Systems
A vector clock is an array of counters, one for each node, that tracks causality across a distributed system. It's how databases resolve conflicting writes.
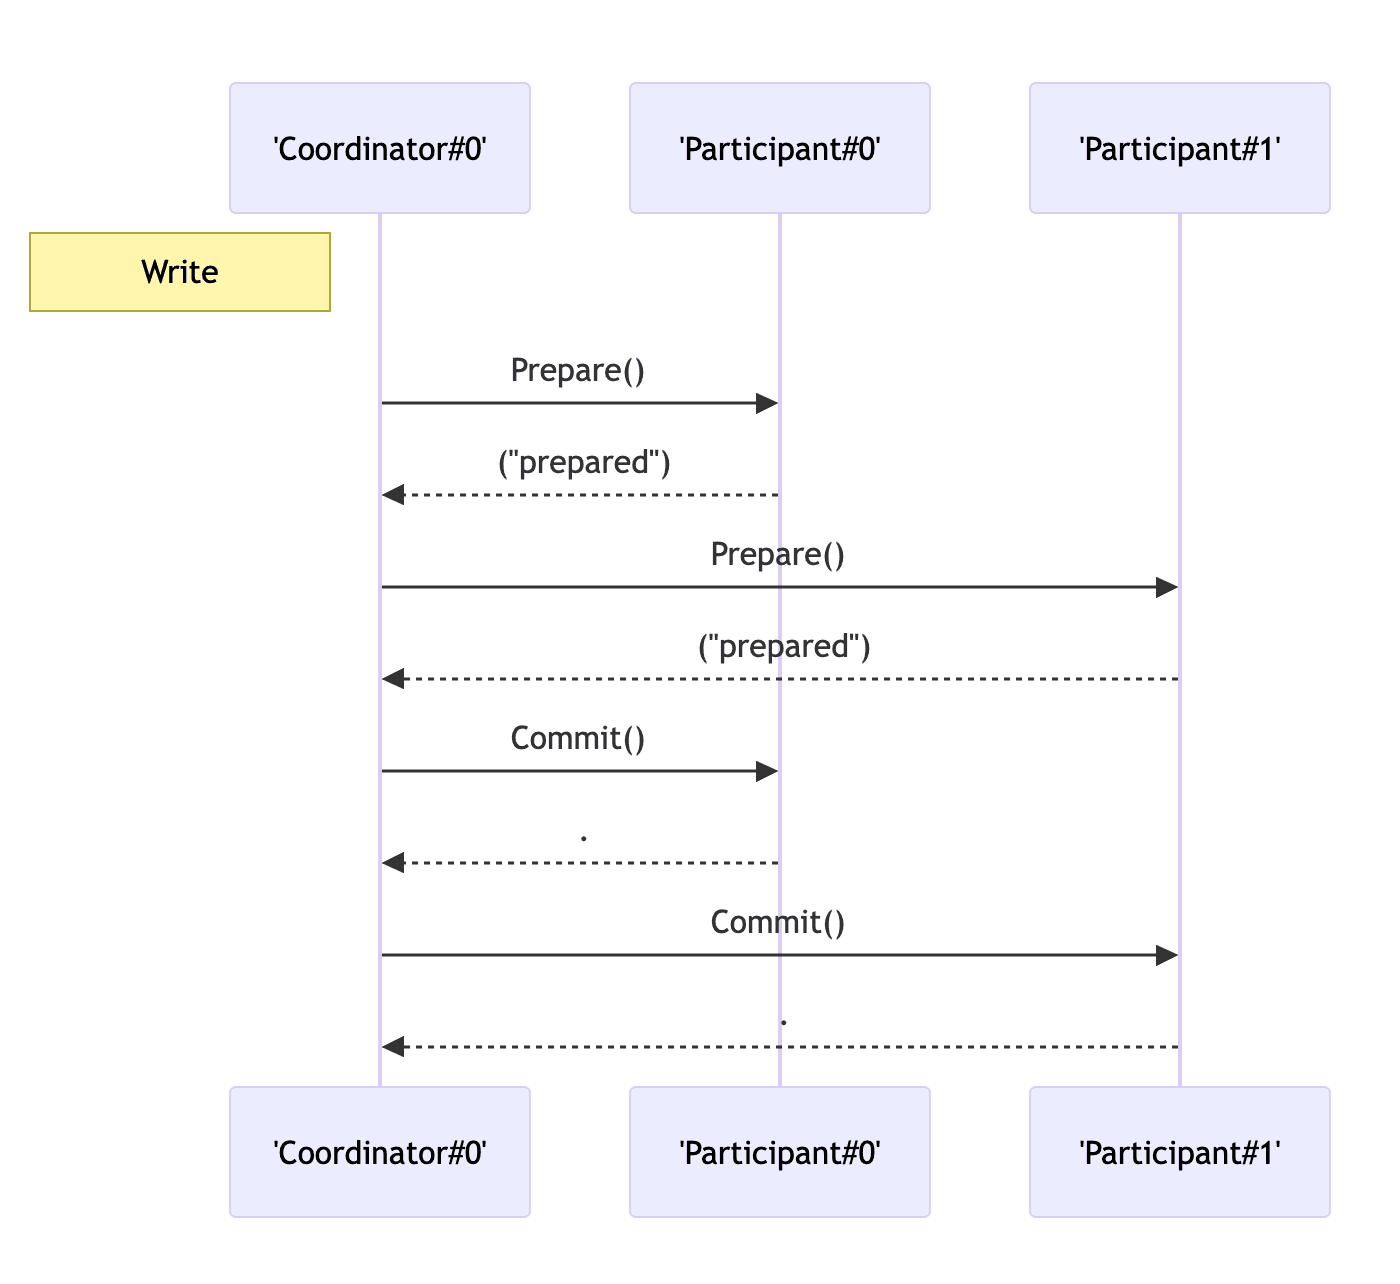
Two-Phase Commit (2PC): All or Nothing, Together
Two-Phase Commit (2PC) ensures a distributed transaction is atomic: all participants either commit or abort together. A coordinator first asks all nodes to prepare (vote), then issues a final commit or abort.
Quorum: How Distributed Systems Agree Without Unanimity
A quorum is a majority vote for distributed systems, letting them operate without waiting for every node. It's used in databases and consensus algorithms to ensure consistent writes. The footgun is setting the quorum too low, risking conflicting decisions.
Consistent Hashing: Resizing Distributed Systems Gracefully
Consistent hashing prevents mass data reshuffling when servers are added or removed. It maps keys to servers on a logical ring, so only a fraction of keys need remapping during a resize. This is crucial for distributed caches to avoid stampedes.
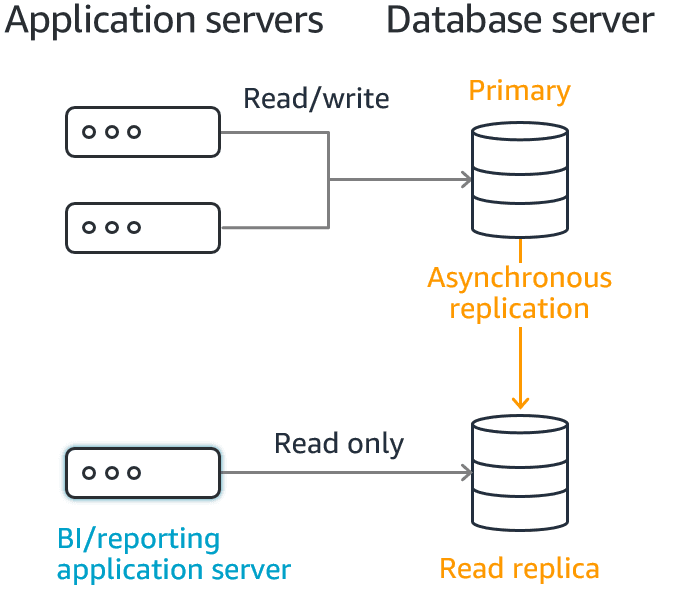
Read Replicas: Scale Out Your Database Reads
A read replica is a read-only copy of your database that handles query traffic. Use it for read-heavy apps to prevent your primary DB from becoming a bottleneck. The footgun: replication is asynchronous, so reads from a replica can return slightly stale data.
MOLAP: A Pre-Computed Cube for Fast Analytics
MOLAP pre-calculates business data into a multi-dimensional "cube" for near-instant analytics. Use it for BI dashboards requiring fast responses to complex queries. The footgun: the cube is a static snapshot, and building it can be slow and rigid.
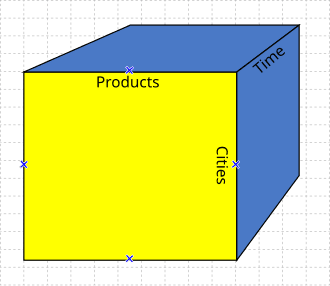
OLAP Cube Operations
OLAP cube operations let you analyze data like a multi-dimensional spreadsheet. Instead of just rows and columns, you navigate dimensions like time and location. Used in business intelligence to answer complex analytical questions.
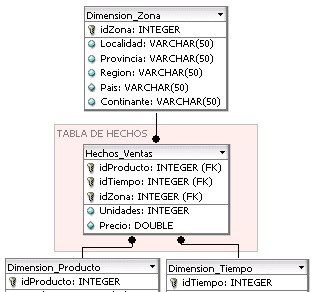
Dimension Tables: The 'Who, What, Where, When' of Your Data
Dimension tables provide the descriptive context—the 'who, what, where, when'—for raw numbers in a fact table. They are the backbone of data warehouses, letting you slice sales data by product or region. The footgun is polluting them with transactional data.
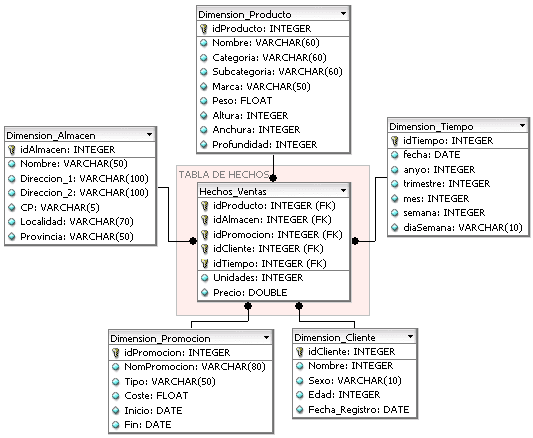
Fact Table: The Numbers in Your Data Warehouse
A fact table is the ledger of business events, recording what happened and how much. It's the core of a data warehouse, holding sales figures or page views. The footgun is storing descriptive text here; that belongs in linked dimension tables.
CRDTs: Syncing Data Without Locks or Conflicts
CRDTs are data structures where updates can be applied in any order and reach the same state, avoiding locks. They enable offline editing in collaborative apps and distributed databases.
Vector Databases: Searching by Meaning, Not Keywords
A vector database finds "what's most like this?" instead of "find me exactly this." It organizes data by semantic meaning, not just exact values, making it ideal for recommendation engines, semantic search, or finding similar images.
Polyglot Persistence: Use the Right Database for the Job
Polyglot persistence means using multiple, specialized data stores in one system. Instead of one database handling everything, you might use a relational DB for transactions, a document DB for profiles, and a graph DB for connections.

BASE: Trading Consistency for Availability
BASE is a database design philosophy that prioritizes availability over strict consistency, the opposite of ACID. It's used in large-scale systems like social media where uptime is key and slightly stale data is okay.
Time Series Database: A Logbook, Not a Filing Cabinet
A Time Series Database (TSDB) is a specialized logbook for data that happens over time, like server metrics or sensor readings. It's built for high-speed writes and fast range queries. The footgun: don't use it for relational data like user profiles.
Database Sharding: Splitting Data for Scale
Sharding splits a database across multiple servers, like dividing a phone book into A-M and N-Z volumes. It's used when a single server can't handle the data size or write load. The footgun is that querying across shards is complex and slow.
Graph Databases: When Relationships Are the Data
A graph database treats connections between data as first-class citizens. It's ideal for social networks or fraud detection where you query relationships by traversing links. The footgun is using it for simple tabular data where a relational DB is faster.
Wide-Column Store: Flexible Schema for Massive Datasets
A wide-column store is like a spreadsheet where each row can have its own unique columns. It's ideal for sparse data like user profiles or IoT readings. The footgun is thinking it's just a relational table with many columns—the flexibility is the point.
Eventual Consistency: Availability Now, Correctness Later
Eventual consistency prioritizes availability by letting replicas temporarily disagree. If updates stop, all nodes will eventually converge on the same value.
Document Databases: Store Data as Flexible Objects
A document database stores data as self-contained objects, like JSON, instead of rows and columns. It's ideal for user profiles or product catalogs where each item might have different attributes. The footgun is treating it as a schema-less free-for-all.

Key-Value Store: The Simplest Database Model
A key-value store is a giant dictionary. You give it a unique key, like "user:123", and it returns the associated data. It's the foundation for caching and session management. The footgun is trying to query by value—it's built for key lookups only.