Interview questions in AI & ML, page 2

What is the difference between lossy and lossless image compression?
This tests irreversible discard versus perfect reconstruction. A strong answer defines lossy as dropping detail, lossless as fully reversible, names JPEG, PNG, and chooses lossless for masters, lossy for web. Red flag: claiming lossless is always smaller.
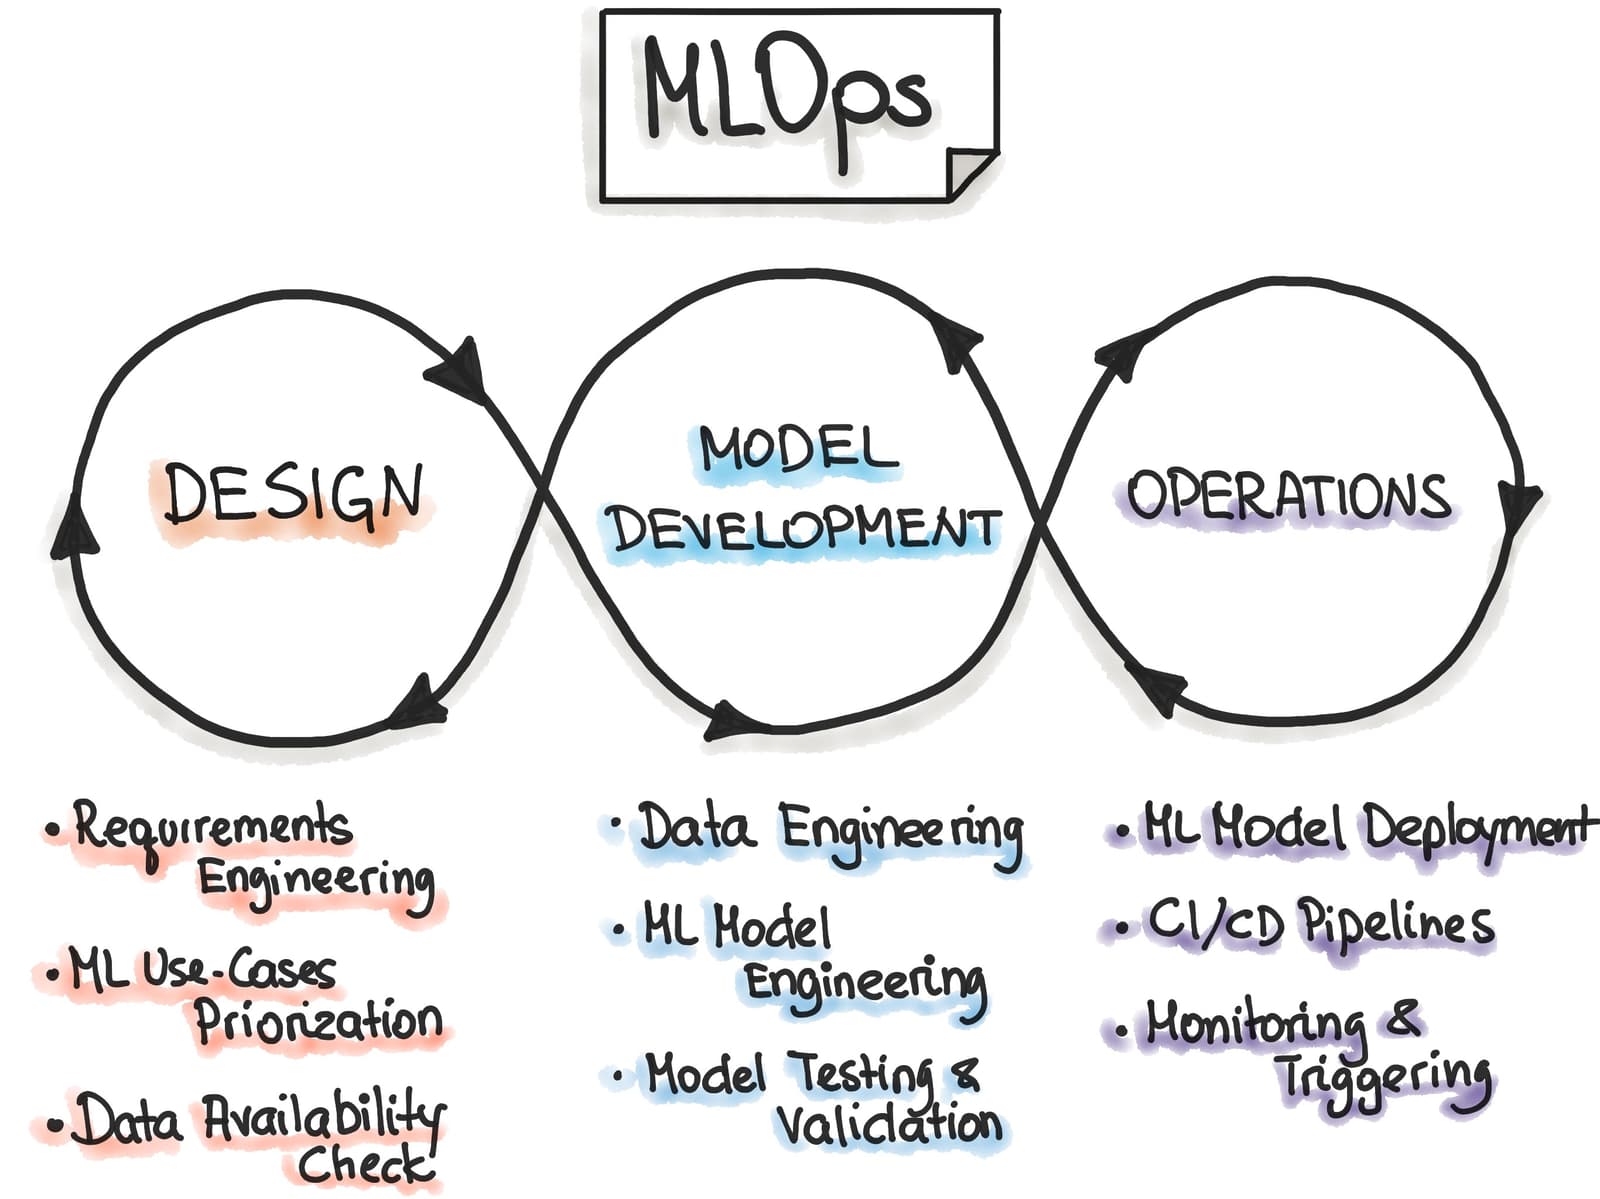
Why version code, data, and models in MLOps?
Tests immutable lineage across code, data, and models. Strong answers cover content-addressed data, git commits, a model registry linking both, and CI triggers on any change. Red flag: saying git alone handles data and models.
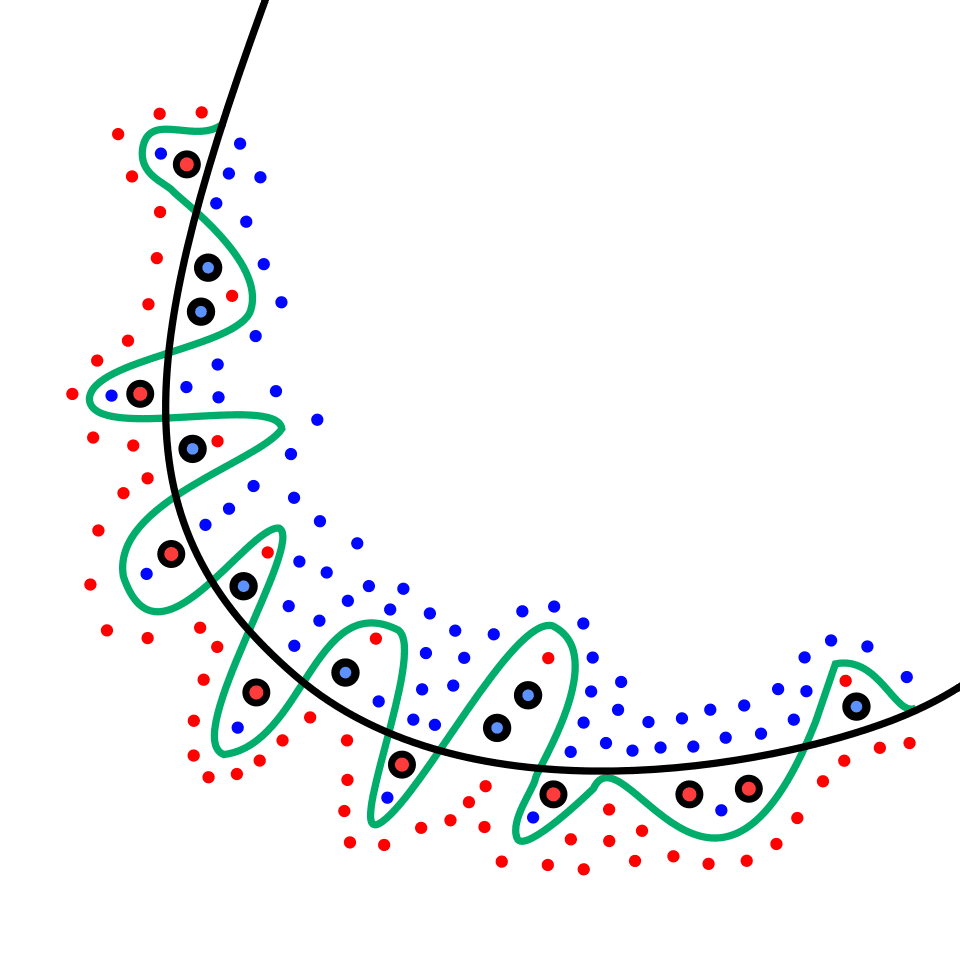
Validation loss increases while training loss decreases: what is this?
This tests recognition of overfitting and regularization. A strong answer names it, offers early stopping, dropout or weight decay, and data augmentation or more data. A red flag is suggesting longer training or more parameters without fixing generalization.
How do you define churn for a subscription service?
This tests operationalizing a business metric into a data definition. A strong answer separates voluntary from passive churn, picks a moment, and aligns to the billing cycle. Red flag: counting all cancellations as churn while ignoring grace periods.
Describe a grayscale histogram and its use in exposure and equalization
Tests pixel distribution intuition. A strong answer covers intensity bin counts, left or right clustering for exposure errors, and CDF-based redistribution for equalization. Red flag: calling equalization min-max stretching without cumulative mapping.
Explain ML pipelines and typical CI/CD/CT components
Tests if you separate code CI/CD from model CT and grasp ML automation. Cover source control, build, tests, deploy for code; data validation, training, evaluation, promotion for CT. Red flag: treating ML like software CI/CD and ignoring data or registry gates.
Explain BPTT and its computational and memory challenges for long sequences
Tests whether you see RNNs as deep unrolled graphs. Good answers define BPTT as backprop over T steps, flag O(T) memory from hidden states, and note vanishing or exploding gradients. Red flag: calling memory constant or confusing BPTT with online updates.
How would you recommend launching a checkout flow with mixed A/B metrics?
This tests multi-metric trade-offs. A strong answer tags conversion as success and AOV as a guardrail, estimates net revenue impact, and frames decision as a risk-managed business choice. A red flag is demanding all metrics win or ignoring business context.

Explain the pinhole camera model and intrinsic matrix K
Tests projective geometry and mapping sensor properties to K. Good answers derive perspective projection via similar triangles, list fx, fy, cx, cy, skew, and explain pixel scaling. Red flag: mixing intrinsics with extrinsics or saying K includes distortion.
Lens distortion and camera calibration
Radial distortion bends straight lines (barrel/pincushion), tangential comes from lens-sensor misalignment; calibrate with a known pattern to estimate intrinsics and distortion coefficients.
Attention in Sequence-to-Sequence Models
Attention computes per-step weighted sums over all encoder states, fixing the information bottleneck for long inputs.
What production metrics and auto-thresholds trigger model retraining?
This tests production monitoring maturity. A strong answer covers technical drift metrics, business KPIs tied to model decisions, and automated thresholds that page or trigger CI/CD retraining.

How do you frame high-value customer identification as classification versus regression?
Tests mapping a business goal to a defensible target. Outline: define value and action, then contrast regression predicting spend versus classification predicting tiers. Red flag: picking models before fixing the label or the campaign action.
Does forcing profile completion cause retention?
Name the confounder (engaged users self-select into completing profiles), warn that forcing it may not transfer the effect, and propose a randomized experiment.

Design an MLOps platform for a mid-sized company: components and build-vs-buy trade-offs
Tests pragmatic scoping and build-vs-buy reasoning. Strong answers rank data estate, feature store, registry, CI/CD/CT, and monitoring above exotic serving, buying commodity and building differentiators. Red flag: custom orchestrators or missing governance.
Explain positional encodings in Transformers and their necessity
Explain encodings inject order into embeddings; cite sinusoidal or learned vectors.
How does a Bayer filter capture color and what is demosaicing?
This tests CFA sampling tradeoffs. The answer covers the RGGB mosaic, demosaicing as interpolation of missing channels, and moire or zippering artifacts. A red flag is believing pixels capture full RGB natively or that demosaicing is only averaging.
Framing ad-load tradeoffs: revenue versus retention
Define revenue plus guardrail engagement metrics, run a long-enough experiment to see retention effects, and weigh short-term lift against lifetime-value erosion.
Self-Attention versus Recurrent Architectures
Each token attends to all others via query-key-value, enabling parallelism and direct long-range links.
Design a robust automated testing strategy for ML models before production
Statistical offline thresholds, shadow-canary launches, input drift detection, and rollbacks tied to KPIs.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles