Interview questions in AI & ML, page 28

How to reduce hallucination in a production LLM application?
This tests your ability to design a robust, multi-layered system for AI safety, not just your model knowledge. A great answer starts with data-level grounding (RAG), moves to model-level tuning (temperature, fine-tuning), and finishes with application-level safeguards (validation, feedback loops). A red flag is focusing only on prompt engineering or stating it's an unsolvable problem without offering concrete mitigation strategies.

Explain Supervised Fine-Tuning, RLHF, and DPO
This tests your understanding of modern LLM alignment techniques. A strong answer explains that Supervised Fine-Tuning (SFT) teaches the model a task via imitation, while RLHF and DPO align it with human preferences. RLHF uses a reward model and reinforcement learning, whereas DPO is a simpler, direct optimization method. The key red flag is conflating these distinct stages or failing to explain the 'reward model' step in RLHF.
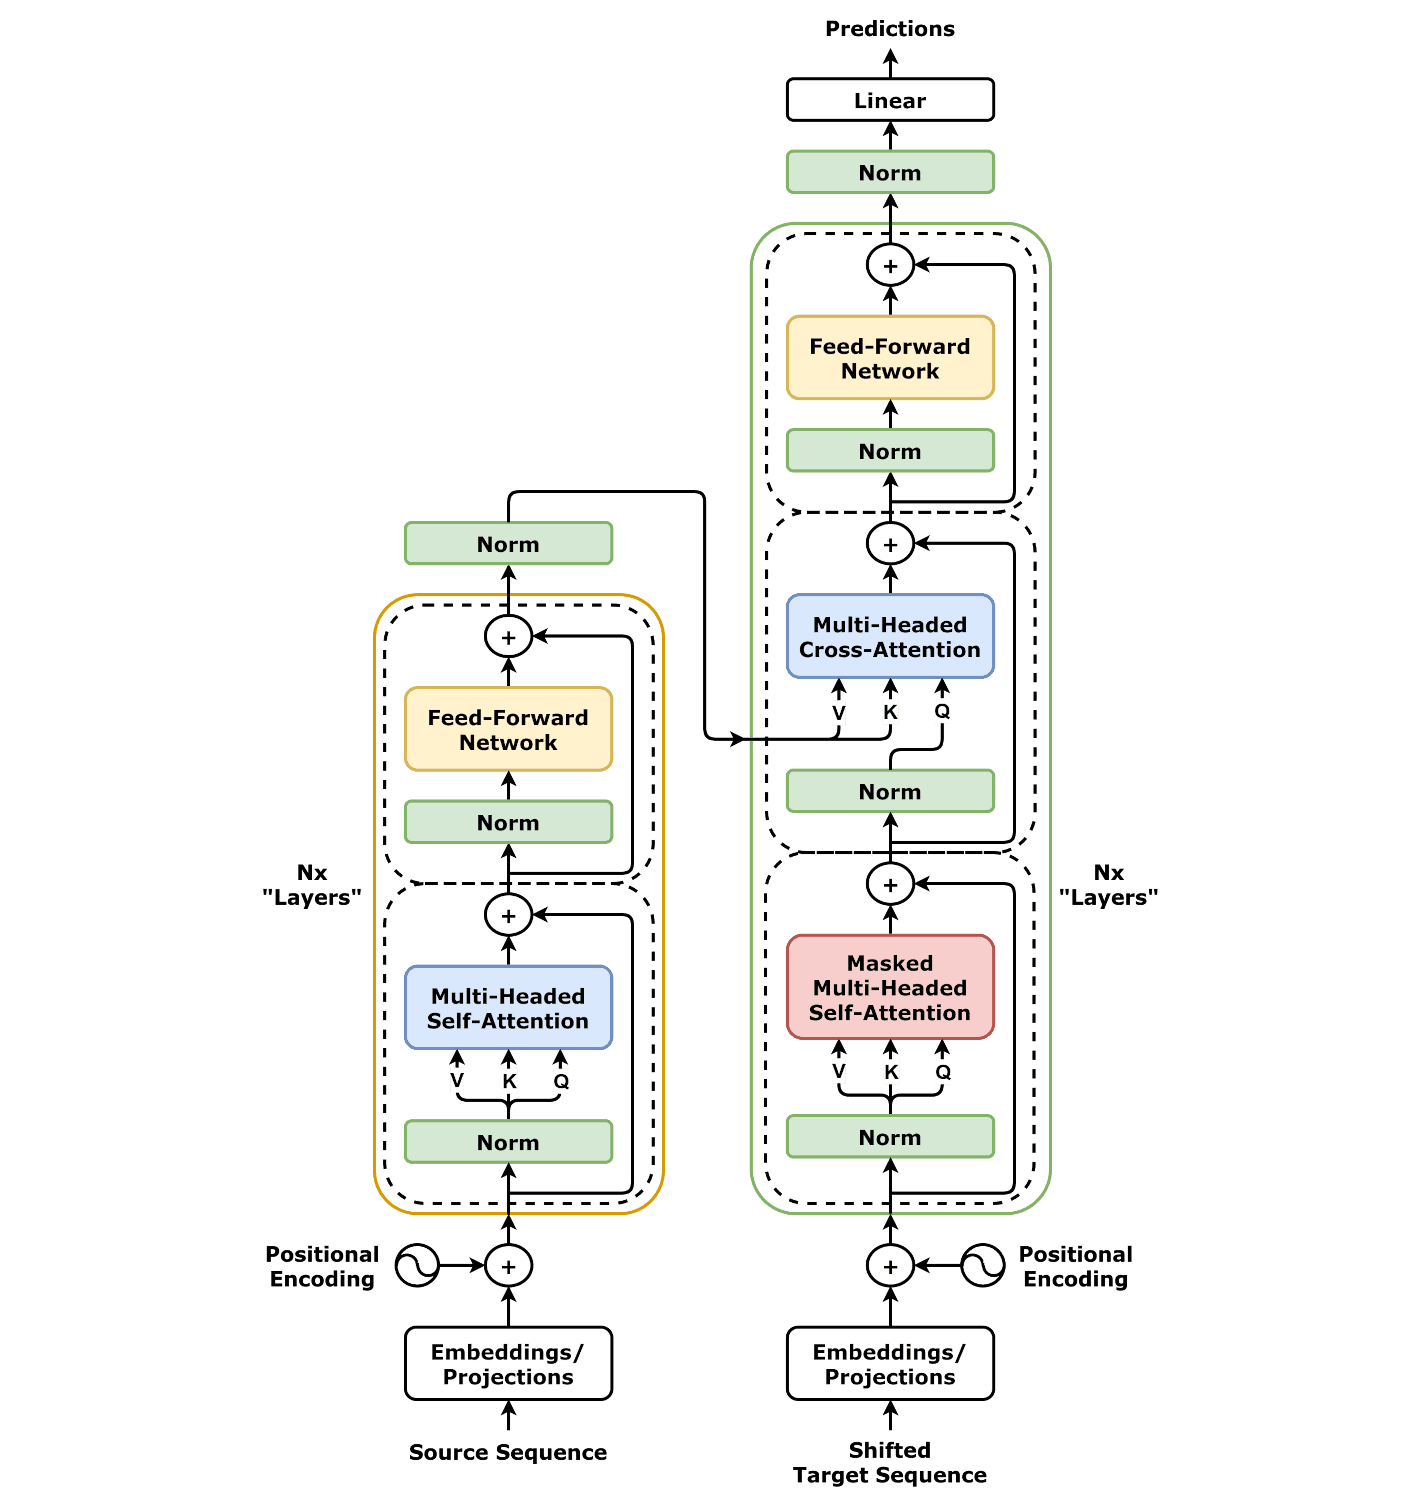
What is the vanishing gradient problem and how do transformers avoid it?
This tests your understanding of core deep learning training issues and the transformer's specific architectural solutions. A great answer defines vanishing gradients in sequential models, then explains how the transformer's parallel attention mechanism creates direct, short paths for gradients between any two tokens, regardless of distance. A red flag is vaguely mentioning 'attention' without explaining why its parallel nature is the key to solving the problem for long sequences.
RAG vs. Fine-Tuning: Key Differences
This tests your understanding of how LLMs incorporate knowledge, specifically the trade-offs between embedding it in model weights versus retrieving it at runtime. A great answer defines RAG as runtime retrieval from an external source and fine-tuning as baking knowledge into model parameters, then contrasts their approaches to knowledge updates, cost, and providing citations. A red flag is stating one is always better, or failing to explain that they solve different problems and can be used tog
What is the trade-off between top-k and top-p sampling?
This tests your practical knowledge of tuning LLM output for the creativity vs. coherence trade-off. A strong answer defines top-k (static token count) and top-p (dynamic probability mass), then explains that top-p's adaptive window is generally more robust than top-k's fixed window. A red flag is failing to contrast the static nature of top-k with the dynamic nature of top-p, which is the core of the trade-off.

Explain the concept of self-attention
This tests your ability to explain the core mechanism of Transformers. A strong answer defines self-attention as a process for relating positions of a single sequence, explains the Query-Key-Value (QKV) model where a token's Query is compared to all Keys to generate weights, and describes how these weights create a weighted sum of Values. A red flag is vaguely describing 'importance' without mentioning the QKV mechanism.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles