Everything in AI & ML, page 27

How would you monitor data quality for a C-level dashboard pipeline?
Designing production data observability for executive dashboards. A strong answer maps freshness SLAs, completeness checks, and distribution drift detection to business impact.
When is streaming better than batch, and what are its infrastructure challenges?
Tests if you separate low-latency decisions from analytics and know ops pain. Good answer: fraud detection vs batch; cite exactly-once, state recovery, backpressure, schema drift. Red flag: calling streaming faster batch while ignoring backpressure or state.
How would you partition a massive user events table?
Tests whether you map query patterns to storage layout to cut bytes scanned. Strong answers pick time-based partitioning for range pruning, cluster by high-cardinality filters, and justify against WHERE clauses.

What is data pipeline idempotency and how do you design for it?
This tests resilient pipeline design under failure. A strong answer defines idempotency as identical output on repeated runs, highlights safe retries and partial failure recovery, and proposes idempotency keys with atomic writes for daily API loads.
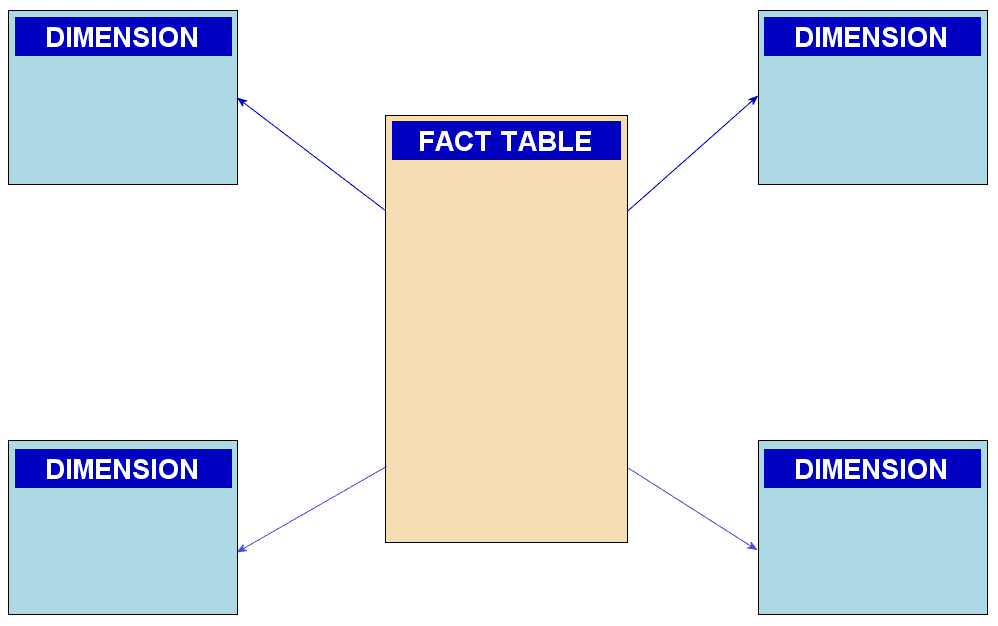
Star schema vs snowflake schema: differences and trade-offs
Tests dimensional modeling: star schemas flatten dimensions for fast joins and simple queries, while snowflakes normalize them to cut redundancy at the cost of extra joins. Red flag: praising snowflake storage savings without admitting query overhead.

Describe the difference between ETL and ELT and when to choose each
Tests transform timing and compute location. ETL cleans data before loading via external engines; ELT loads raw data first, then transforms in the warehouse. Pick ETL when pre-load cleansing is needed, ELT when warehouse compute is cheaper.
How would you standardize a 500GB dataset that does not fit in RAM?
This tests two-pass statistics for out-of-core scaling. A good answer outlines: first compute mean and variance via sums and counts; second apply z = (x - mean) / std; mention Dask-ML or PySpark. A red flag is averaging chunk-wise means without weighting.
How do you prevent future leakage in time-series preprocessing?
This tests temporal causality in feature engineering and validation. Use only past data for lags and rolling windows and enforce a rolling validation split without shuffling. Red flags are random k-fold CV and global standardization leaking future information.
Why is scaling unnecessary for trees but critical for SVM or K-Means?
Tests whether you understand model internals. Trees split on rank order, so scale is irrelevant. SVM and K-Means rely on distance or margin geometry, making magnitude dominate.
What is data leakage in preprocessing and cross-validation?
This tests recognition of data leakage through preprocessing statistics. A strong answer defines leakage, describes scaling using global statistics before CV splits, and states transformers must be fit per training fold.
Why avoid one-hot encoding for high cardinality and what are alternatives?
This tests dimensionality explosion and encoding alternatives. A strong answer notes one-hot creates many sparse binary columns, increasing memory and compute costs, then names strategies such as target encoding or feature hashing and explains leakage safeguards.
Min-Max scaling vs Z-score standardization: differences and algorithm preferences
Tests if you know how feature scaling works and can pair a scaler with algorithmic assumptions. Contrast [0,1] Min-Max against mean-zero Z-score, then defend standardization for PCA or gradient descent.
Design a scalable, fault-tolerant real-time IoT data ingestion system
This tests separation of edge connectivity, buffering, and processing. A strong answer names an edge gateway, Kafka as the backplane, stream processing, and cold storage, plus backpressure and partitioning.
How would you evade an advanced anti-bot system while scraping?
Discuss JA3/TLS spoofing, CDP-based browser automation, human-like mouse paths and delays, and session consistency.

Design an incremental load pipeline from a transactional DB to a warehouse
Contrast timestamp watermarking, CDC from transaction logs, and open-table incremental reads; cite merge logic and idempotency.
Implement OAuth 2.0 flow to get an access token for API requests
Tests your grasp of OAuth 2.0 grant-type selection and token lifecycle. Strong answers match the script context to client credentials or authorization code flow, detail the token endpoint exchange, and address refresh and expiry.

SQL or NoSQL for high-volume semi-structured event ingestion?
Choose an event store by access patterns, write volume, consistency and operational cost. Document stores fit flexible payloads; PostgreSQL JSONB is also a valid option.
How would you scrape a page with dynamically loaded JavaScript content?
It tests if you know dynamic pages need a real renderer. A great answer names Playwright or Selenium, uses explicit waits for elements, and extracts via DOM or network interception. Red flag: suggesting only static parsers like BeautifulSoup or blind sleeps.

Design a rate-limited REST API data collection script
Tests client-side throttling discipline versus reactive 429 handling. Strong answers proactively pace calls using rate-limit headers, cap concurrency, and apply exponential backoff with jitter. Red flag: tight-loop retries or ignoring headers.
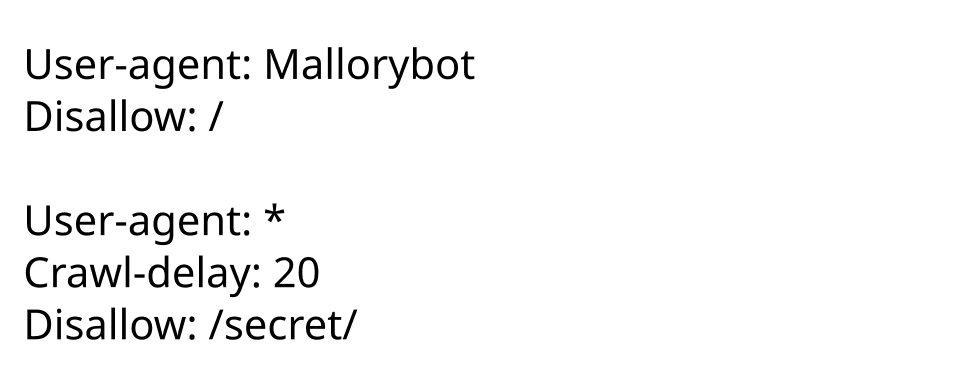
What is robots.txt, why respect it, and consequences of ignoring it?
It disallows crawler paths via the Robots Exclusion Protocol; honoring it prevents server strain, legal risk, and broken trust.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles