Intermediate everything in Backend Dev, page 26
Graph Databases: When Relationships Are the Data
A graph database treats connections between data as first-class citizens. It's ideal for social networks or fraud detection where you query relationships by traversing links. The footgun is using it for simple tabular data where a relational DB is faster.
Wide-Column Store: Flexible Schema for Massive Datasets
A wide-column store is like a spreadsheet where each row can have its own unique columns. It's ideal for sparse data like user profiles or IoT readings. The footgun is thinking it's just a relational table with many columns—the flexibility is the point.
Eventual Consistency: Availability Now, Correctness Later
Eventual consistency prioritizes availability by letting replicas temporarily disagree. If updates stop, all nodes will eventually converge on the same value.
Query Rewriting: Your Database's Unseen Optimizer
A database's query rewriter is like a smart GPS, finding a faster route (execution plan) to the same destination (your query result). It happens automatically to speed up joins and filters. The footgun: your handwritten query isn't what actually runs.
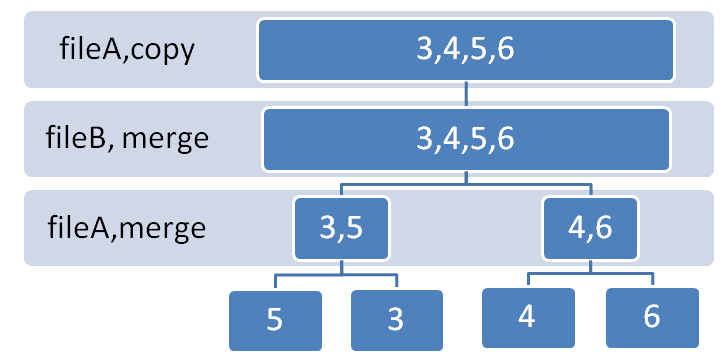
External Merge Sort: Sorting Data Bigger Than RAM
External merge sort handles datasets too big for RAM. It sorts the data in memory-sized chunks, writes them to disk, then merges the sorted chunks back together. It's crucial for database indexing, but its speed is limited by disk I/O, not CPU.
Sort-Merge Join: The 'Line Up and Walk' Join
A sort-merge join is like merging two sorted lines of people. It's efficient when tables are already sorted on the join key or memory is tight. The footgun: if data isn't pre-sorted, the initial sort can make it slower than other join methods.
Hash Join: Faster Database Joins with Hash Tables
A hash join speeds up database joins by building an in-memory lookup table (a hash table) for the smaller table, then streaming the larger one past it to find matches. It's ideal for large, unsorted equijoins.
Page Replacement Algorithms: Evicting Data from Memory
A page replacement algorithm is a bouncer for your RAM. When memory is full and a new page is needed, it decides which existing page to evict to disk. This is crucial in virtual memory systems.

Database Checkpoints: Faster Recovery After a Crash
A database checkpoint creates a known good point for faster crash recovery. Instead of writing every change to disk, it periodically flushes modified data from memory, reducing the amount of log data to process.
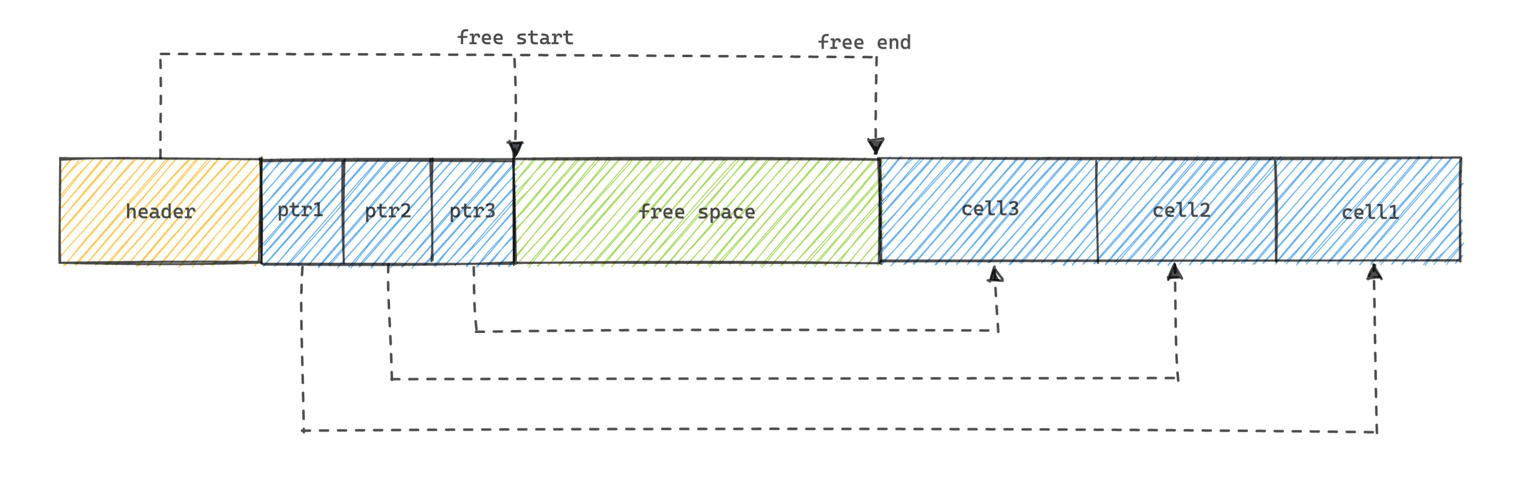
Slotted Page Structure: Stable Pointers on Disk
A slotted page organizes data by growing records from the end of the page and pointers from the beginning. This allows databases to handle variable-sized records without costly reshuffling, keeping pointers stable.

Heap File Organization: Fast Writes, Slow Reads
Heap file organization is like tossing records into a box in no particular order. It's great for bulk-loading data quickly, but searching requires a full table scan. The footgun is using it for frequently queried tables, which kills performance.
Composite Indexes: One Index for Multiple Columns
A composite index is like a phone book sorted by last name, then first name. It's for queries filtering on multiple columns, like finding a specific person. The footgun is creating separate indexes, which is far less efficient than a single composite one.
The Query Optimizer: Your Database's Internal GPS
A query optimizer is your database's internal GPS, turning your SQL "what" into the fastest "how." It chooses the best execution plan—like join order or index usage—for every query. The footgun: stale statistics can trick it into picking a slow route.
Strict Two-Phase Locking (S2PL): Safety Over Speed
Strict Two-Phase Locking (S2PL) forces a transaction to hold all its locks until it fully commits or aborts. This prevents cascading aborts in databases but at the cost of concurrency, as other transactions are blocked for longer periods.
MVCC: Read and Write Data Without Blocking Each Other
MVCC avoids slow, traditional locks by giving each transaction its own consistent data snapshot. This allows readers and writers to work at the same time without blocking each other, boosting performance in databases like PostgreSQL.
Database Deadlock: The Two-Way Standoff
A deadlock is a 'Mexican standoff' where two transactions can't finish because each is waiting for a resource the other has locked. This happens in systems with concurrent writes. The database will kill one transaction, forcing your app to handle the retry.
Two-Phase Locking (2PL): Preventing Database Race Conditions
2PL is a database's pessimistic strategy for safe concurrency. A transaction acquires all necessary locks before releasing any, ensuring operations don't clash. It's used to guarantee consistency.
Denormalization: Trading Write Speed for Faster Reads
Denormalization speeds up database reads by intentionally adding redundant data, trading write-speed for read-performance. Use it for read-heavy systems like reporting dashboards where joins are too slow.
Surrogate Keys: Stable IDs for Unstable Data
A surrogate key is a meaningless, system-generated ID that never changes, unlike a 'natural' key (like an email) which can. Use it for stable joins between tables. The footgun is exposing these internal IDs in public URLs, which leaks data structure.
Third Normal Form (3NF): Nothing But The Key
Third Normal Form (3NF) dictates that every non-key column must describe 'nothing but the key.' This prevents transitive dependencies, where one non-key column determines another.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles