Advanced everything in Cloud Platforms, page 3
Explainable AI (XAI): Why Did the Model Do That?
Explainable AI (XAI) translates a model's 'black box' decision into a human-readable reason. Use it to debug predictions, build user trust, or meet regulatory needs. The footgun: explanations are approximations of the model's logic, not absolute truth.

Model Drift: When Good Models Go Bad
A model is a snapshot of the world; model drift is the alarm that fires when the world changes but your snapshot has not. It detects when production data no longer statistically matches the training data, a common issue for models predicting user behavior.
Distributed Model Training: Splitting the Workload
Don't wait for one GPU to finish; use many. Distributed training splits a model's workload across multiple processors to finish faster. It's essential for massive deep learning models.
Data Virtualization: One Query, Many Sources
Data virtualization creates a single logical database from many physical sources without moving the data. It's used for real-time integration across silos like SQL, NoSQL, and APIs.
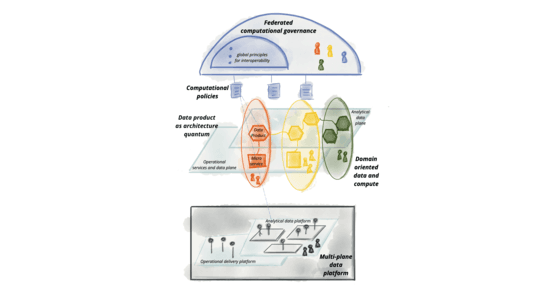
Data Mesh: From Central Data Lake to Distributed Ownership
Data Mesh decentralizes data ownership, moving it from a central team to the business domains that create it. This approach, like microservices for data, is for orgs where a monolithic data lake has become a bottleneck.
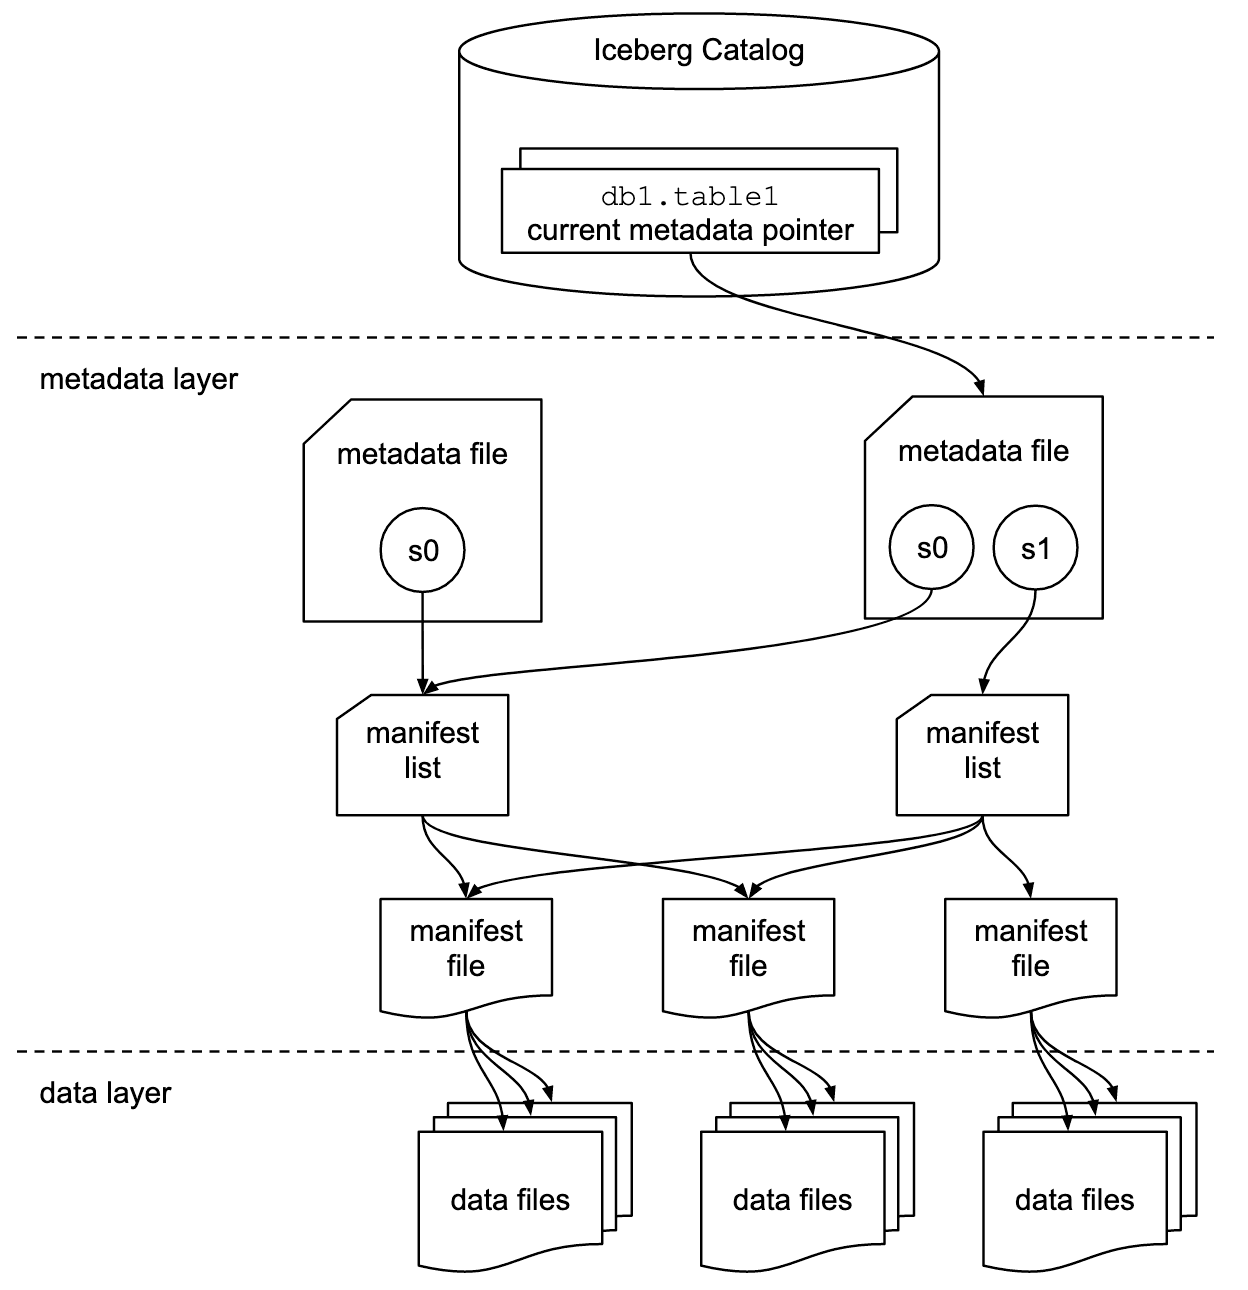
Apache Iceberg: A Table Format for Huge Datasets
Apache Iceberg is an open table format for huge analytic datasets. It adds a metadata layer to files in object storage, enabling engines like Spark and Trino to work with transactional guarantees. The footgun: it's a format, not a query engine itself.
Apache Beam: Write-Once, Run-Anywhere Data Pipelines
Apache Beam is a universal remote for big data engines. You write your pipeline logic once using its SDK, and it translates your code to run on different "runners" like Spark or Flink. The footgun is thinking Beam is an engine; it's an abstraction that.
Apache Flink: Unifying Batch and Stream Processing
Apache Flink treats everything as a stream of data, even finite batches. This unified model lets you process real-time events and historical data with the same logic. Use it for live analytics or fraud detection.
Cloud Unit Economics: Tying Spend to Value
Instead of just a total cloud bill, unit economics calculates cost per meaningful unit, like 'cost per customer.' This helps justify rising costs with business growth and lets product owners make data-driven pricing tradeoffs.
Cost Anomaly Detection: Catching Runaway Cloud Bills
Think of cost anomaly detection as a fraud alert for your cloud bill. It uses machine learning to learn your normal spending patterns and automatically flags unexpected spikes before they become a crisis.
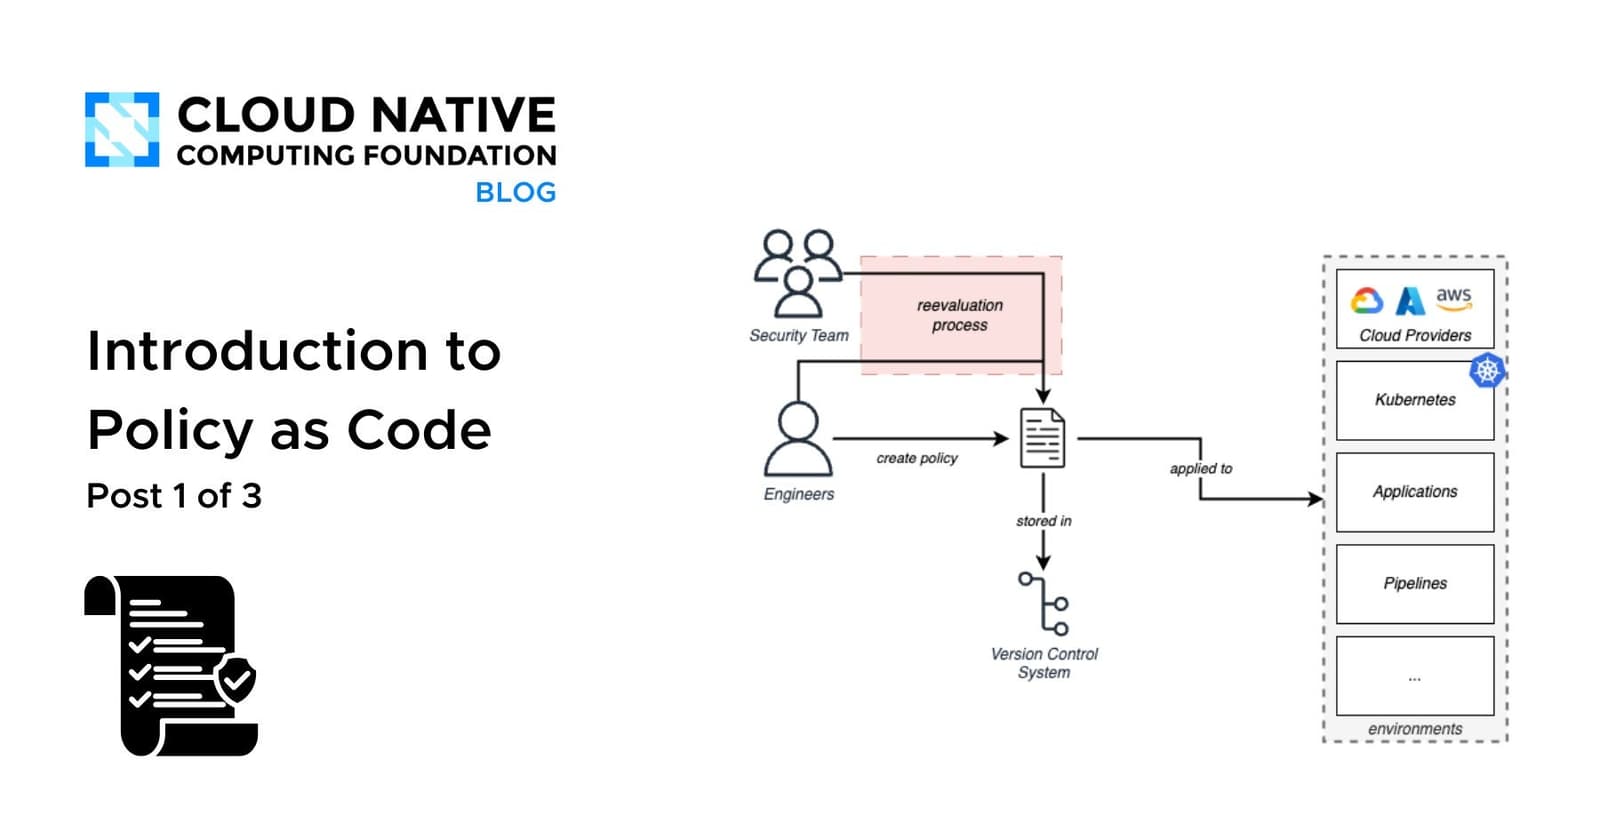
Policy as Code: Rules as Versioned, Testable Code
Policy as Code (PaC) treats rules like code: versioned, tested, and automated. Instead of manual UI clicks, you define guardrails in a declarative language. Use it in CI/CD to block bad deploys or in Kubernetes to enforce runtime rules.
IaC State: The Map Between Your Code and the Cloud
IaC state is the source of truth mapping your code to real-world resources, acting as your tool's memory. Terraform uses a state file to plan updates, while other tools use a service backend. The footgun: never commit state files to Git; they lack locking and.

CQRS: Separate Models for Reading and Writing Data
CQRS splits your application into two parts: one for changing data (Commands) and one for reading it (Queries), often with separate data models. Use it in complex systems with different read/write patterns.
The Saga Pattern: Transactions Across Microservices
The Saga pattern manages transactions across services by chaining local operations. If a step fails, compensating actions undo previous work. It's common in booking systems.
Serverless State Machines: The Conductor for Your Functions
A serverless state machine is the conductor for your microservices, telling each function when to run and how to handle errors. It's built for multi-step processes like ETL pipelines or coordinating parallel tasks. The footgun is creating a visual monolith.

Horizontal Pod Autoscaler (HPA): Scale on Demand
A Horizontal Pod Autoscaler (HPA) is a thermostat for your app's capacity, adding or removing pods based on load. It's used to handle traffic spikes by watching metrics like CPU, but a common footgun is setting aggressive thresholds that cause flapping.
Managed Kubernetes: Your Cloud's K8s Control Plane
A managed Kubernetes service (EKS, AKS, GKE) runs the complex K8s control plane for you, letting you focus on deploying apps, not managing infrastructure. Use it to run containers without the overhead of maintaining masters.
Cloud Native Buildpacks: No More Dockerfiles
Cloud Native Buildpacks turn source code into container images without a Dockerfile. This lets platform teams enforce security and best practices, while app developers just push code. The footgun is assuming they're simple; they're a full build system.
.ebextensions: Infrastructure as Code for Elastic Beanstalk
.ebextensions are config files for customizing the AWS resources in your Elastic Beanstalk environment. Use them to install packages, run commands on instances, or provision related AWS resources.
Immutable Deployments: Treat Servers Like Cattle, Not Pets
Treat servers like cattle, not pets. Instead of modifying live servers, you deploy updates by replacing entire server fleets with new, pre-baked images. This eliminates configuration drift and simplifies rollbacks.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles