Advanced concepts in Computer Vision, page 2
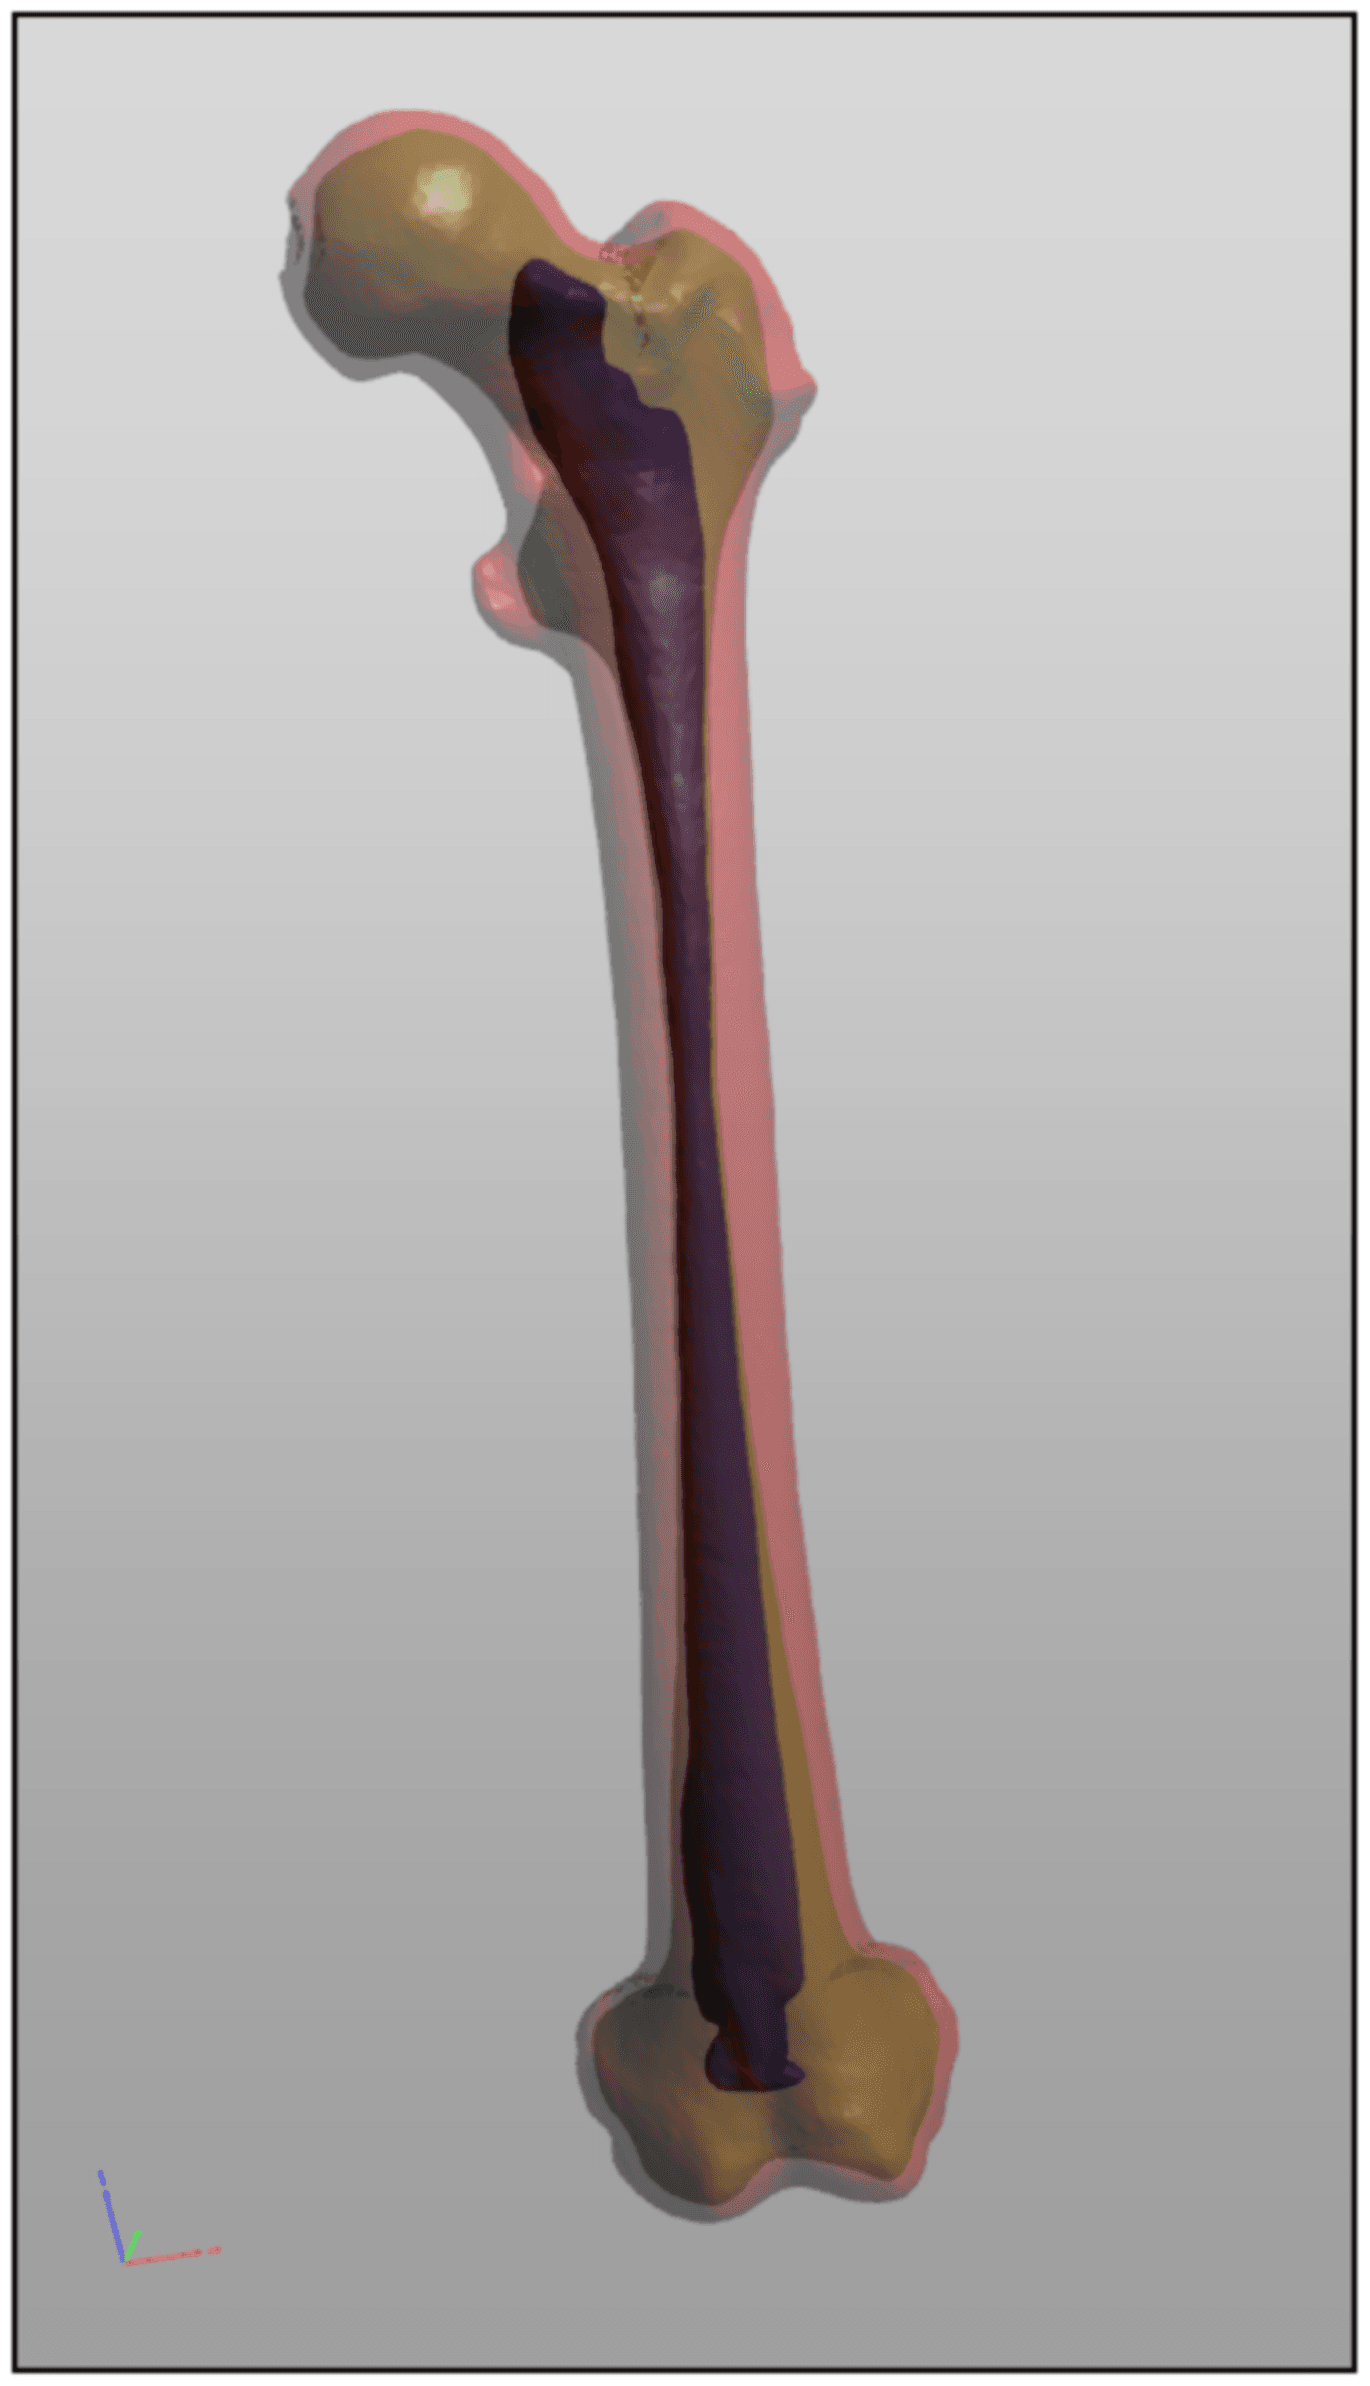
Panoptic Segmentation: A Unified View of a Scene
Panoptic segmentation unifies two tasks: it labels every pixel with a class ('stuff' like road, sky) and also identifies individual object instances ('things' like car 1, car 2). It provides a complete scene understanding for autonomous driving and robotics.
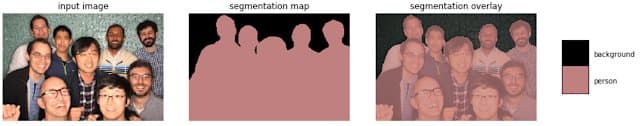
DeepLab: Pixel-Level Semantic Image Segmentation
DeepLab assigns a class label like 'road' or 'person' to every pixel in an image. This powers features like smartphone portrait mode by precisely outlining objects. The key challenge is achieving sharp object boundaries, not just coarse bounding boxes.
Mask R-CNN: Region-Based Detection
Mask R-CNN belongs to the R-CNN family core: selective search over CNN feature maps yields bounding boxes with object categories. Reusing convolutional features for localization, not just classification, is the win.
Conditional Random Fields: Labeling with Context
A Conditional Random Field (CRF) makes predictions that know their neighbors, enforcing that nearby pixels in an image get similar labels. It cleans up raw segmentation outputs by considering local context.
Two-Stream ConvNets: Seeing What vs. How It Moves
Two-Stream ConvNets split video analysis into two paths: a spatial stream sees *what* is in a frame, and a temporal stream sees *how* it moves via optical flow. This is used for action recognition, like telling 'typing' from 'waving'.
Correlation Filters: Fast and Robust Object Tracking
Correlation filters track objects by learning a template that gives a peak response at the object's location. This makes them extremely fast for real-time visual tracking. The footgun: basic versions fail when the object changes scale or is occluded.
Particle Filters for Object Tracking
A particle filter tracks an object by maintaining a cloud of possible states ('particles'), not one best guess. It's used to follow objects through clutter and occlusion, like tracking a face in a crowd.
DeepSORT: Adding Visual Memory to Object Tracking
DeepSORT adds a 'visual memory' to object tracking, using a deep learning model to re-identify objects after they're hidden. It's used in surveillance and autonomous driving to maintain consistent IDs across frames.
Temporal Segment Networks: Seeing the Whole Video Story
Temporal Segment Networks (TSN) understand video actions by sampling sparse snippets across the entire timeline. This gives a model long-range context to distinguish complex actions.
Swin Transformer: Efficient Vision with Shifted Windows
Swin Transformer makes Vision Transformers practical by processing images in local "windows" instead of all at once. It's a powerful backbone for object detection and segmentation where scale varies.
Cross-Attention: How Models Fuse Text and Images
Cross-attention lets a model fuse different data streams, like asking 'what in this image corresponds to this word?'. It's key for text-to-image generation, where text queries attend to image features. The footgun is confusing it with self-attention.
MLP-Mixer: Vision Without Convolutions or Attention
MLP-Mixer shows that simple MLPs can achieve strong vision results, challenging the need for convolutions or attention. It works by alternating between mixing features within image patches and mixing information across patches.
NeRF: Turning 2D Photos into a Walkable 3D Scene
A Neural Radiance Field (NeRF) learns to be a 'ray-tracing oracle' for a scene, predicting color and density from any angle. It's used to create walkable 3D experiences from 2D photos. The footgun: NeRFs can't invent details not in the source images.
Diffusion Models: Generating by Reversing Noise
Diffusion models generate data by learning to reverse a process of adding noise. They power state-of-the-art image generation (DALL-E 2, Stable Diffusion). The main footgun is that their iterative sampling process is slow and computationally expensive.
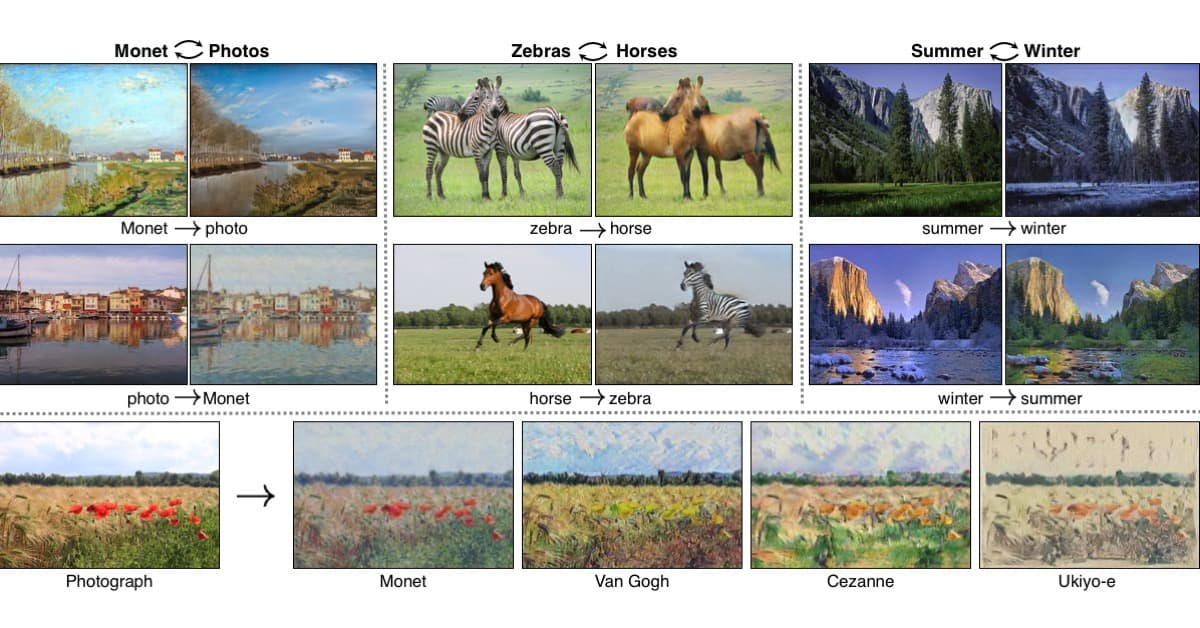
CycleGAN: Image Translation Without Paired Data
CycleGAN translates images between domains (e.g., photos to paintings) without direct 'before' and 'after' examples. It's used for style transfer or turning horses into zebras. The footgun is that it hallucinates details, making it unsafe for critical tasks.
Normalizing Flows: Shaping Simple Distributions into Complex Ones
Normalizing flows transform a simple probability distribution, like a Gaussian, into a complex one, like images. This allows generative models to explicitly calculate the probability of any data point. The footgun is that the transformation must be invertible.
GAN Inversion: Editing Real Photos with Fake Image Generators
GAN Inversion finds the latent code "recipe" inside a pre-trained GAN that best recreates a real image. This lets you use a generator's powerful editing features on real photos for tasks like manipulation or restoration.
Scene Graph Generation: From Pixels to Relationships
Scene Graph Generation (SGG) moves beyond just finding objects in an image; it maps out the relationships between them. This enables deeper scene understanding for tasks like advanced image search.
Visual Servoing: Using Eyes to Guide a Robot's Hands
Visual servoing is like how you reach for a cup: your eyes guide your hand. A robot uses a camera to continuously correct its motion toward a target, closing the loop between seeing and doing. It's key for robotic arms, drones, and surgical bots.
Affordance Learning: Teaching AI What Objects Do
Instead of just naming objects, affordance learning teaches AI to see potential actions—a chair is for sitting, a knob is for turning. This is crucial for robotics, where a machine must know how to interact with novel items.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles