Advanced interview questions in Computer Vision
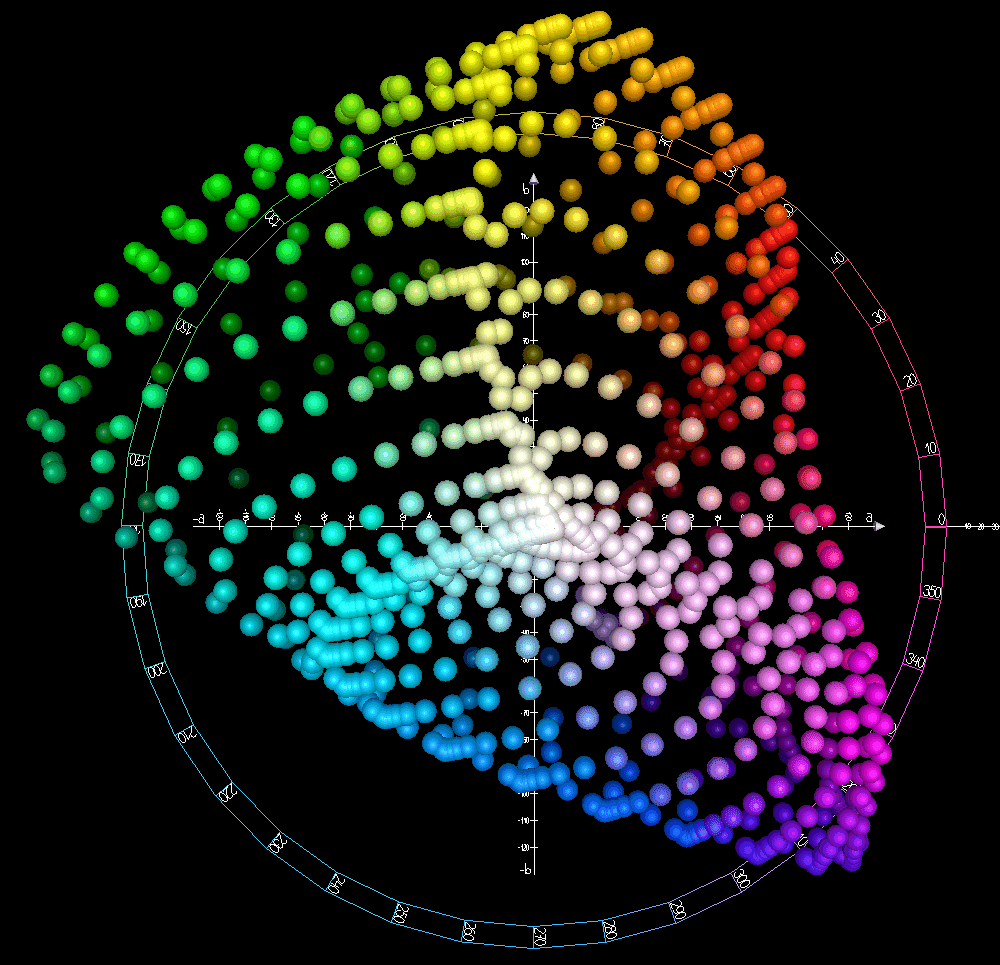
Why is RGB Euclidean distance a poor measure of perceptual color difference?
This tests perceptual uniformity. A good answer explains that RGB distance does not match human vision, then describes CIELAB as a space where deltas approximate perceived differences, making segmentation align with human vision.

Describe the BRDF, its advantage over Lambertian, and critical CV tasks
Tests 4D view-dependent reflectance. Strong answers define BRDF as dL_r/dE_i (sr^-1) over four angles; note Lambertian is isotropic; cite photometric stereo and shape-from-shading where specularity breaks the model. Red flag: calling it albedo.
Image rotation: forward versus inverse mapping
Forward mapping sends source pixels to non-integer destinations, leaving holes and overlaps; inverse mapping iterates over output pixels, finds the source location, and interpolates.

How does filter separability optimize Gaussian blur and its complexity?
This tests if you know a 2D Gaussian separates into two 1D convolutions. A strong answer gives complexity as O(N^2 K^2) dropping to O(N^2 K) for an N-by-N image and K-by-K kernel. A red flag is claiming all kernels are separable or omitting dimensions.
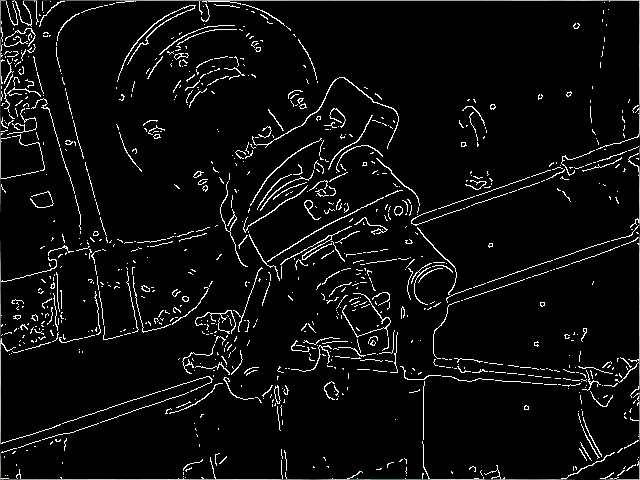
Walk me through Canny edge detection and why it beats Sobel thresholding
Tests multi-scale edge detection and noise robustness versus raw gradient thresholding. Strong answer lists Gaussian blur, Sobel gradients, non-maximum suppression, double thresholding, hysteresis. Red flag: calling it blurred Sobel without hysteresis or NMS.
CNN features for image retrieval
Pass the image through a pretrained CNN and read activations from a late layer as a descriptor; deeper layers encode semantics, earlier layers encode texture.
Feature choice for real-time mobile SLAM
Pick ORB for fast FAST keypoints and cheap binary descriptors matched by Hamming distance; accept reduced robustness versus SIFT for real-time, low-power operation.
Stereo rectification math and its artifacts
Rectification warps both images by homographies so epipolar lines become horizontal and aligned.
Adapting a classification CNN for segmentation
Replace the dense head with conv layers, upsample via transposed convolutions, and fuse encoder skip connections to recover spatial detail lost to downsampling.
Depthwise separable convolution cost savings
Separable conv splits standard conv into per-channel spatial filtering plus a 1x1 pointwise mix, cutting cost by roughly 1/N plus 1/k².
Translation equivariance versus invariance in CNNs
Convolution is equivariant, shifting input shifts feature maps; invariance comes only from pooling and global aggregation. Strict invariance is partial and broken by strided sampling.
Focal Loss and class imbalance in detectors
Focal loss multiplies cross-entropy by a (1-p)^gamma factor that down-weights easy, well-classified examples so the vast easy background does not swamp the loss.
Deploying real-time detection on edge devices
Pick an efficient one-stage detector, train with augmentation, then quantize, prune, and compile to a hardware-accelerated runtime, measuring latency and accuracy tradeoffs.
Detector head losses: regression versus classification
The head splits into a classification branch using cross-entropy over classes and a regression branch using a robust Smooth L1 or IoU loss on box offsets, combined as a weighted sum.
Explain panoptic segmentation and Panoptic Quality
Panoptic assigns every pixel a class and instance id over things and stuff; PQ factors into SQ, average IoU of matches, times RQ, an F1 over matched segments.
Adapting ViT for dense semantic segmentation
Reassemble patch tokens into a 2D feature map, add a decoder, and handle low resolution plus quadratic attention cost.
Self-supervised pretraining for video understanding
Define a label-free task like temporal order prediction or contrastive clip matching that forces temporal reasoning, then fine-tune on labeled action data.
Scene flow versus optical flow
Optical flow is 2D pixel motion in the image plane; scene flow is the 3D motion field of points in space, needing depth via stereo, RGB-D, or LiDAR.
Core principles of a Neural Radiance Field
An MLP maps a 3D point plus view direction to color and density; novel views render by casting rays, sampling points, querying the MLP, and volume-integrating along each ray.
Pure ViT vs hybrid CNN-Transformer for medical segmentation
Pure ViT captures global context but is data hungry and weak on local detail; hybrid CNN-Transformer gets local features cheaply plus global attention, ideal for scarce…
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles