Intermediate concepts in Data Science & Analytics, page 4
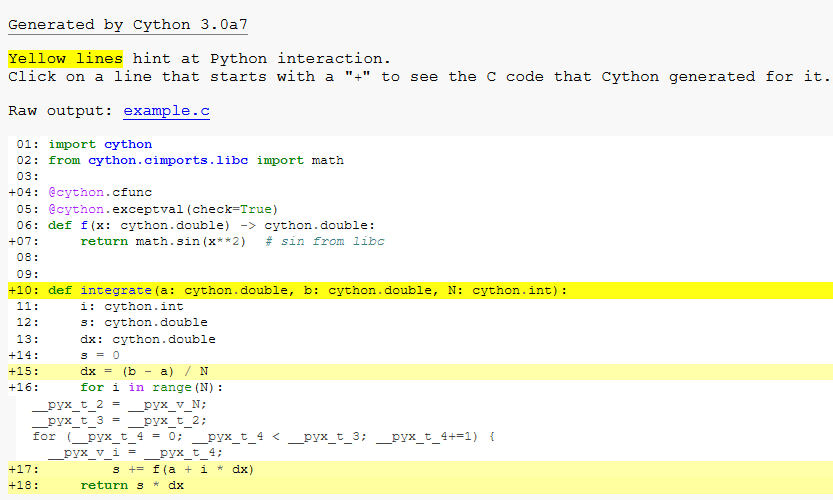
Cython: Static Typing for Faster Python
Cython speeds up Python by compiling it to C, especially when you add static types to bypass Python's dynamic overhead. Use it for CPU-bound bottlenecks like tight loops in numerical code.
Missing Data Imputation: Filling in the Blanks
Instead of deleting rows with missing values, imputation makes an educated guess to fill the blanks, preserving your sample size. It's used in survey analysis or time-series data where dropping records would introduce bias.
Log Transformation: Taming Skewed Data for Better Models
A log transform tames skewed data by compressing large values and spreading out small ones. It's used on data like income or web traffic to help it meet the assumptions of linear models. The footgun: it fails on zero or negative values.
Idempotency: Making Data Pipelines Retry-Safe
Idempotency means an operation has the same effect whether run once or multiple times, like closing an already-closed door. It's essential for data pipelines where retries are common. The footgun is assuming retries are safe, leading to data corruption.
Data Pipeline Orchestration: Beyond Cron Jobs
Data pipeline orchestration is the conductor for your data workflows, ensuring tasks run in the right order with full dependency awareness. It manages complex chains, like triggering analytics only after an ETL job succeeds.
Spark DataFrame API: SQL Smarts on Distributed Data
The DataFrame API is like giving Spark a schema for your distributed data, letting its Catalyst optimizer plan queries like a database would. Use it for structured data processing with column-based operations.
Data Partitioning: Spreading Data for Scalability
Partitioning splits a huge dataset across many machines, like assigning phonebook sections to different librarians. This allows systems to scale beyond a single server.
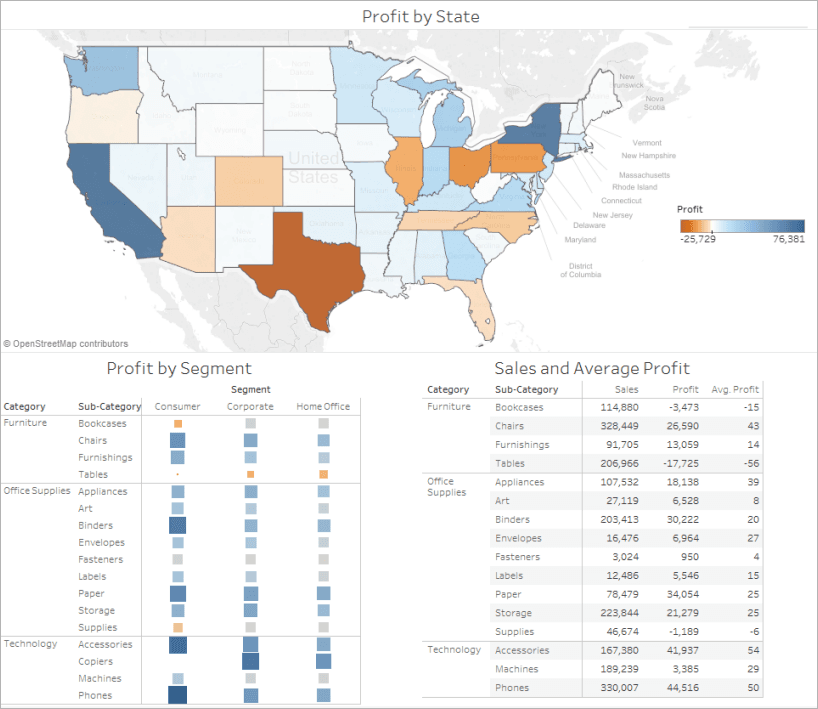
Dashboard Design: Guide, Don't Overwhelm
A good dashboard guides users to an insight, not just displays charts. Place your key takeaway in the top-left and limit views to 2-3 to maintain focus. The biggest mistake is including too many views, which clutters the message and slows down the dashboard.
Data Sonification: Hearing Your Data's Story
Data sonification is data visualization for your ears, mapping data points to sound properties like pitch or volume. It helps find patterns in complex datasets, like network traffic, where visuals fail.
How a SQL SELECT Query Actually Runs
A SQL SELECT query runs in a different order than you write it. It first builds the dataset with FROM/JOINs and filters it with WHERE, only then computing the final columns in SELECT. This is crucial for debugging.
The Big Idea: Your Presentation's Single-Sentence Core
The "Big Idea" is a single sentence distilling your presentation's core message. It must state your point of view and what's at stake, telling your audience what to know and what to do.
Python Virtual Environments
A virtual environment is an isolated Python installation with its own packages, so each project gets the exact dependency versions it needs without conflicting with other projects or the system Python.
Vectorization: Ditch the Python Loop
Vectorization means issuing one batch command to C-backed arrays instead of looping in Python. Use it for million-row DataFrames or matrix math. The footgun is treating apply() as vectorized, or silently materializing giant temporaries that exhaust RAM.
Spark Structured Streaming: Unify Batch and Stream
Spark Structured Streaming treats a live stream as an unbounded DataFrame. It unifies batch and streaming ETL on Kafka, but the footgun is confusing event time with processing time without watermarks, which silently drops late data.
ML Model Registry: Source of Truth for Production Models
A model registry is version control for trained models, not just code. It tracks which artifact is running in production, who approved it, and how it was built. Skip it and you get untracked files in S3 with no way to reproduce a production model.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles