Advanced everything in Growth & Experimentation
When user-level A/B tests get contaminated
Network or marketplace spillover violates SUTVA, so randomize by cluster (geo, group, time) and analyze at that level.
Build an opportunity-sizing model before building
Locate the affected funnel step, estimate addressable population times a bounded conversion lift times value per user, then sanity-check against a realistic ceiling.
Architect an experimentation dashboard for culture
Searchable experiment repository, structured hypotheses, results regardless of outcome, and cross-team discovery.

Compare server-side and client-side experimentation architectures
This tests rendering-layer architecture. A strong answer contrasts server-side zero-flicker and algorithm tests against client-side marketer agility and SEO safety, mapping each to release cycles. A red flag is claiming one approach dominates every dimension.
How do you mitigate peeking in experiment infrastructure?
Lock results behind minimum samples; auto-correct via sequential testing; hide early metrics and require stop approval.
Design a pre-aggregation architecture for low-latency experiment results
Tests OLAP-at-scale trade-offs. Strong answers design streaming rollups into a real-time OLAP store, use partial cubes for high-cardinality dimensions, and retain raw events.

Design a system to reduce large client-side experiment payload size
Tests edge evaluation and payload compression. Use server-side pre-evaluation or edge nodes sending only assigned variants; compact bucketing indexes or Bloom filters; lazy-load noncritical experiments. Never do full client-side evaluation of every flag rule.
Describe a strategy for reconciling different forecasts into one robust prediction
Tests synthesis of heterogeneous models into a consensus forecast. Strong answers diagnose divergence drivers first, then weight by track record or uncertainty, and output a distribution. Red flag: blind averaging without understanding why models disagree.
How would you adapt a growth model for network effects and k-factor?
Define K as invites x conversion; K over 1.0 explodes, yet K over 0.7 with fast cycle time still compounds; anchor at peak delight.

What data pipelines and infrastructure feed a viral user acquisition model?
Tests causal attribution architecture. Great answers cover invite instrumentation with identity resolution, streaming pipelines that split organic and viral signups, and feature stores for network-state features.

Architect real-time usage-based billing for a PLG company
This tests event-driven metering, idempotent aggregation, and pricing decoupling at scale. A strong answer outlines real-time ingestion, stream processing for micro-events, a rules-based pricing engine, and dashboards with reconciliation.
Design a multivariate experimentation platform with collision-free concurrent bucketing and cross-device consistency
Tests orthogonal layers and cross-session assignment persistence. Cover: deterministic hashing per layer, a user profile service for sticky bucketing, and stable ID resolution across devices. Red flag: random bucketing or local storage breaking consistency.
How would you design international monetization with multi-currency and tax?
Localized pricing, jurisdictional tax, gateway routing, async reconciliation.
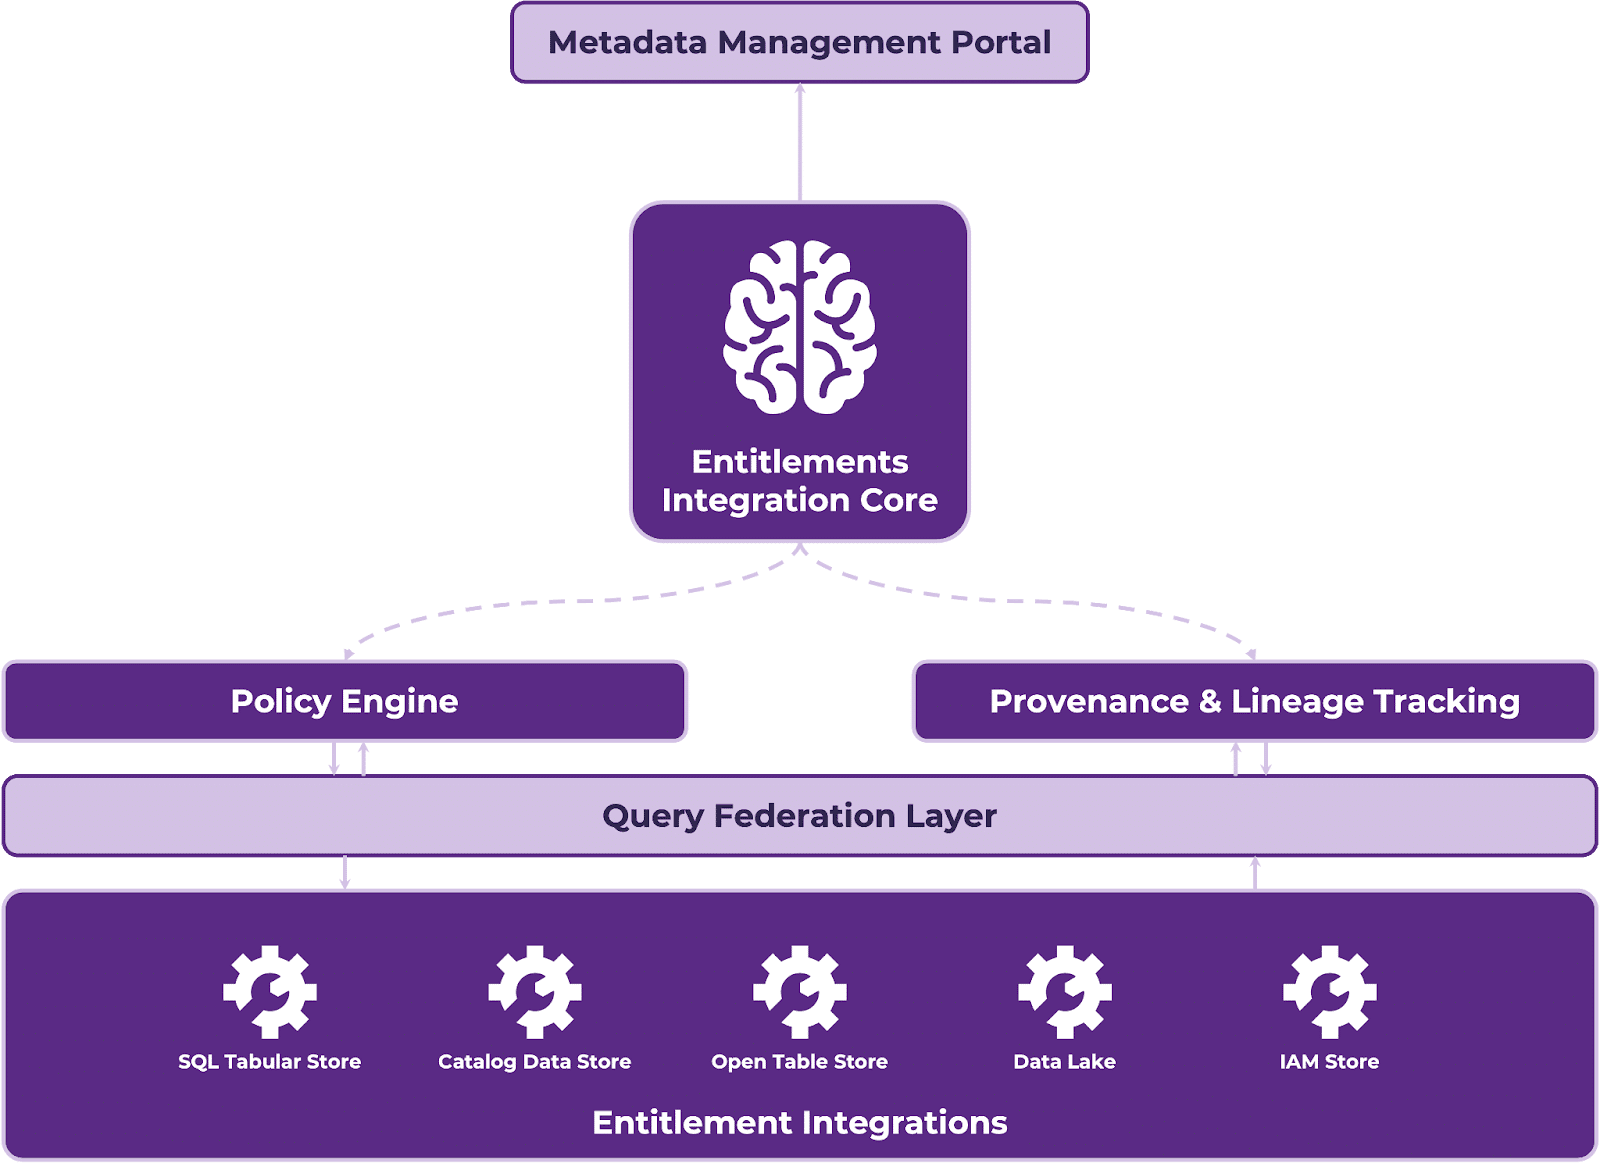
Design a highly available entitlements service with caching
This tests balancing read performance with consistency in access control. A strong answer proposes tiered caching with proactive invalidation, read-optimized hot paths, and event-sourced temporary grants.

Design a real-time personalized notification trigger system
Stream events to a delayed queue, expose a rule UI to non-technical users, and deliver idempotently.
Long-term onboarding holdback: technical and data integrity challenges
This tests the engineering cost of year-long holdbacks in growth. A strong answer covers feature-flag entropy, pipeline drift, survivorship bias, and counterfactual validity. Red flag: treating the holdback as static config that never rots.
Design a programmatic SEO system for 1 million landing pages
Tests data infrastructure thinking, not content generation. Covers one-row-one-page schema, template rendering with edge caching, hierarchical routing, and crawl-budget controls via sitemaps. Red flag: AI bulk writing without structured data or caching.

What is the multiple comparisons problem and how to correct?
This tests your grasp of family-wise error inflation across many tests. A strong answer defines the problem, contrasts per-comparison and family-wise error, and names corrections like Bonferroni or FDR.

WAU is flat despite positive A/B tests; why and how to diagnose
This tests distinguishing real impact from statistical artifacts. Strong answers cite false positives from low base rates, peeking, novelty, and local-global mismatches. Diagnose with long-term holdouts, audits, and causal bridges.

How would you structure your growth team's experimentation portfolio?
3 asset classes (iterative 30-70%, tech investments, big bets 20-40%), use expected value per week, and evolve the mix.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles