Concepts in LLMs & Generative AI, page 4
Large Multimodal Models (LMMs): Beyond Text
An LMM is like a large language model that can also see and hear. It processes and connects information from multiple sources—like text, images, and audio—to perform tasks like describing a picture or answering questions about a video.
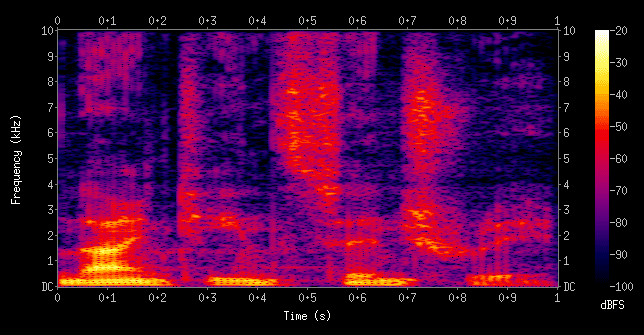
Audio Spectrograms: Turning Sound into Images for AI
A spectrogram turns sound into an image, plotting frequency against time, with color showing intensity. This lets vision-based AI models "see" audio for tasks like speech recognition or music generation. The footgun is mistaking it for a simple waveform.
Text-to-Speech (TTS): Turning Text into Spoken Audio
Text-to-Speech (TTS) systems are digital voice actors, converting written language into artificial human speech. They are the core of any system that needs to speak text aloud.
BLIP: Bootstrapping Better Vision-Language Models
BLIP is a pre-training framework that masters both image understanding and generation by creating its own training data. It uses a captioner and filter to generate clean image-text pairs from noisy web data.
Flamingo: Few-Shot Learning for Vision-Language Models
Flamingo is a vision-language model that learns new visual tasks from a few examples, like a child seeing a picture book before the zoo. It can tackle multiple tasks without needing massive, task-specific datasets.
Text-to-Video Generation: From Prompt to Picture Show
Text-to-video models are like a film director in a box, turning written descriptions into moving pictures. This tech, powered by video diffusion models, is used for creating short-form content or prototyping visual ideas from a simple text prompt.

Human Evaluation: Judging AI When Metrics Aren't Enough
Human evaluation is the ultimate reality check for AI, using people to judge qualities like fluency and coherence that automated scores can't capture. It's essential for tasks like summarization but is too slow and costly to use for everything.
Inception Score: Judging AI Art for Quality and Variety
Inception Score judges an AI image generator on quality and variety, using a classifier to check if images are distinct and the overall set is diverse. Its main footgun is that it only measures what another AI can classify, not what a human finds appealing.
HellaSwag: A Benchmark Designed to Fool LLMs
HellaSwag is a commonsense benchmark designed to fool language models. It asks an AI to pick the most logical sentence ending, but the wrong answers are specifically generated to trick machines, not humans. It's used to test for true contextual understanding.
BERTScore: Judging AI Text on Meaning, Not Just Words
BERTScore evaluates AI-generated text by comparing its meaning to a reference, not just matching words. It's used to score machine translation or summarization where phrasing can vary.
MMLU Benchmark
MMLU (Measuring Massive Multitask Language Understanding) is a popular benchmark for evaluating large language models. Its influence is shown by its many spin-offs, making it a foundational tool for comparing AI capabilities.
Why Elo Ratings for LLMs Can Be Misleading
Elo ranks LLMs like chess players, but models have fixed skills, not dynamic ones. This method powers leaderboards but produces volatile scores, meaning a model's rank can be an unstable estimate of its true, unchanging ability.
LLM-as-a-Judge: Using Models to Grade Models
Instead of paying humans to rate AI outputs, LLM-as-a-Judge uses a powerful 'judge' model to do it automatically. This is used to evaluate chatbot responses or summarization quality, but the main footgun is assuming the judge model is unbiased or perfectly…
HumanEval: Testing if AI-Generated Code Actually Works
HumanEval is a benchmark that tests if an LLM's generated code is functionally correct, not just syntactically valid. It's used to compare models like Codex by having them solve programming puzzles.
The AI Alignment Problem
AI alignment is about making sure an AI pursues our intended goals, not just the literal instructions. It's critical for autonomous systems in medicine or finance. The footgun is assuming a clear objective prevents unintended, harmful outcomes.
Model Cards: The 'Nutrition Label' for AI Models
A model card is the nutrition label for an AI model, summarizing its ingredients, intended use, and risks. Found in model repos, it details training data, performance, and ethical guardrails.
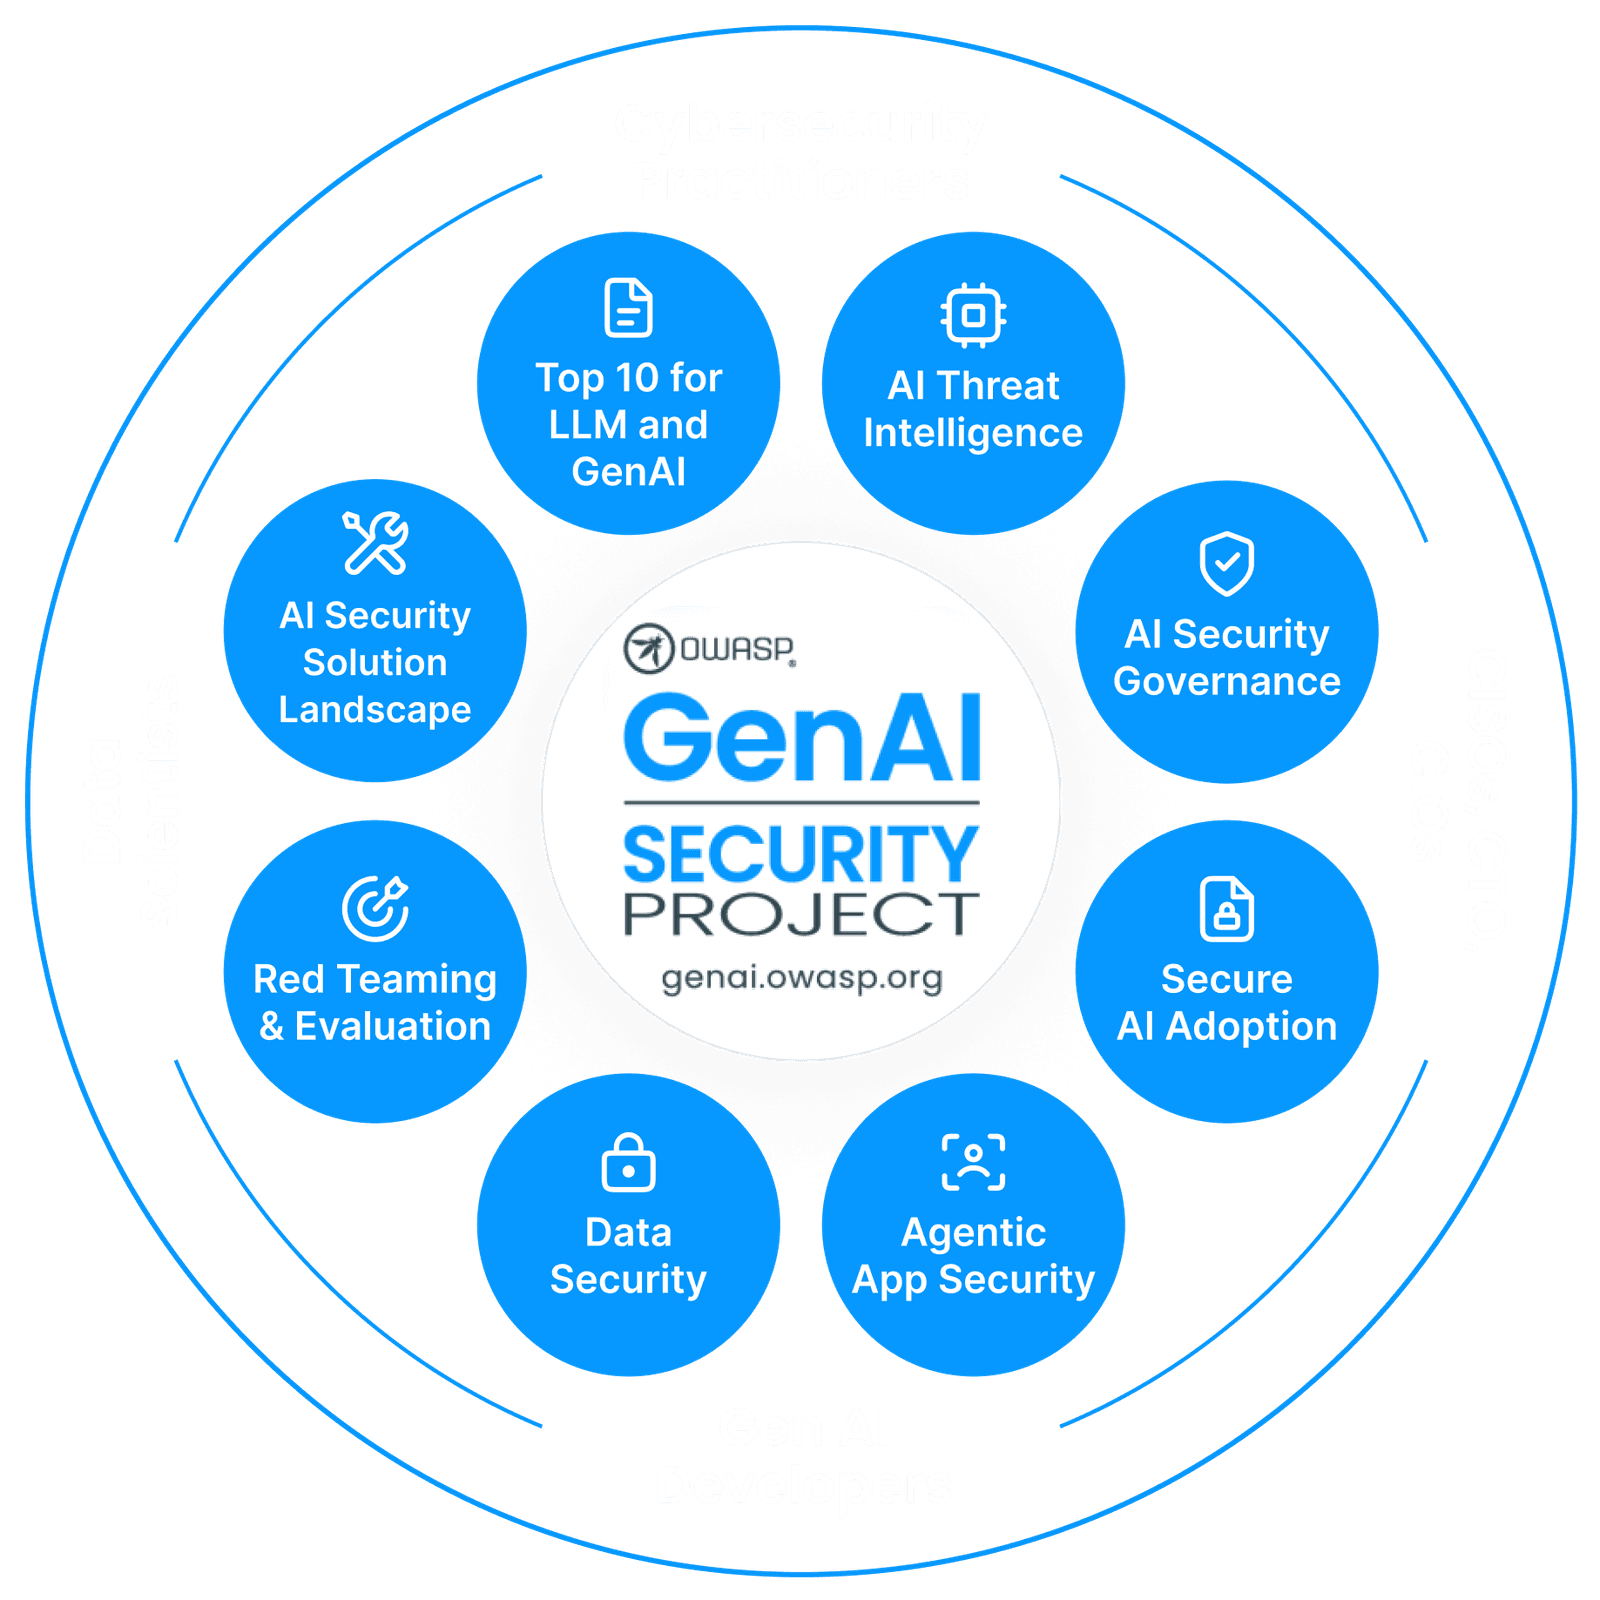
LLM Red Teaming: Adversarial Security Testing
LLM Red Teaming is a simulated attack where you proactively try to break your own AI to find security flaws. It's used to test for vulnerabilities like prompt injection or data leakage, which traditional security tools miss.
LLM Guardrails: Keeping Model Outputs on Track
LLM guardrails are safety policies that steer model outputs, acting like bumpers in a bowling alley to prevent responses from going off-topic, leaking data, or generating harmful content. They are crucial for topic control and preventing prompt injections.
Adversarial Attacks: Tricking LLMs into Misbehaving
Adversarial attacks are inputs designed to trick an LLM, bypassing its safety alignment. This is how "jailbreaks" coax models into generating harmful content. The footgun is assuming safety training makes a model foolproof; it just makes attacks more subtle.
ML Interpretability: Cracking Open the Black Box
ML interpretability cracks open the 'black box' to explain *why* a model made a specific decision. It's essential in high-stakes fields like finance or medicine to ensure automated decisions are fair. The footgun is trusting accuracy alone.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles