Interview questions in MLOps & Infrastructure, page 4
Deploy a trained model as a containerized REST API
This tests practical MLOps fluency. A strong answer covers loading the artifact, wrapping it in a web server, building a Dockerfile, and exposing health and predict endpoints. Red flag: conflating training with serving or omitting resource limits.
How would you systematically diagnose high latency in an online inference service?
Check p90/p99 and TTFT to split queuing from compute; inspect queue depth, batch size, GPU, and benchmarks; check cache.
Explain model quantization, its benefits, drawbacks, and validation approach
Tests precision trade-offs in production. Answer: define lowering weights from fp32 to int8/int4; cite memory and latency gains versus accuracy loss; validate with downstream benchmarks and shadow A/B. Red flag: treating as lossless or skipping task metrics.
How would you design an A/B test for two live ML models?
Tests production experimentation rigor beyond random splitting. Strong answers cover: consistent user hashing for sticky assignment, isolated feature stores, guardrail metrics, and pre-calculated statistical power.

Design cost-effective inference for spiky traffic without idle GPUs
Tests designing inference that cuts idle GPU cost during troughs yet handles spiky peaks with low latency via SageMaker blue/green fleets, production variants, and CloudWatch baking periods. Red flag: always-on GPU pools with naive auto-scaling.
Design a multi-model serving architecture for infrequently used models
Tests sparse-traffic cost efficiency via shared compute and dynamic loading. Strong answers: LRU cache on fast storage, scale-to-zero with async preload, pinned hot models, per-model quotas.

Differences between monitoring a traditional REST API and a production ML model
Contrast latency/errors with ML signals like data drift and training-serving skew against baselines, noting ground truth delays.
Detecting data drift on a continuous feature
Data drift is when serving feature distributions shift from training; detect with a Kolmogorov-Smirnov test comparing distributions; a small p-value signals drift to alert on.

Design a system to monitor a real-time prediction service for feature drift
Async feature logging, distribution comparison via PSI/KS against training baseline, and threshold-based anomaly alerts.
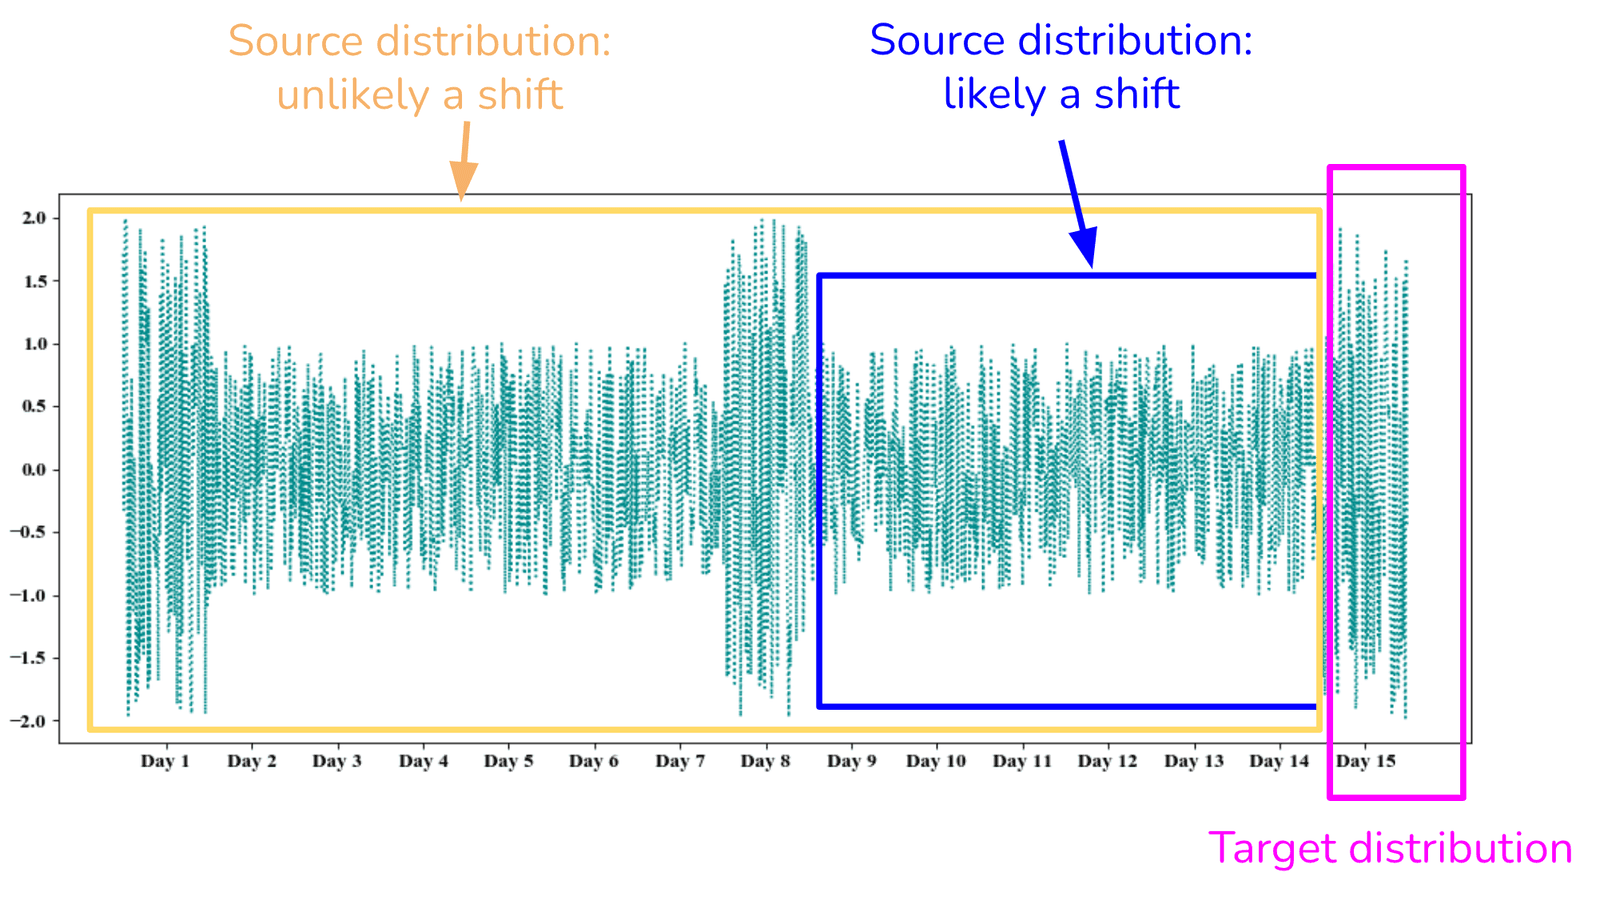
Model output distribution shifts. What are root causes and next steps?
This tests covariate vs label shift vs concept drift when outputs shift. A strong answer checks features before labels, then feedback loops or staleness. A red flag is generic drift without separating P(X), P(Y), and P(Y|X).
Design an automated system to diagnose model performance drop root causes
Tests causal attribution between pipeline bugs and drift. Strong answers sequence schema/null audits, feature drift via PSI/KS, then concept drift via holdout decay. Red flag: skipping pipeline checks to retrain immediately.

How do you monitor thousands of per-customer models as a fleet?
Tests fleet-level statistical aggregation versus per-instance alerting. Strong answers propose tiered telemetry, cohort baselining for drift, and hierarchical alerting to prevent fatigue.
Stages of an end-to-end ML pipeline
Ingest, validate, preprocess and feature engineer, train, evaluate against a baseline, then register and package for deployment, with gates between stages.
What triggers automatic full retraining in an ML pipeline?
A strong answer lists four triggers: fresh data, code changes, model drift, and scheduled cadence.
How would you implement automated data validation before training?
Enforce schema contracts, halt training on failure, quarantine bad batches, and alert owners.
How do you programmatically promote a retrained model to production?
Compare on held-out data using significant metric uplift, schema, latency, and drift checks before shadow release.

Design concept drift detection with automated retraining safeguards
Baseline monitors raise CloudWatch alarms; EventBridge triggers retraining with cooldowns; model registry gates promotion.
How would you architect dynamic training resource provisioning?
Routes jobs to right-sized instances, provisions managed jobs using spot, and auto-tears down on completion.
Automated rollback for a failed model deploy
Detect failure via health and metric checks, automatically route traffic back to the last known-good version (blue-green or canary), keep the registry entry but unpromote, and alert.
What are the essential components of an end-to-end ML platform?
Tests mapping the ML lifecycle to infrastructure. A strong answer walks through six stages: data ingestion, feature store, training pipeline, model registry, deployment/serving, and monitoring with feedback loops.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles