All bites
The whole library, newest first. Filter by what you are here for, or pick a topic if you already know.
8667 bites
Page 306
Data Schema Evolution: Changing Your Data's Blueprint
Schema evolution is like updating a building's blueprint while it's occupied. You must change your data's structure without breaking apps or losing data. It's key for adding features that need new DB columns.
ELT: Load Raw Data, Transform in Place
ELT flips the data pipeline: load raw data first, then use the data warehouse's own power to transform it. It's used in ML feature pipelines. The footgun is assuming it's ETL; with ELT, the transformation logic is coupled to the warehouse's SQL engine.
Data Labeling: Teaching Machines What to See
Data labeling gives raw data meaning so a machine learning model can learn. It's used to prepare datasets for tasks like object detection in images or sentiment analysis in text. The footgun: low-quality labels directly limit your model's performance.
Data Lake vs. Data Warehouse: Raw vs. Refined Data
A data lake is a vast pool of raw data; a data warehouse is a library of refined data ready for analysis. Lakes store everything for future ML or data science; warehouses power BI reporting on clean metrics.
ML Metadata: The Logging Layer for ML Pipelines
ML Metadata is the logging layer for your ML pipeline, tracking every dataset, hyperparameter, and model version. It's crucial for debugging failed runs by tracing a model back to its exact data.
Data Drift vs. Concept Drift: When Models Go Stale
Your ML model's accuracy decays when the real world no longer matches its training data. This is drift. It happens when user behavior changes (concept drift) or input data distributions shift (data drift).
Continuous Training: CI/CD for ML Models
Continuous Training (CT) is a CI/CD pipeline for models, not code. It automatically retrains and redeploys models to fight performance decay from changing data, a problem known as 'data drift'. The footgun is deploying a new model without validating it first.
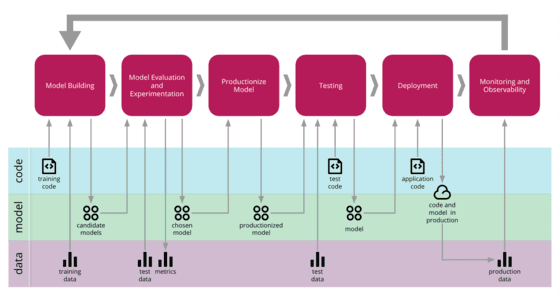
CD4ML: Automating ML from Data to Deployment
CD4ML extends CI/CD to manage ML's three axes of change: code, data, and models. It automates the entire lifecycle, enabling reliable updates for systems like sales forecasting.
Data Versioning: Git for Your Datasets
Think of data versioning as Git for datasets. It tracks changes to your data, allowing you to reproduce ML experiments or roll back to a previous state. The footgun is using regular Git, which chokes on the large binary files common in ML.
ML Experiment Tracking: Your Model's Lab Notebook
Think of it as a lab notebook for your models, logging every parameter and result. It's essential when tuning hyperparameters or comparing architectures, preventing you from losing track of what worked.

MLOps vs. DevOps: More Than Just "DevOps for ML"
Think of MLOps as DevOps extended for machine learning. While DevOps automates code deployment, MLOps also handles the unique lifecycle of data and models, including retraining and monitoring for performance decay.
Open LLM Leaderboard: Separating Hype from Performance
The Open LLM Leaderboard is the de facto scoreboard for open-source models, providing reproducible benchmarks to cut through marketing hype. It helps you compare models on standardized tests, but remember that a high rank doesn't guarantee performance on your…
AI Coding Assistants: Your LLM Pair Programmer
AI coding assistants are like pair programmers powered by large language models. They assist in tasks across the software lifecycle, from code generation and testing to debugging and documentation. The key footgun is over-reliance; they assist, not replace.
AI's Dual-Use Problem: Good Tools, Bad Outcomes
AI models built for good can be easily repurposed for harm. A language model that helps with coding can also generate malware. The footgun is assuming good intentions prevent misuse; the risk is in the capability, not the creator's intent.
Quantization-Aware Training (QAT): Forcing Models to Learn While Quantized
QAT forces a model to "learn its own compression" by simulating quantization during training. This lets you shrink LLMs to aggressive low-bit formats (like 4-bit) where simpler post-training methods fail.

Dynamic Batching: Balancing LLM Throughput and Latency
Dynamic batching groups LLM requests like a bus that leaves on a schedule or when full, whichever comes first. This improves throughput in inference servers by avoiding long waits. The footgun: all requests in a batch are still held hostage by the slowest one.

Model Pruning: Making LLMs Smaller, Not Dumber
Model pruning is surgical weight loss for an LLM, removing neurons or layers to reduce its size. It's used to create smaller, faster versions of models like LLaMA for efficient deployment. The footgun: naive pruning can cripple the model's core capabilities.
Modality Gap: When Multimodal LLMs Don't Trust Their Senses
A multimodal LLM has a modality gap when it trusts one input type (like text) over another (like images), even with identical information. This bias causes performance drops, like ignoring visual data if conflicting text is present.
Full Fine-Tuning: Updating Every Model Parameter
Full fine-tuning updates all weights of a pre-trained model on your new data, unlike methods that only change a small fraction. Use it to deeply embed new knowledge, but beware: it's costly and risks making the model forget its original general skills.
LLMs as Tool Makers: Write Once, Solve Many
LLMs can create their own tools, not just use them. A powerful model writes a reusable function once, and a cheaper model calls it many times. This gives top-tier results at a lower cost for repetitive tasks.