Advanced concepts in AI & ML, page 3
Secrets Management: Beyond Environment Variables
Treat secrets like cattle, not pets: they should be temporary and replaceable. Use a central vault to dynamically inject credentials into apps at runtime, especially in CI/CD and containerized environments.
Scraping Dynamic Sites: Find the API, Not Just Render
To scrape a dynamic site, find the hidden API call its JavaScript makes to fetch data instead of rendering the whole page. This is faster and more reliable. This applies when your scraper gets empty HTML but you see data in your browser.
Nix: Reproducible Builds Through Functional Package Management
Nix treats system configuration like pure functional programming, ensuring reproducible builds by isolating every package into a unique, immutable path. It's used for reliable CI/CD and consistent dev environments. The footgun is its steep learning curve.

Streaming Ingestion: Catching Data as It Happens
Streaming ingestion is a conveyor belt for data, catching events as they happen instead of in batches. It's used for real-time fraud detection and IoT monitoring. The footgun is confusing ingestion (getting data in) with processing (acting on it).
Eight-Point Algorithm: Finding Geometry from Image Pairs
The Eight-Point Algorithm finds the geometric relationship between two camera views of the same scene. Given at least eight matching points, it estimates the essential or fundamental matrix.
Adapter Modules: Efficient LLM Fine-Tuning
Adapters are small modules plugged into a frozen LLM to avoid costly full fine-tuning. This lets you specialize a base model for many tasks by training tiny, swappable plugins instead of duplicating the entire model for each task.
gRPC: High-Performance RPC with Contracts
gRPC is a typed, high-performance function call between services. Instead of crafting JSON, you define a contract and gRPC handles the efficient binary transport. It's for low-latency microservice communication.
Bundle Adjustment: Jointly Refining 3D Scenes and Cameras
Bundle adjustment is a grand negotiation, simultaneously refining a 3D scene, camera poses, and lens properties to best explain the 2D images. It's the final polish in Structure from Motion (SfM) or SLAM.
Proximal Policy Optimization (PPO): Stable RL Updates
PPO prevents destructive updates in reinforcement learning by "clipping" how much a policy can change at once, like a governor on an engine. It's a default for training LLMs with RLHF or robotics agents where stability is key.
Log Aggregation and Parsing: From Chaos to Clarity
Log aggregation gathers scattered system events into one place; parsing turns that raw text into structured, searchable data. This is essential for debugging distributed systems or analyzing security incidents.
SLAM: Mapping a Room While You're Still In It
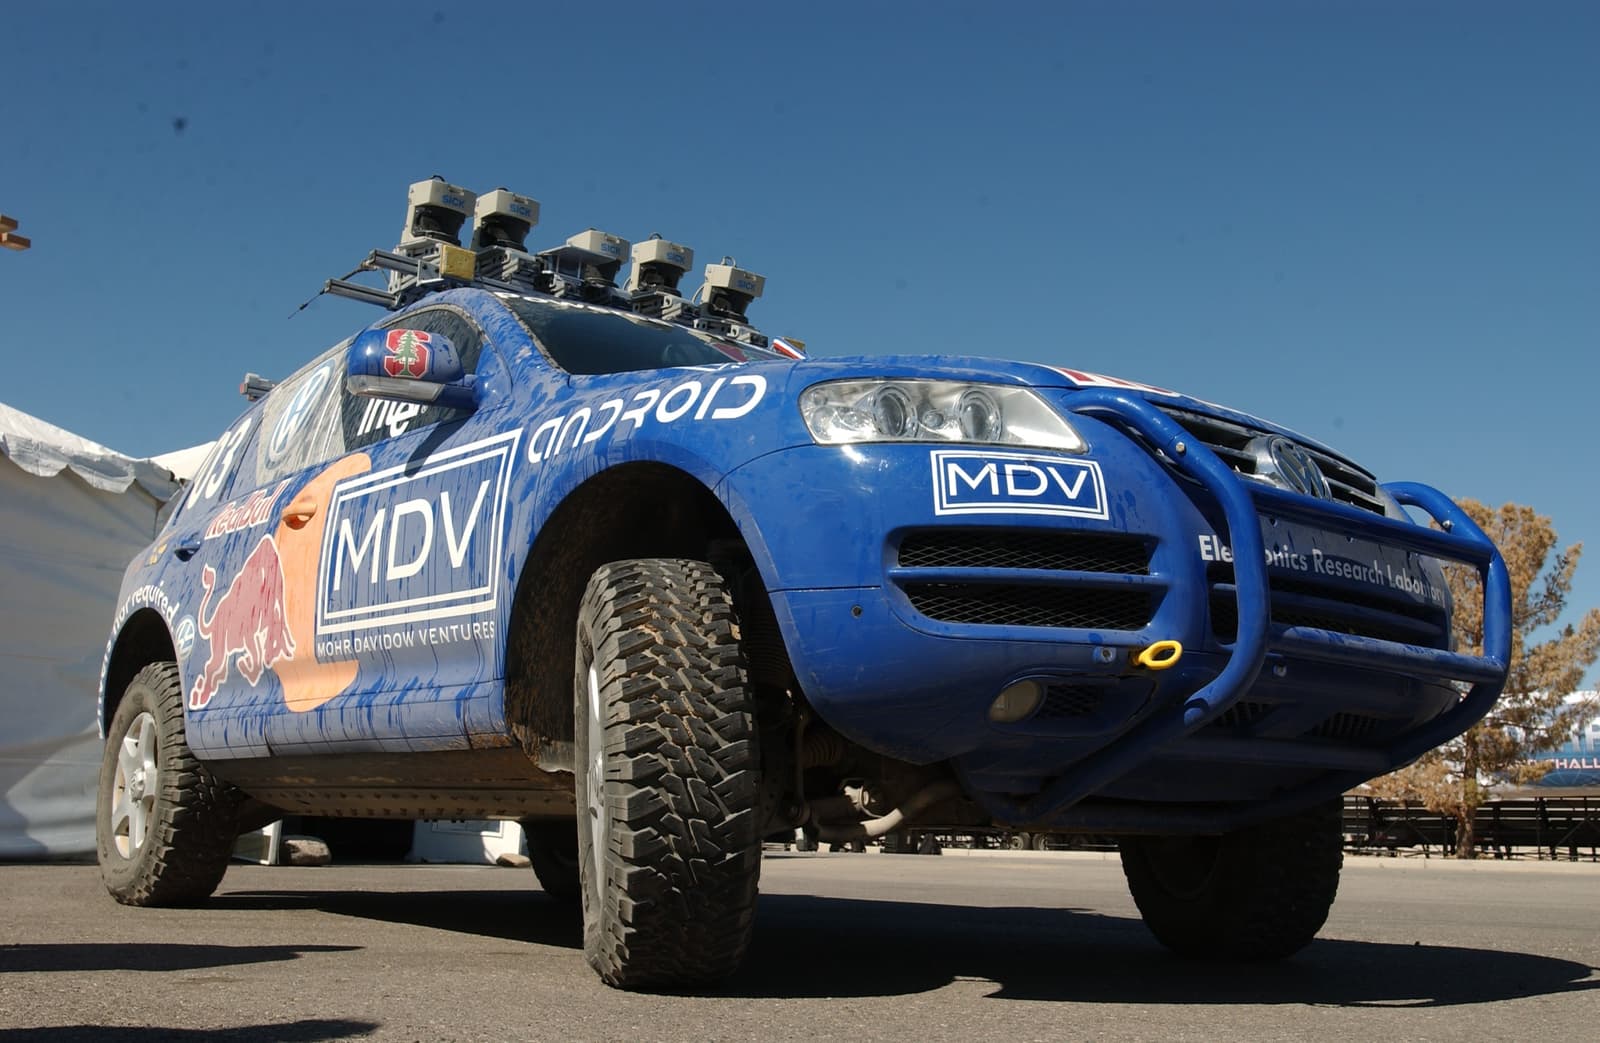
SLAM solves a chicken-and-egg problem: you can't map a space without knowing your location, and you can't know your location without a map. It does both at once. It's used by robots and AR headsets to navigate.
QLoRA: Finetune Huge LLMs on a Single GPU
QLoRA lets you finetune massive LLMs on one GPU by freezing the model in a 4-bit state and only training tiny adapter layers. Use it to adapt a 65B model with limited hardware. The footgun: performance hinges on high-quality data, not just the technique.
Feature Engineering: Better Inputs, Better Models
Feature engineering preps raw data for a model, like a chef preps ingredients. It transforms raw inputs into a more effective set of predictive signals. The footgun is creating irrelevant features, which can harm model performance more than using raw data.
All-Reduce: Synchronizing Parallel Workers
All-Reduce lets parallel workers agree on a global result. Each worker contributes data, an operation (like sum) runs on all data, and every worker gets the final answer. It's the core of distributed ML training, used to average gradients across GPUs.
Self-Querying Retriever: Let an LLM Write Its Own Filters
A self-querying retriever uses an LLM to turn a natural language question into a structured query with metadata filters. It lets users ask things like "Find documents about Python from before 2020," which a simple vector search can't do.
Box-Cox Transformation: Forcing Skewed Data to Look Normal
The Box-Cox transformation is a statistical lens that reshapes skewed data to better resemble a normal distribution. It helps meet the assumptions of models like linear regression, but it only works on positive data and complicates direct interpretation of…
Microsoft DeepSpeed: Training Massive Models Across GPUs
DeepSpeed trains models too big for one GPU by partitioning model states across many devices. It's essential for training foundation models like BLOOM, but its complexity is overkill for smaller models and misconfiguration can harm performance.
HyDE: Find Documents by Embedding a Fake Answer
Instead of embedding a short query, HyDE uses an LLM to generate a full, hypothetical answer document. This vector, representing an ideal answer, is then used to find similar real documents, improving zero-shot retrieval. The generated document is fictional.

Target Encoding: Replacing Categories with Target Stats
Target encoding replaces a category (e.g., "USA") with a statistic from your target variable (e.g., average sales). It's ideal for high-cardinality features where one-hot encoding is impractical. The footgun is data leakage, which causes severe overfitting.

Graph RAG: Answering Questions with Connected Facts
Graph RAG answers complex questions by exploring a map of connected facts (a knowledge graph) instead of just searching flat text. Use it for queries needing synthesis, like finding drugs for a disease made by companies in a specific country.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles