Easy concepts in AI & ML, page 7
N-way-K-shot: Classifying with Few Examples
N-way-K-shot is a framework for testing a model's ability to learn from scarce data. It asks: 'Can you classify between N categories after seeing only K examples of each?'
High Dynamic Range (HDR): Seeing More Light
HDR captures a wider range of light and dark than standard images, preventing blown-out highlights and crushed shadows. It's used to show scenes as the human eye sees them. The footgun is thinking HDR is just 'brighter'—it's about more detail in the extremes.
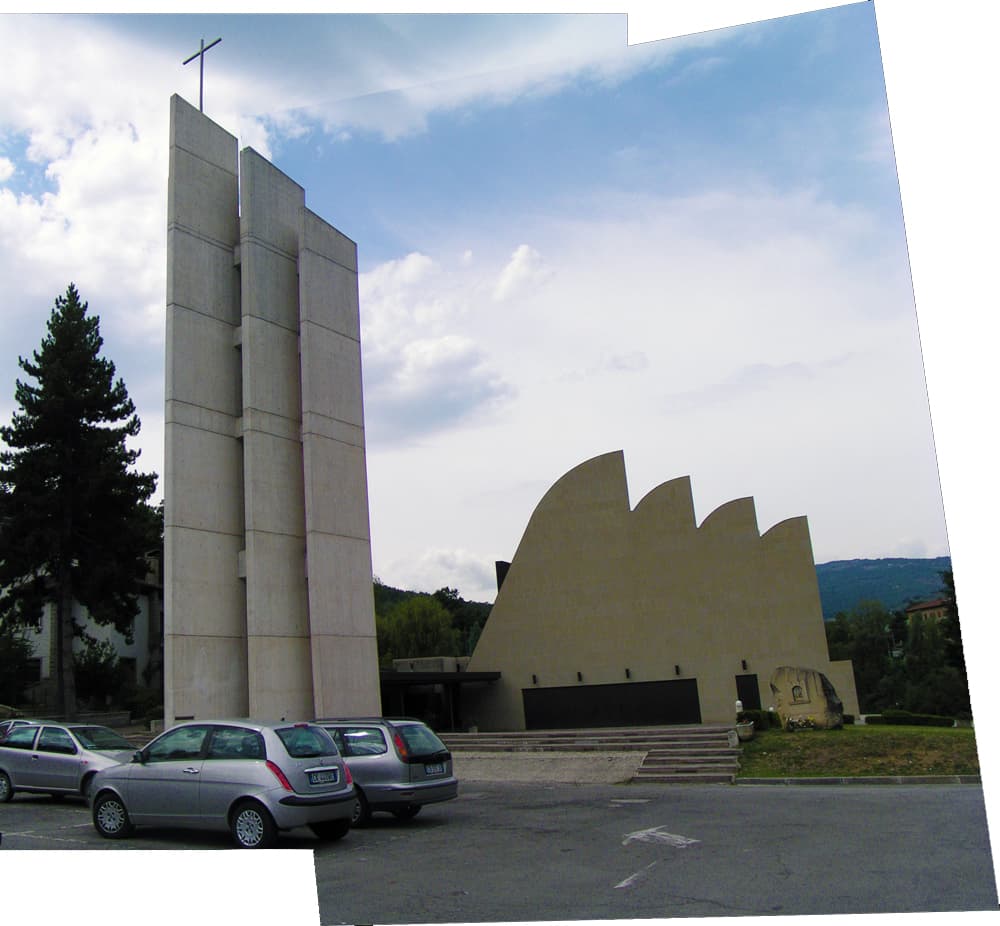
Image Stitching: Creating Panoramas from Overlapping Photos
Image stitching digitally 'tapes' together overlapping photos to create a single, wider panorama or a super-high-resolution image. It's used in phone panorama modes and for creating gigapixel photos. The main footgun is insufficient overlap between shots.
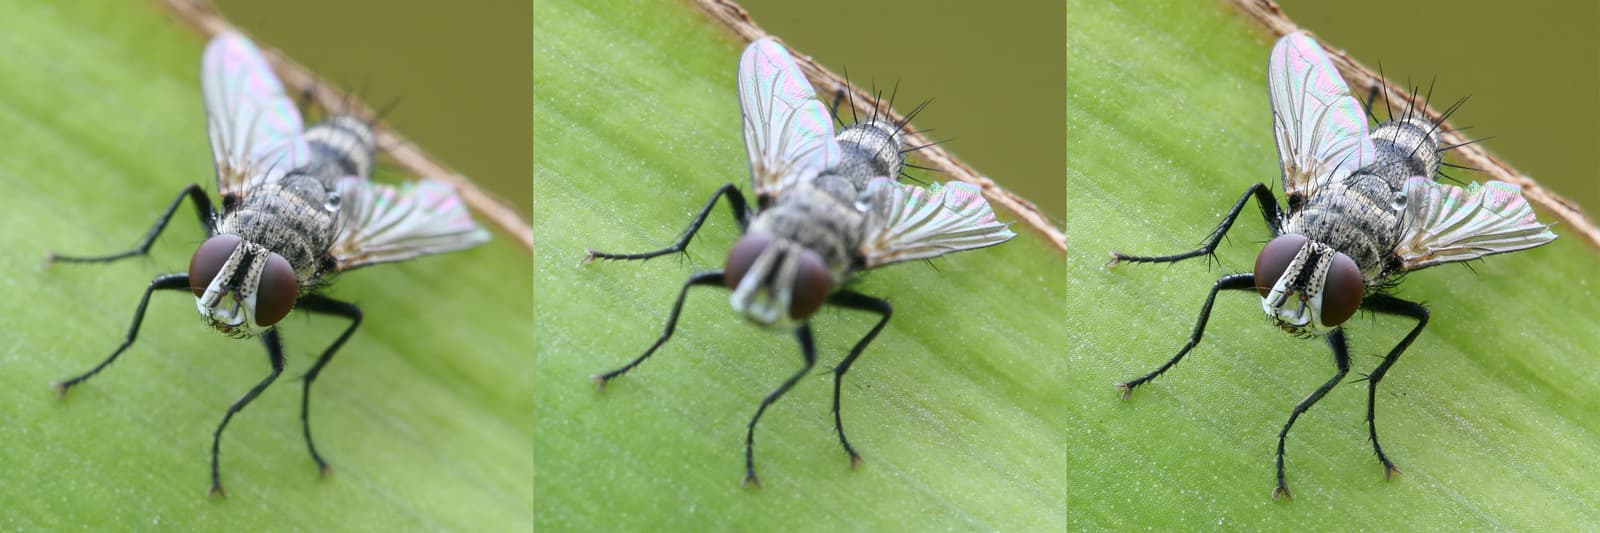
Focus Stacking: Combining Focal Planes for Ultimate Sharpness
Focus stacking creates an image with impossible depth of field by combining the sharpest parts of multiple photos. It's essential for macro, landscape, and microscopy where one shot can't keep everything sharp.
Image Sensors: Converting Light to Data
An image sensor is the digital equivalent of film, turning light into electrical signals. It's the core component in everything from your phone's camera to medical imaging.
ImageNet: The Dataset That Launched the Deep Learning Boom
ImageNet is a massive, human-labeled image library that became the standard benchmark for teaching computers to "see". It's the dataset behind the deep learning revolution, used to pre-train models for photo search and more.
Data Labeling: Teaching Computers How to See
Data labeling is like creating flashcards for an AI. You show it an image and explicitly tell it what's important, like 'this is a cat.' It's essential for training models for self-driving cars or medical imaging.
Confusion Matrix: Grading Your Model's Predictions
A confusion matrix is a scorecard showing how a classification model gets confused. It grids predicted labels against actual labels to reveal specific error types. It's essential for diagnosing failures that overall accuracy metrics might hide.
Softmax Function: Turning Scores into Probabilities
The softmax function turns a list of raw scores from a model into a clean probability distribution where all values sum to 1. It's most often the final step in a neural network for multi-class classification, like deciding if an image is a 'cat', 'dog', or 'bird'. The main footgun is mistaking a high softmax probability for high model confidence; it only reflects the score's strength relative to the other scores, not its absolute certainty.
Prompt Engineering: How to Talk to AIs
Think of prompt engineering as giving a smart but literal intern a precise set of instructions. It's the skill of structuring your text input to guide a generative AI toward a specific, desired output, moving beyond simple keywords. This is essential for getting reliable results, from formatted JSON to correctly styled text. The biggest mistake is treating the AI like a search engine instead of a collaborator that needs clear direction.
Prompt Engineering: Steering AI with Words
Prompt engineering is steering an AI with carefully chosen words instead of code. You use it to get reliable results from chatbots like ChatGPT or to build applications that use large language models (LLMs). The biggest mistake is treating the AI like a search engine; effective prompts provide context, examples, and constraints to guide the model, rather than just asking a simple question.

AI Hallucination: Confabulation, Not Perception
An AI hallucination is a confident answer that contains false or misleading information. It can happen when a model lacks reliable evidence, contradicts supplied context, or is asked for a very specific fact. Example: a chatbot invents a citation that sounds real. Check important claims against an authoritative source.
Cosine Similarity: Measuring Direction, Not Distance
Cosine similarity measures the angle between two vectors, not their distance, to gauge similarity. It asks, "Do these point in the same direction?" This is fundamental in AI for comparing text embeddings, where a vector's direction represents its meaning. The main footgun is confusing it with Euclidean distance; cosine similarity ignores vector magnitude, so two vectors can be far apart in space but still be considered nearly identical if their orientation is the same.

Word Embeddings: Turning Words into Vectors
Word embeddings turn words into numerical vectors, like coordinates on a map of meaning. Words with similar meanings, like "king" and "queen," are placed close together in this vector space. This is fundamental for text analysis in machine learning, allowing models to grasp semantic relationships instead of just matching text. The footgun is assuming the vector's individual numbers are human-interpretable; they are abstract features learned from data.
Byte Pair Encoding: Compressing Text for LLMs
Think of Byte Pair Encoding (BPE) as creating custom abbreviations for common letter pairs to compress text. It repeatedly finds the most frequent pair, like 'th', and merges it into a new token. LLMs use this to build vocabularies of common sub-word units, helping them understand rare words. The main footgun is that the final vocabulary size is fixed; choosing the wrong size can hurt model performance and efficiency.
Large Language Models (LLMs)
A large language model is a sophisticated pattern-matching engine trained on a massive library of text. They power modern chatbots and can generate, summarize, or translate text by predicting the most probable next word based on the patterns they've learned. The key footgun is that their output reflects the biases and inaccuracies of their training data, making them confident but potentially unreliable.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles