Intermediate concepts in AI & ML, page 5
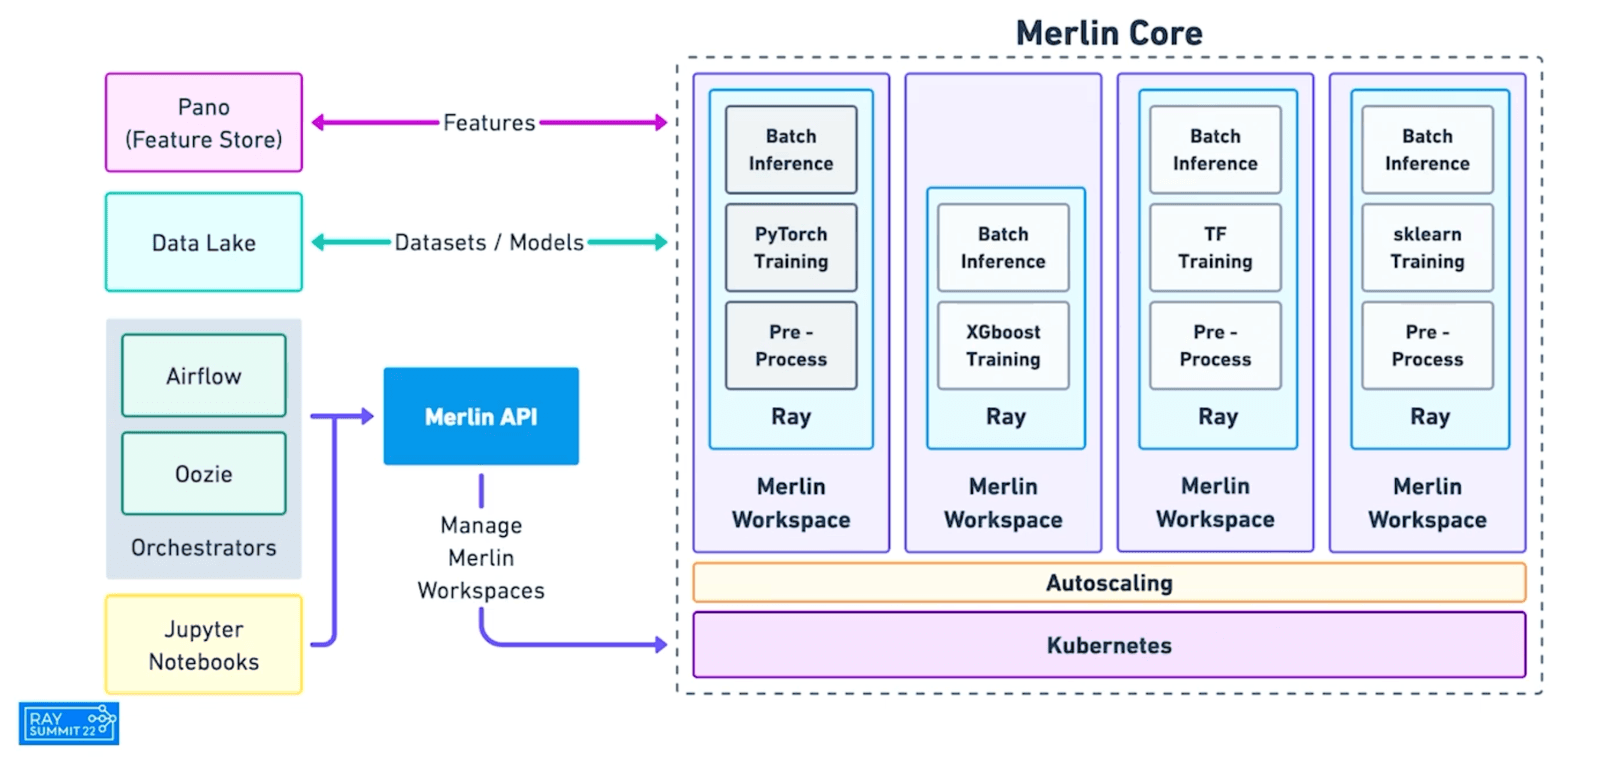
Ray AI Runtime (AIR): A Unified ML Toolkit
Ray AIR is a unified toolbox for the ML lifecycle, bundling libraries for data, training, tuning, and serving. It's for scaling end-to-end ML workflows on one distributed platform.
Kubeflow: MLOps on Kubernetes
Kubeflow brings the declarative, container-based world of Kubernetes to the entire ML lifecycle. It provides tools for building portable and scalable ML workflows, from development to production serving.
Dense Passage Retrieval (DPR): Semantic Search for QA
DPR finds answers by meaning, not just keywords. It converts questions and documents into vectors and finds the closest matches, forming the core of Retrieval-Augmented Generation (RAG).
Binning: Grouping Continuous Data into Buckets
Binning is like rounding, but for ranges. It groups continuous data into discrete 'buckets' to reduce noise. This turns messy user ages (21, 22.5) into clean categories (20-29) for analysis. The footgun: poor bin sizes can hide or create false trends.

ReLU: The 'On/Off' Switch for Neural Networks
ReLU acts as a simple on/off switch for neurons: positive inputs pass through, negative ones become zero. It's the default activation in deep learning, especially for vision tasks, as it's fast and helps gradients flow. The footgun: neurons can "die".
Slurm: The Job Scheduler for Supercomputers
Slurm is the reservation system for a shared supercomputer, queuing up jobs and assigning them to available nodes. It's the backbone of high-performance computing clusters in science and ML.

Hybrid Search: Combining Keyword and Vector Search
Hybrid search combines keyword precision with vector search's conceptual understanding in one query. It excels at retrieving relevant documents for RAG by finding both exact matches (like names) and similar ideas.
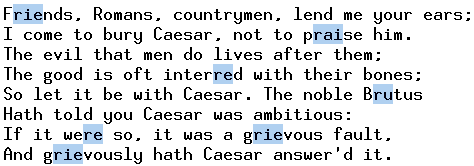
Regular Expressions for Data Cleaning
Regex is a mini-language for describing text patterns, letting you find and fix messy data at scale. It's used to standardize phone numbers or extract zip codes from addresses. The footgun: complex regex is often unreadable and a maintenance nightmare.
Elastic Training: Training Models on Unreliable Hardware
Elastic Training lets ML training jobs survive worker nodes being added or removed mid-run. It's like a construction crew that adapts to a changing number of workers, making it ideal for training large models on cheap but unreliable cloud spot instances.
Context Stuffing: Giving LLMs Short-Term Memory
Context stuffing adds external documents to an LLM's prompt, giving it temporary, task-specific knowledge. Use it for one-off questions on specific docs, but beware: it fails when documents exceed the model's context window limit, causing truncated data.

Label Encoding: Turning Categories into Numbers
Label Encoding turns text categories into numbers, like assigning bib numbers to runners. It's essential for algorithms that need numerical input, but its biggest footgun is creating a fake order (e.g., 2 > 1) that can mislead linear models and neural…
Cross-Entropy Loss: How Wrong Is Your Model's Guess?
Cross-entropy loss measures the penalty when a model's predicted probabilities diverge from the true labels. It's the standard loss for classification tasks, like telling a cat from a dog.
LLMs Get 'Lost in the Middle' of Long Contexts
LLMs struggle to find information buried in the middle of long prompts. Performance is highest when key facts are at the beginning or end of the context. This impacts multi-document QA and RAG.
Backpropagation: How Neural Networks Learn from Mistakes
Backpropagation is how a network learns from its mistakes. It works backward from the output error, calculating how much each weight contributed and adjusting it. This is the core training loop for most deep learning models.
Data Augmentation: Getting More Images for Free
Data augmentation creates "fake" training data by modifying existing images—flipping, rotating, or color-shifting them. This fights overfitting when your dataset is small, forcing the model to generalize.
Dropout: Forcing a Network to Generalize
Dropout prevents overfitting by randomly zeroing out a fraction of neurons during training. This forces the network to learn more robust features instead of relying on specific neurons. It's a standard regularizer for large, dense layers.

AlexNet: The CNN That Sparked the Deep Learning Boom
AlexNet is the blueprint that proved deep CNNs could master image recognition, kicking off the modern AI boom. Its architecture is foundational for modern computer vision. The footgun is thinking it was just bigger; its novelty was combining new techniques.
Task Decomposition: Teaching LLMs to Plan
Task decomposition for an LLM agent is like writing a recipe: break a big goal into a checklist of small, executable steps. It's vital for complex requests like planning a trip, but a bad initial plan can cause cascading failures that doom the entire process.
Data Quality Management: Is Your Data Fit for Use?
Data quality management ensures data is "fit for purpose." It's vital when training ML models or creating financial reports, as outcomes depend on data reliability. The footgun is treating quality as a one-time project, not a continuous process.

Shadow Deployment: Test Models on Real Traffic
Shadow deployment runs a new model on real traffic without serving its predictions, letting you catch data drift before users are affected. It is the safest production validation method, but teams often forget to monitor its latency and resource costs.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles