Intermediate everything in AI & ML, page 18
Idempotent Data Pipelines: Reruns Without Side Effects
An idempotent pipeline gives the same output for the same input, no matter how many times you run it. This lets you safely retry failed jobs without side effects, which is crucial for scheduled batch inference or feature engineering tasks.
Data Storage Tiering: Pay Only for the Access You Need
Treat data like items in a house: hot, frequently used data on the counter; cool, less-used data in the pantry. Cloud providers use this to price storage, letting you move old logs to cheaper tiers.

Stop Paying for Idle Cloud Resources
Stop paying for idle cloud servers. Automated shutdown is like turning off the lights in an empty office, running compute only when needed. It's ideal for dev environments or scheduled batch jobs. The footgun is applying this to stateful production services.
GPU Utilization: Are You Wasting Your Most Expensive Resource?
GPU utilization isn't just a percentage; it's a measure of your return on investment. It tells you if your expensive hardware is computing or just waiting for data. Use it to diagnose slow training jobs and right-size cloud instances for ML workloads.
Unit Economics: Tying ML Costs to Business Value
Unit economics connect your ML spending to business outcomes. Instead of a total cloud bill, you see cost per prediction or per token. This helps product owners make pricing tradeoffs and engineers spot efficiency gains.
Showback vs. Chargeback: Who Pays for Compute?
Showback tells teams what their resource usage costs; Chargeback makes them pay for it. It's the difference between a receipt and a bill. These models help manage cloud costs, but implementing chargeback without granular tracking leads to disputes.
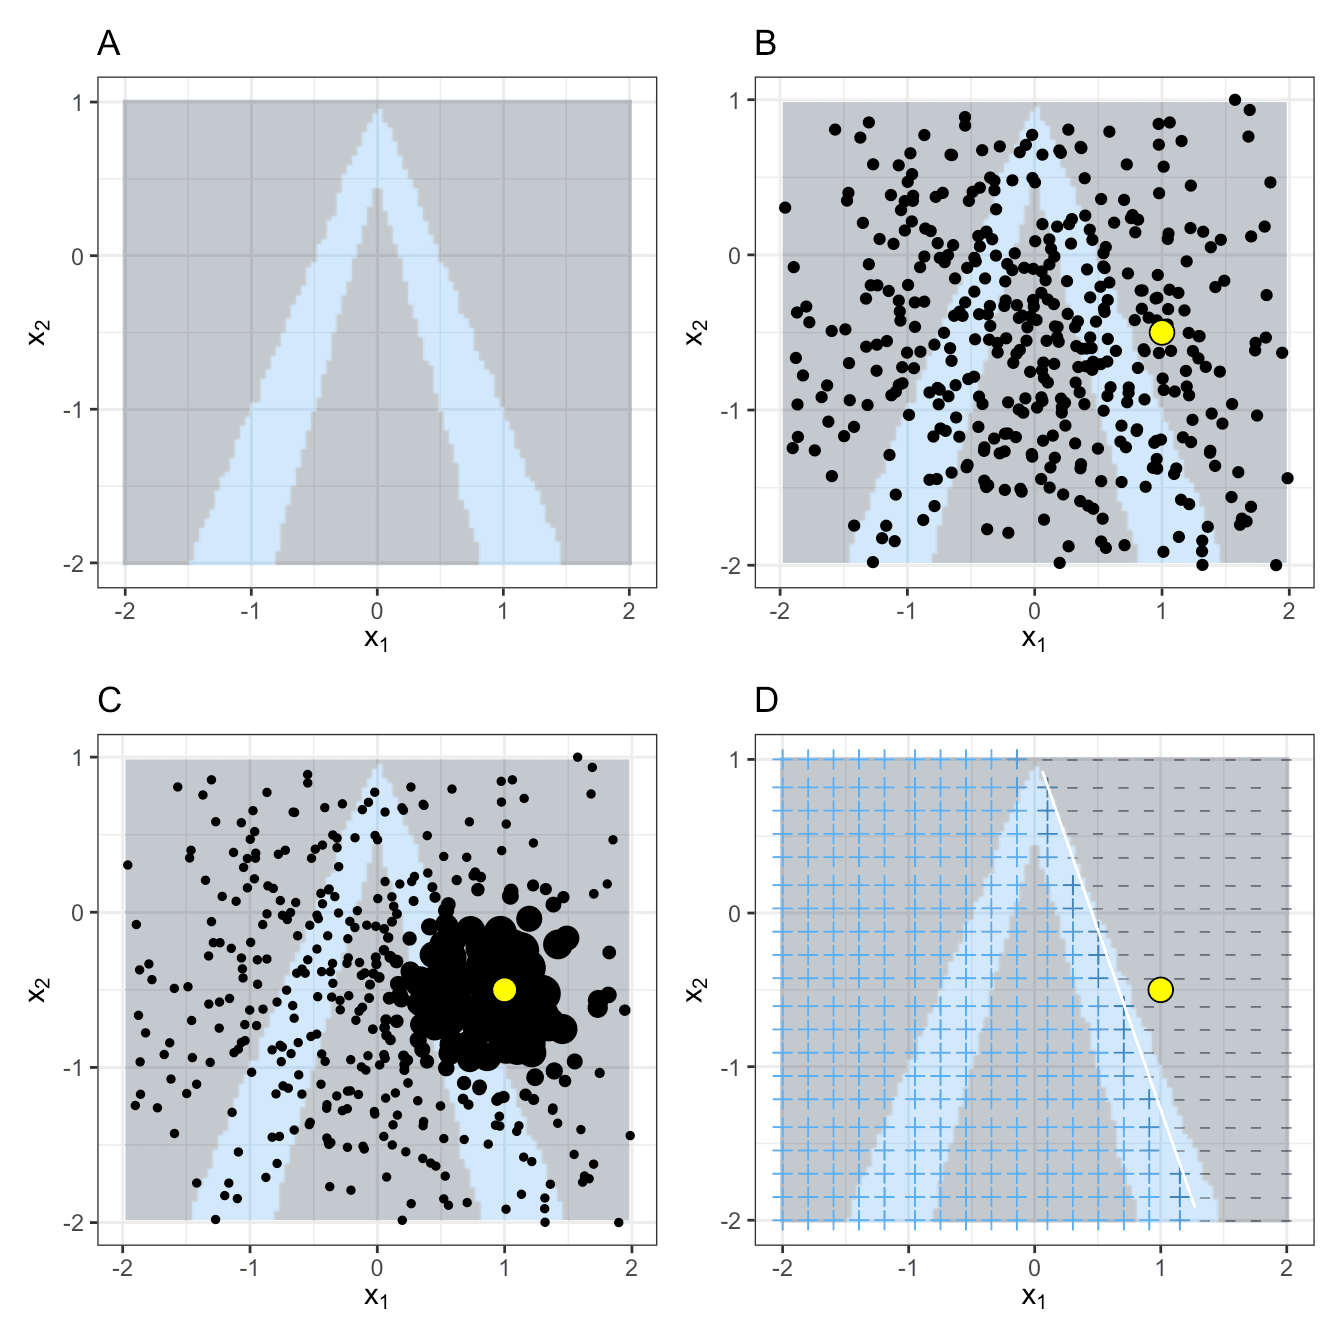
LIME: Explaining Single Predictions from Any ML Model
LIME explains a single prediction from any 'black box' model by approximating it with a simpler model that's only accurate locally. Use it to see why a specific user churned.
SHAP: Explaining Black Box Model Predictions
SHAP explains a model's prediction by treating features as players in a game and fairly distributing credit for the outcome. Use it to understand why a specific loan was denied or an image was misclassified. The footgun: SHAP explains the model, not reality.
ML Threat Modeling: Assume Your Data Is Compromised
Threat modeling for ML means assuming your training data is already compromised. This is crucial for services using public or user-supplied datasets. The main footgun is trusting data sources, as data poisoning can silently corrupt your model's behavior.
The MLOps Maturity Model: A Roadmap for Growth
The MLOps Maturity Model is a roadmap from manual chaos to automated ML systems. Use it to assess your team's current state and plan incremental improvements.

Pipeline Step Caching: Don't Recompute What You Don't Have To
Pipeline step caching is memoization for your ML infrastructure, saving time and money by reusing previous results. It's used in MLOps pipelines when inputs and code haven't changed. The footgun: the cache is scoped to one pipeline and a timeout, not globally.
Argo Workflows: Run Complex Jobs on Kubernetes
Think of Argo Workflows as a script runner for Kubernetes, where each command is a container. It runs multi-step jobs like CI/CD or ML pipelines. The footgun is treating it like a full CI server; it's just an engine and lacks features like Git polling.
Vertex AI Pipelines: Orchestrating ML Workflows
Think of it as an assembly line for your machine learning models, automating everything from data prep to deployment. Use it to build reproducible, production-grade ML systems on Google Cloud.
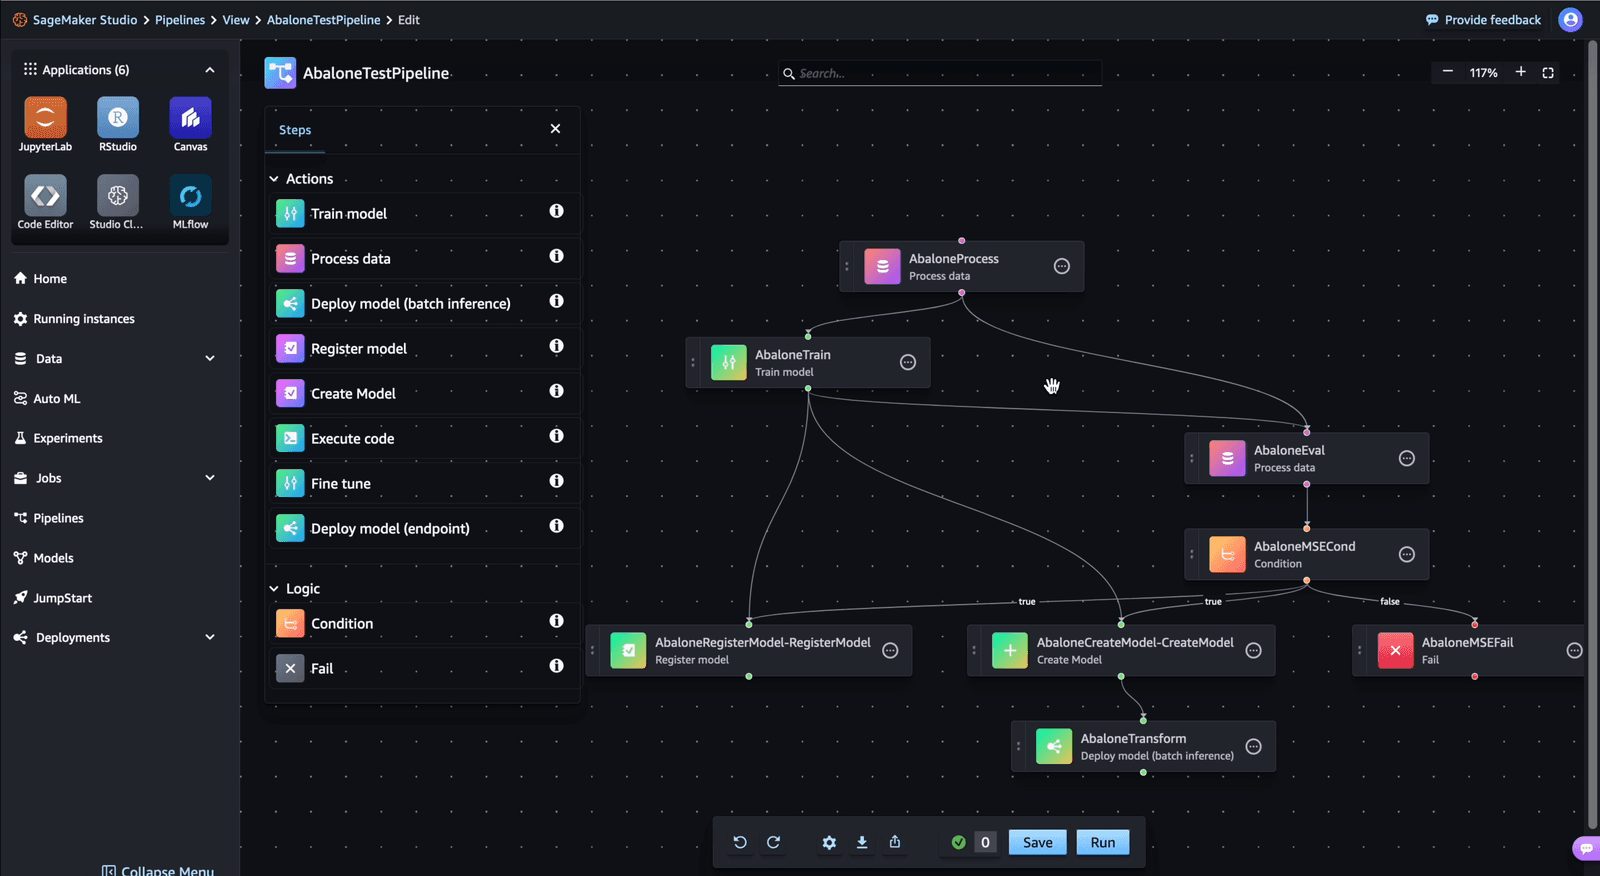
Amazon SageMaker Pipelines: Repeatable ML Workflows
Think of SageMaker Pipelines as a CI/CD pipeline for ML models, automating workflows from data prep to deployment. Use it for reproducible training and automated retraining.
TensorFlow Extended (TFX): Production ML Pipelines
TFX is an end-to-end platform for building production ML pipelines, like an assembly line for your models. It automates data validation, training, analysis, and serving. The footgun: TFX is not one tool, but a suite of libraries you must learn and connect.
Population Stability Index (PSI): Quantifying Data Drift
The Population Stability Index (PSI) gives you a single number to quantify data drift between training and live data. It's used in MLOps to monitor model health, especially in finance. The footgun is ignoring a high PSI, which signals silent prediction decay.
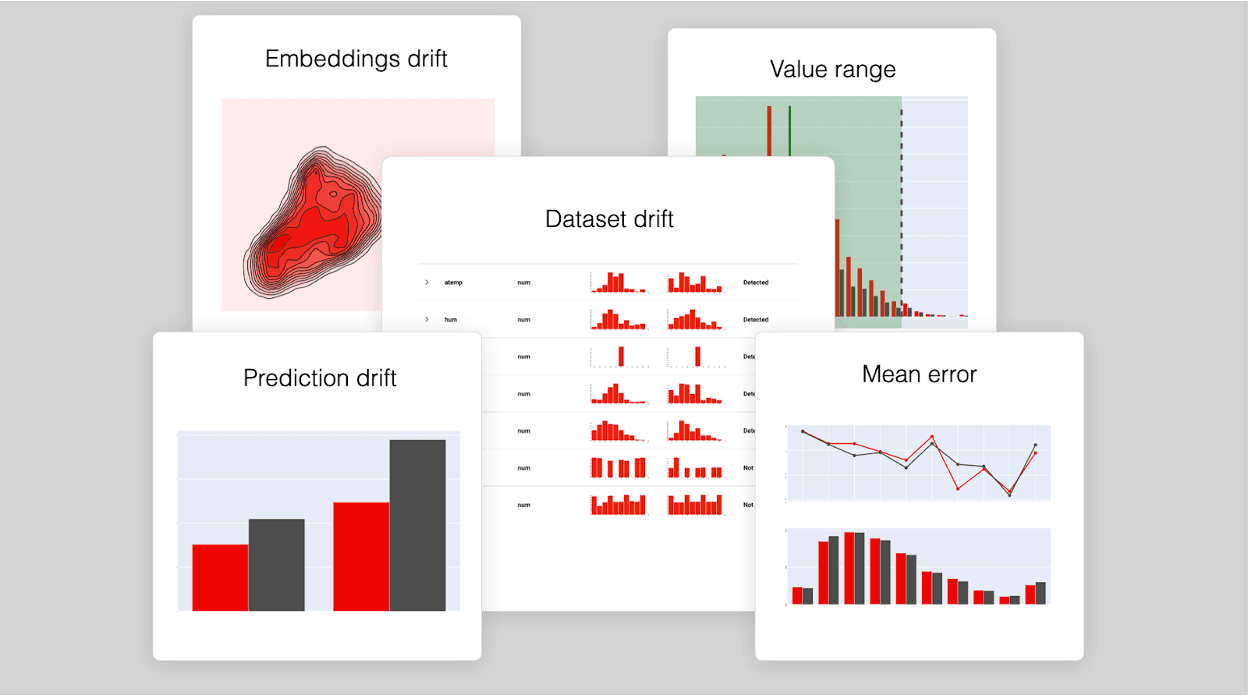
ML Monitoring Dashboards: Your Model's Health Chart
An ML monitoring dashboard is a health chart for your production model, showing how its performance decays. It tracks silent failures like data drift or concept drift, where user behavior changes and makes your model obsolete.
BentoML: Packaging Models for Production APIs
BentoML is a standardized shipping container for your ML models, packaging them into production-ready API endpoints. Use it to deploy LLMs or RAG systems without managing complex infrastructure. Its focus is purely on inference, not model training.
Autoscaling ML Inference Endpoints
Autoscaling matches your ML model's compute to real-time demand, like an elastic container for your inference service. It handles spiky traffic for online endpoints, scaling up for peaks and down to save costs.

Inference Batching: Grouping Requests for Throughput
Think of inference batching as a carpool for your ML model. Instead of sending each request in its own car, you wait a few microseconds to fill a bus, dramatically improving GPU efficiency.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles