Everything in AI & ML, page 21
How would you implement versioning for feature definitions in a feature store?
Tests separation of metadata schema versions from data snapshots for reproducible training. Strong answers cover: immutable schema versions on breaking changes, safe appends without backfill, and time-travel data reads.
Backfill a complex feature for millions of users without impacting production
Reuse the live pipeline on historical partitions, run bounded batches on separate compute, stage results, and validate before promotion.
Design a system to detect training-serving skew for a numerical feature
Tests ML monitoring design via statistical distribution comparison between training and live data. Strong answers cover PSI/KS tests, windowed thresholding, and tiered alerting. Red flag: comparing raw values instead of distributions or ignoring alert fatigue.
Online vs offline feature store architecture and use cases
This tests latency trade-offs between real-time and batch infrastructure. Contrast fast online lookups against batch offline stores; fraud detection maps to online and model training to offline. Red flag: treating them as interchangeable and ignoring latency.
What problems does a Feature Store solve in ML systems?
Tests understanding of feature store value beyond storage. Great answers cover: feature reuse across teams, managed transformation pipelines, and online/offline consistency to prevent training-serving skew. Red flag: calling it simply a database or cache.
How to establish data lineage and reproducibility for hundreds of ML models
This tests MLOps traceability architecture. A strong answer proposes a unified metadata graph linking raw data, feature transforms, dataset versions, training runs, and deployed models via automated hooks.
Design a sub-50ms real-time bidding feature pipeline
Tests merging batch historical and streaming data under sub-50ms latency. Strong answers use dual paths: batch backfills a KV store, streaming writes to an in-memory cache, serving merges both at request time. Red flag: one database without hot-cold split.
How would you design automatic data drift detection for production inference?
This tests reference-vs-live monitoring architecture. A strong answer chunks data, runs univariate per-feature drift, adds multivariate PCA or domain classifiers, and ranks threshold alerts. A red flag is checking aggregate metrics instead of feature shifts.
How would you scale 1TB Pandas feature computation across machines?
This tests memory limits and distributed migration. A strong answer contrasts single-machine tactics, column pruning and efficient dtypes, with distributed frameworks like Dask or Spark, noting shuffle costs and API parity.
Describe feature store architecture and training-serving skew
This tests FTI pipeline glue and dual-store skew elimination. A strong answer lists offline and online stores, shared transformation logic for consistent compute, and point-in-time correctness. A red flag is calling it merely a database or cache.
What data validation strategy prevents new categories from breaking your encoder?
Lock categorical domains in a schema, reject unseen categories before encoding, and use an OOV bucket as fallback.

ETL vs ELT: when to prefer each for ML?
Tests architecture tradeoffs. Contrast ETL's pre-load transformation with ELT's in-warehouse transformation, map structured legacy to ETL and raw lakes to ELT, and cite ML iteration needs. Red flag: calling one better ignoring compute placement or volume.

Design ingestion for clickstream and batch product metadata
Use a data lake for raw data, a feature store for joins, columnar formats for batch, and row formats for events.

How do you guarantee identical feature engineering for training and real-time inference?
Tests unifying feature engineering across batch and online paths to eliminate skew. Answer: shared transformation libraries, versioned feature stores, and logged feature validation. Red flag: separate training and serving code without a single source of truth.
Design a robust automated testing strategy for ML models before production
Statistical offline thresholds, shadow-canary launches, input drift detection, and rollbacks tied to KPIs.
Design an MLOps platform for a mid-sized company: components and build-vs-buy trade-offs
Tests pragmatic scoping and build-vs-buy reasoning. Strong answers rank data estate, feature store, registry, CI/CD/CT, and monitoring above exotic serving, buying commodity and building differentiators. Red flag: custom orchestrators or missing governance.
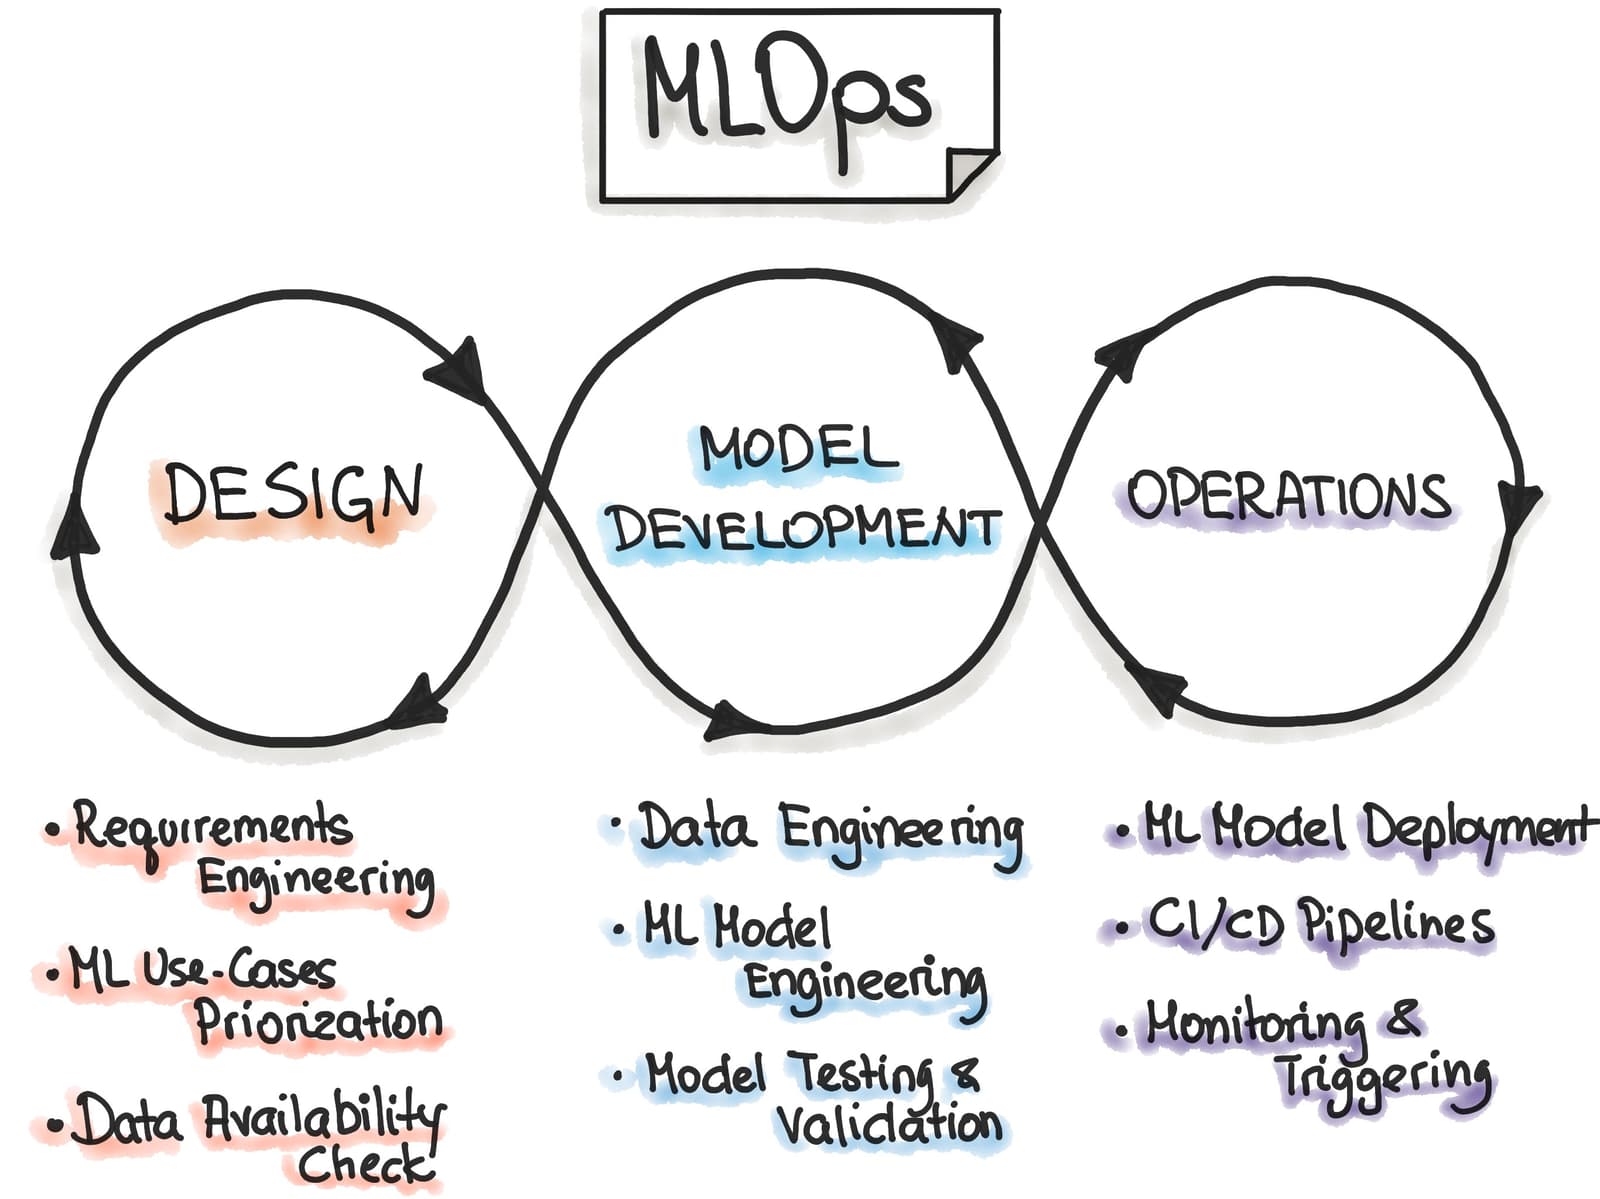
What production metrics and auto-thresholds trigger model retraining?
This tests production monitoring maturity. A strong answer covers technical drift metrics, business KPIs tied to model decisions, and automated thresholds that page or trigger CI/CD retraining.
Explain ML pipelines and typical CI/CD/CT components
Tests if you separate code CI/CD from model CT and grasp ML automation. Cover source control, build, tests, deploy for code; data validation, training, evaluation, promotion for CT. Red flag: treating ML like software CI/CD and ignoring data or registry gates.
Why version code, data, and models in MLOps?
Tests immutable lineage across code, data, and models. Strong answers cover content-addressed data, git commits, a model registry linking both, and CI triggers on any change. Red flag: saying git alone handles data and models.
What are the primary differences between traditional DevOps and MLOps?
Tests if you know MLOps extends CI/CD to data and probabilistic assets. Contrast code artifacts with models and datasets. Distinguish commit triggers from drift or retraining triggers. Red flag: treating models as static binaries and ignoring data lineage.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles