Everything in AI & ML, page 19

Design a system to monitor a real-time prediction service for feature drift
Async feature logging, distribution comparison via PSI/KS against training baseline, and threshold-based anomaly alerts.
Differences between monitoring a traditional REST API and a production ML model
Contrast latency/errors with ML signals like data drift and training-serving skew against baselines, noting ground truth delays.
Design a multi-model serving architecture for infrequently used models
Tests sparse-traffic cost efficiency via shared compute and dynamic loading. Strong answers: LRU cache on fast storage, scale-to-zero with async preload, pinned hot models, per-model quotas.

Design cost-effective inference for spiky traffic without idle GPUs
Tests designing inference that cuts idle GPU cost during troughs yet handles spiky peaks with low latency via SageMaker blue/green fleets, production variants, and CloudWatch baking periods. Red flag: always-on GPU pools with naive auto-scaling.
How would you design an A/B test for two live ML models?
Tests production experimentation rigor beyond random splitting. Strong answers cover: consistent user hashing for sticky assignment, isolated feature stores, guardrail metrics, and pre-calculated statistical power.
Explain model quantization, its benefits, drawbacks, and validation approach
Tests precision trade-offs in production. Answer: define lowering weights from fp32 to int8/int4; cite memory and latency gains versus accuracy loss; validate with downstream benchmarks and shadow A/B. Red flag: treating as lossless or skipping task metrics.
How would you systematically diagnose high latency in an online inference service?
Check p90/p99 and TTFT to split queuing from compute; inspect queue depth, batch size, GPU, and benchmarks; check cache.
Deploy a trained model as a containerized REST API
This tests practical MLOps fluency. A strong answer covers loading the artifact, wrapping it in a web server, building a Dockerfile, and exposing health and predict endpoints. Red flag: conflating training with serving or omitting resource limits.

Describe the difference between online and batch inference.
Online uses autoscaling APIs for millisecond-to-second latency; batch uses scheduled compute for minute-to-hour latency.

Architectural challenges for deploying ML models on resource-constrained edge devices
Tests Edge MLOps architecture under severe constraints. Strong answers hit quantization and delta OTA updates for flaky networks, power-aware scheduling, and closed-loop drift detection.
How would you systematically debug an inference API latency breach?
This tests structured debugging across the full inference stack. A strong answer traces the request path from ingress to GPU, splits TTFT from token-generation latency, inspects queuing and batching, then applies targeted fixes.

Design a system for batch scoring millions of customer records daily
Shard jobs via scheduler; partition storage; right-size CPU/GPU on spot; retry.

Where to place feature transformations: client, serving API, or upstream service?
Tests separation of concerns in ML systems. Client causes duplication and skew; serving API couples compute to requests; dedicated service adds a network hop but centralizes logic. Red flag: ignoring training-serving skew.
Describe the difference between online and batch inference.
Online serves single requests in ms on live endpoints; batch processes data offline with elastic compute.

How would you design safe, automatic schema evolution in CI?
Tests whether you separate schema evolution from semantic validation. Strong answer: versioned data contracts allowing additive enums, unknown-category model buckets, and automated contract negotiation. Red flag: manual allow-lists or disabling validation.
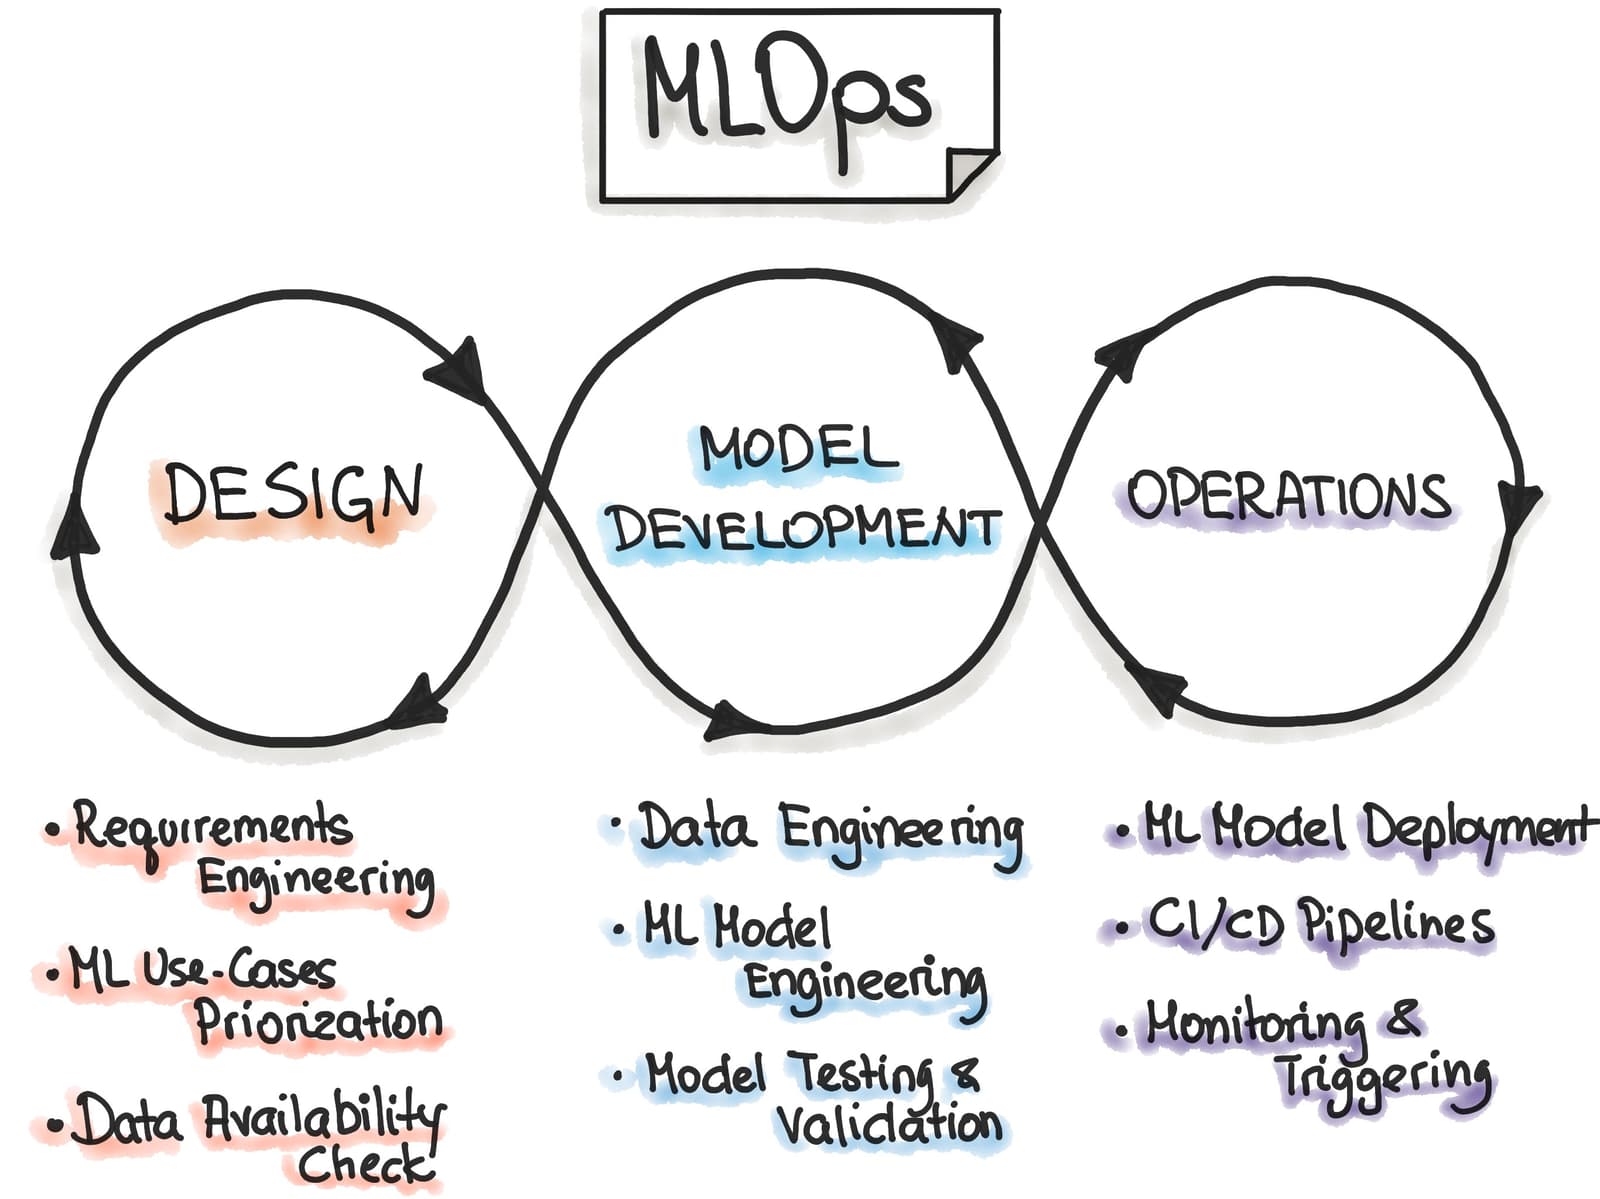
What infrastructure is needed for a Continuous Training pipeline?
Tests event-driven ML system design beyond CI/CD. Strong answers name orchestrators, feature stores, model registries, and validation gates, mapping triggers to retraining and promotion. Red flag: conflating CT with CI/CD or skipping model validation.
How would you implement shadow deployment and which metrics justify promotion?
Tests zero-impact validation when feedback loops are broken. Mirror traffic to a shadow variant, log predictions, and compare latency, errors, and drift against SLAs. Red flag: calling it A/B testing or claiming live business metrics from unserved responses.
What events trigger automatic model retraining beyond code changes?
This tests whether you treat ML pipelines as event-driven systems, not just software CI/CD. A strong answer lists data drift, scheduled cron jobs, production metric degradation, schema changes, and upstream data pipeline completion.
What is a model registry's purpose in CI/CD4ML and its CI/CD interaction?
Tests if you see the model registry as the bridge between experiments and production, not just storage. A strong answer explains how CI publishes validated artifacts and CD consumes versioned models. Red flag: calling it a passive file dump without versioning.
What automated tests belong in CI before deploying a classification model?
Name data schema checks, performance regression vs baseline, bias audits, and artifact integrity.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles