Everything in AI & ML, page 17
Describe a Model Registry and how it differs from versioned storage
It tests governance and lifecycle metadata beyond file storage. A strong answer covers lineage, stage transitions, approval gates, and artifact metadata, contrasting with buckets that only store file versions.
Why systematically track ML experiments and what should you log?
This tests reproducibility mindset over bookkeeping. A strong answer names three motivations—reproducibility, selection, debugging—and three logs: hyperparameters, metrics, and code versions.
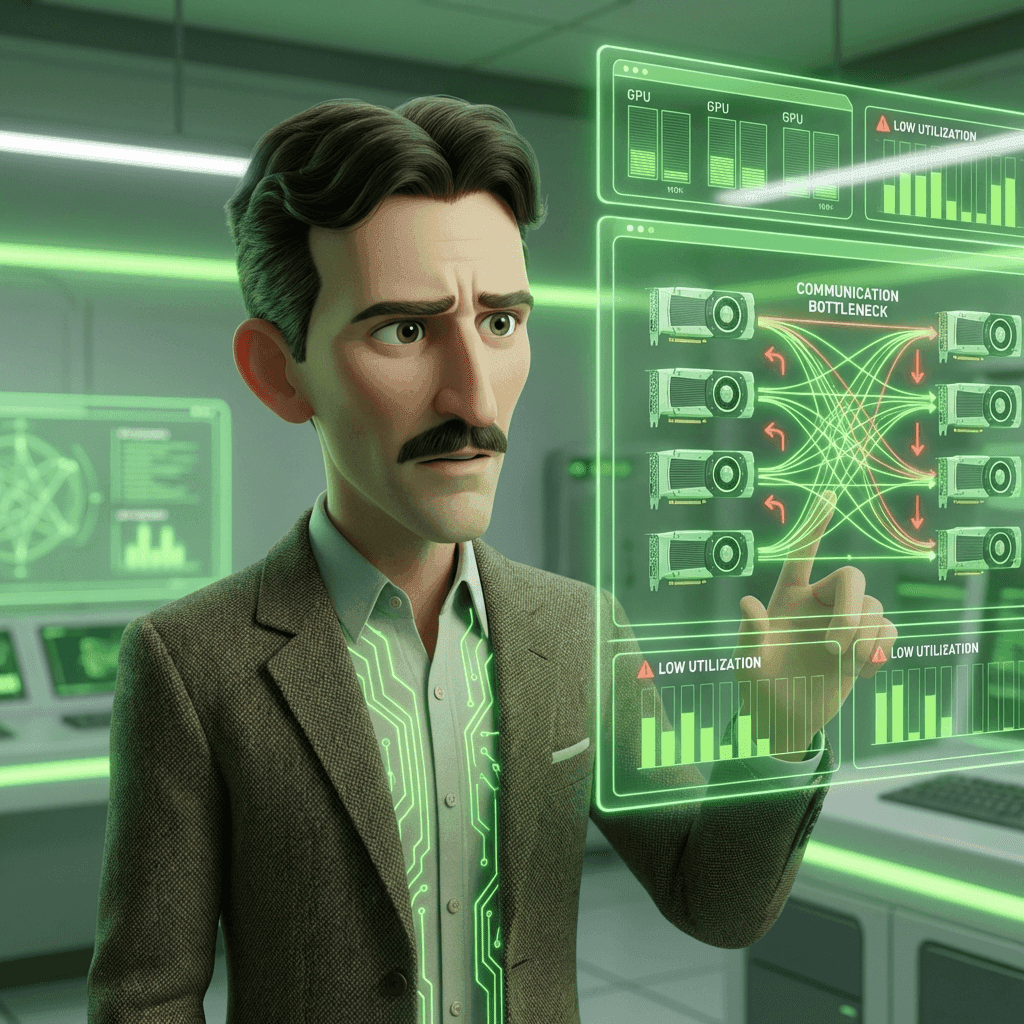
Low GPU utilization on multi-GPU instance: diagnose and right-size
Tests distributed bottleneck triage. Strong answers profile CPU/GPU/disk, compare gradient sync time to compute, validate per-GPU batch size, and check NVLink vs PCIe. Red flag: suggesting more GPUs before ruling out data starvation or all-reduce overhead.
Design an ML workflow that masks PII from scientists
This tests privacy-preserving pipeline design and least-privilege access for ML teams. Propose automated de-identification before experimentation, restrict re-identification to production jobs, and enforce role-based access with audit logs.

Compare and contrast Apache Airflow versus Kubeflow Pipelines for ML orchestration
This tests matching orchestrators to ML constraints. A strong answer contrasts Airflow's task scheduling and backfills with Kubeflow's K8s-native GPU scaling, choosing based on team skills.

Explain dynamic batching in inference servers and its trade-off
Dynamic batching launches when a time window or max size is met, improving throughput over static batching, but short ones wait for the slowest.

Design a multi-tenant GPU serving system for hundreds of fine-tuned models
Tests GPU memory tradeoffs versus cold-start latency in multi-tenant serving. Strong answers propose tiered CPU staging, predictive pre-warming, and disaggregated prefill and decode. Red flag: keeping all models GPU-resident or ignoring transfer overhead.

Compare Canary and Blue/Green ML deployments and model-specific metrics
Contrast Canary gradual shift vs Blue/Green instant swap; highlight silent failures, data drift, prediction distribution; cite accuracy and calibration.
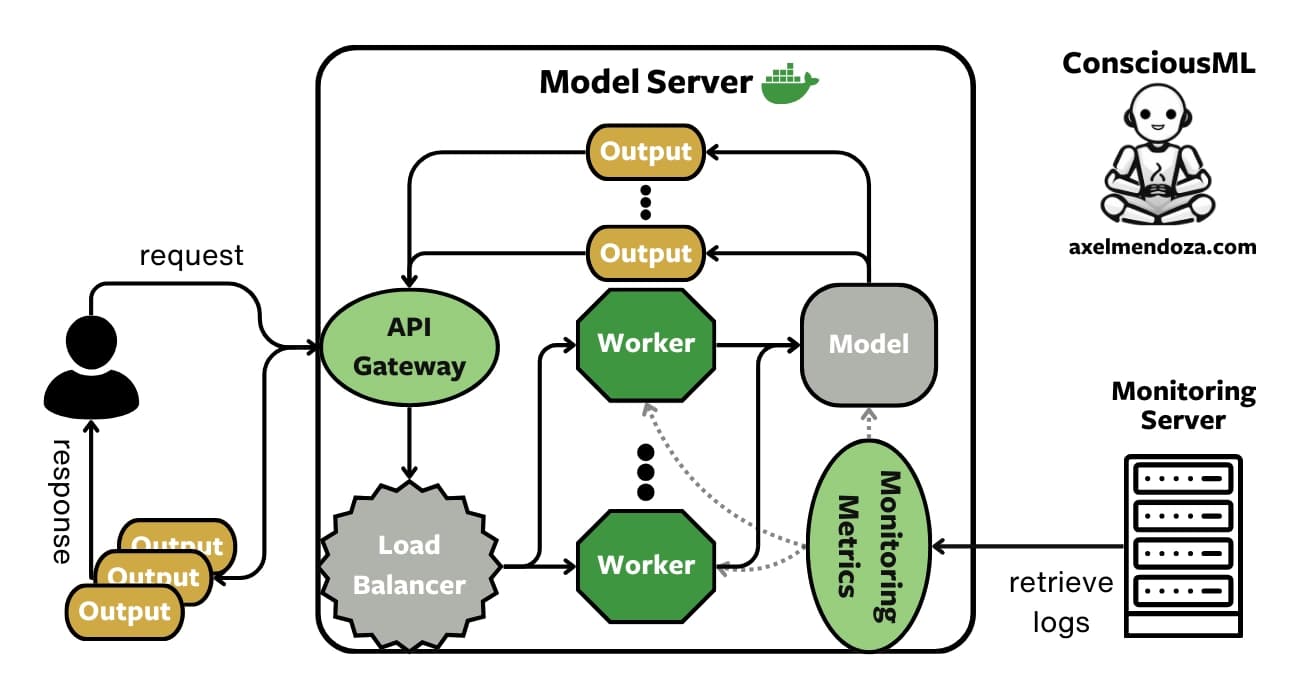
Expose a trained model as a simple web service
Practical MLOps knowledge from model serialization to serving. Package the model into a standard format, containerize it, expose a REST endpoint behind a load balancer, and add monitoring. A bare Flask server without containers or health checks is a red flag.
How would you version control a 50GB dataset in a CI/CD pipeline?
Contrast Git LFS (simple, but 50GB chokes CI clones) with DVC (git metadata plus S3; enables selective pulls and CI cache).
How would GDPR requirements influence experiment tracking and model management design?
Immutable data lineage, user exclusion lists, audit logs, versioned explainability.
How do you ensure ML experiment reproducibility beyond random seeds?
Tests system-level reproducibility through data versioning, environment capture, and pipeline automation. Strong answers cover versioned datasets, containerized dependencies, and immutable experiment logs.

Describe an ML workflow with massive egress fees and re-architecture to mitigate
Tests whether you recognize egress spikes when storage and compute cross cloud or region boundaries. Great answers sketch a multi-cloud training pipeline, cite per-GB rates, and propose caching or compute placement. Red flag: suggesting compression alone.
Design a showback or chargeback system for ML infrastructure costs
Tag workloads to cost centers; define shared-resource formulas; automate reconciliation; use showback.
Design a near real-time cost visibility system for ML teams
Tests cost attribution across shared ML infrastructure and streaming pipeline design. Strong answers combine billing exports with resource labels, sub-hour aggregation, and anomaly detection for training spikes.
How do you adapt ML training for spot instance interruptions?
Tests resilience under preemption. Strong answers cover frequent checkpoints to durable storage, SIGTERM handling, idempotent retries with budgets, and compute-state separation. Red flag: saving checkpoints only on local ephemeral disks or solely at epoch end.

Describe a basic lifecycle policy to manage cloud storage costs
This tests cost optimization via tiered storage and automated expiration. Strong answers list transitions from Standard to IA to Glacier, then deletion after set days, plus retrieval costs. A red flag is using manual scripts instead of native lifecycle rules.
Differences between on-demand, reserved, and spot EC2 instances?
Tests cost-reliability-commitment tradeoffs for ML infrastructure. Good answers map on-demand to experiments, reserved for production training, and spot to fault-tolerant batch jobs. Red flag: spot for real-time serving or skipping reserved capacity analysis.
How do you attribute cloud costs to ML projects and implement tagging?
Tests knowledge of resource tagging for cost attribution. A strong answer names provider-specific tags or labels, embeds them in infrastructure-as-code, and activates cost allocation reports.
Design a defense-in-depth strategy against adversarial evasion on a deployed image classifier
Proactive: adversarial training, preprocessing, ensembles.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles