Everything in AI & ML, page 18
Design a cryptographically verifiable ML audit trail from dataset to deployment
Tests cryptographic provenance and tamper-evident ML pipelines. Strong answers cover content-addressed datasets, signed training logs linking code and hyperparameters to model hashes, and deployment signature checks.

What is the wrong and right way to manage ML database secrets?
This tests secret management hygiene for ML pipelines. A strong answer rejects hardcoded secrets and env vars, then proposes AWS Secrets Manager with IAM retrieval, TLS, caching, and rotation. A red flag is suggesting .env files, ConfigMaps, or CLI arguments.
How would you programmatically monitor a deployed model for demographic bias?
Tests operationalizing fairness beyond static audits. Track group metrics like parity and equalized odds; slice by protected attributes; alert on drift; route violations to review. Red flag: treating fairness as a one-time check versus continuous monitoring.
Describe securing an automated ML pipeline and CI/CD integration points
Tests ML supply-chain depth versus bolt-on appsec. Strong answers stage checks across
Why was this customer denied: global or local explanation?
This tests matching questions to explanation scope. Global methods show overall behavior; local methods explain one prediction. Specific denials need local methods like SHAP. A red flag is using global summaries like permutation importance or PDPs for a case.
How do you give read-only access to a shared cloud storage bucket?
Bind an IAM role with read permissions to the team at the bucket level, avoid object-level ACLs, and mount read-only on training VMs.

Propose an architectural solution for contended GPU training resources
Tests multi-tenant GPU scheduling design at scale. Great answers tier jobs by checkpointability, apply quota-based preemption, mix spot and on-demand instances, and use MIG or time-slicing to bin-pack. Red flag: buying GPUs without scheduling logic.
Design a multi-tenant ML platform with isolation, security, and cost attribution
Tests mapping tenancy to compute, network, and identity primitives. Strong answers compare hard vs soft isolation, use namespaces or node pools with network policies and IAM, and enforce chargeback via resource quotas and labels.
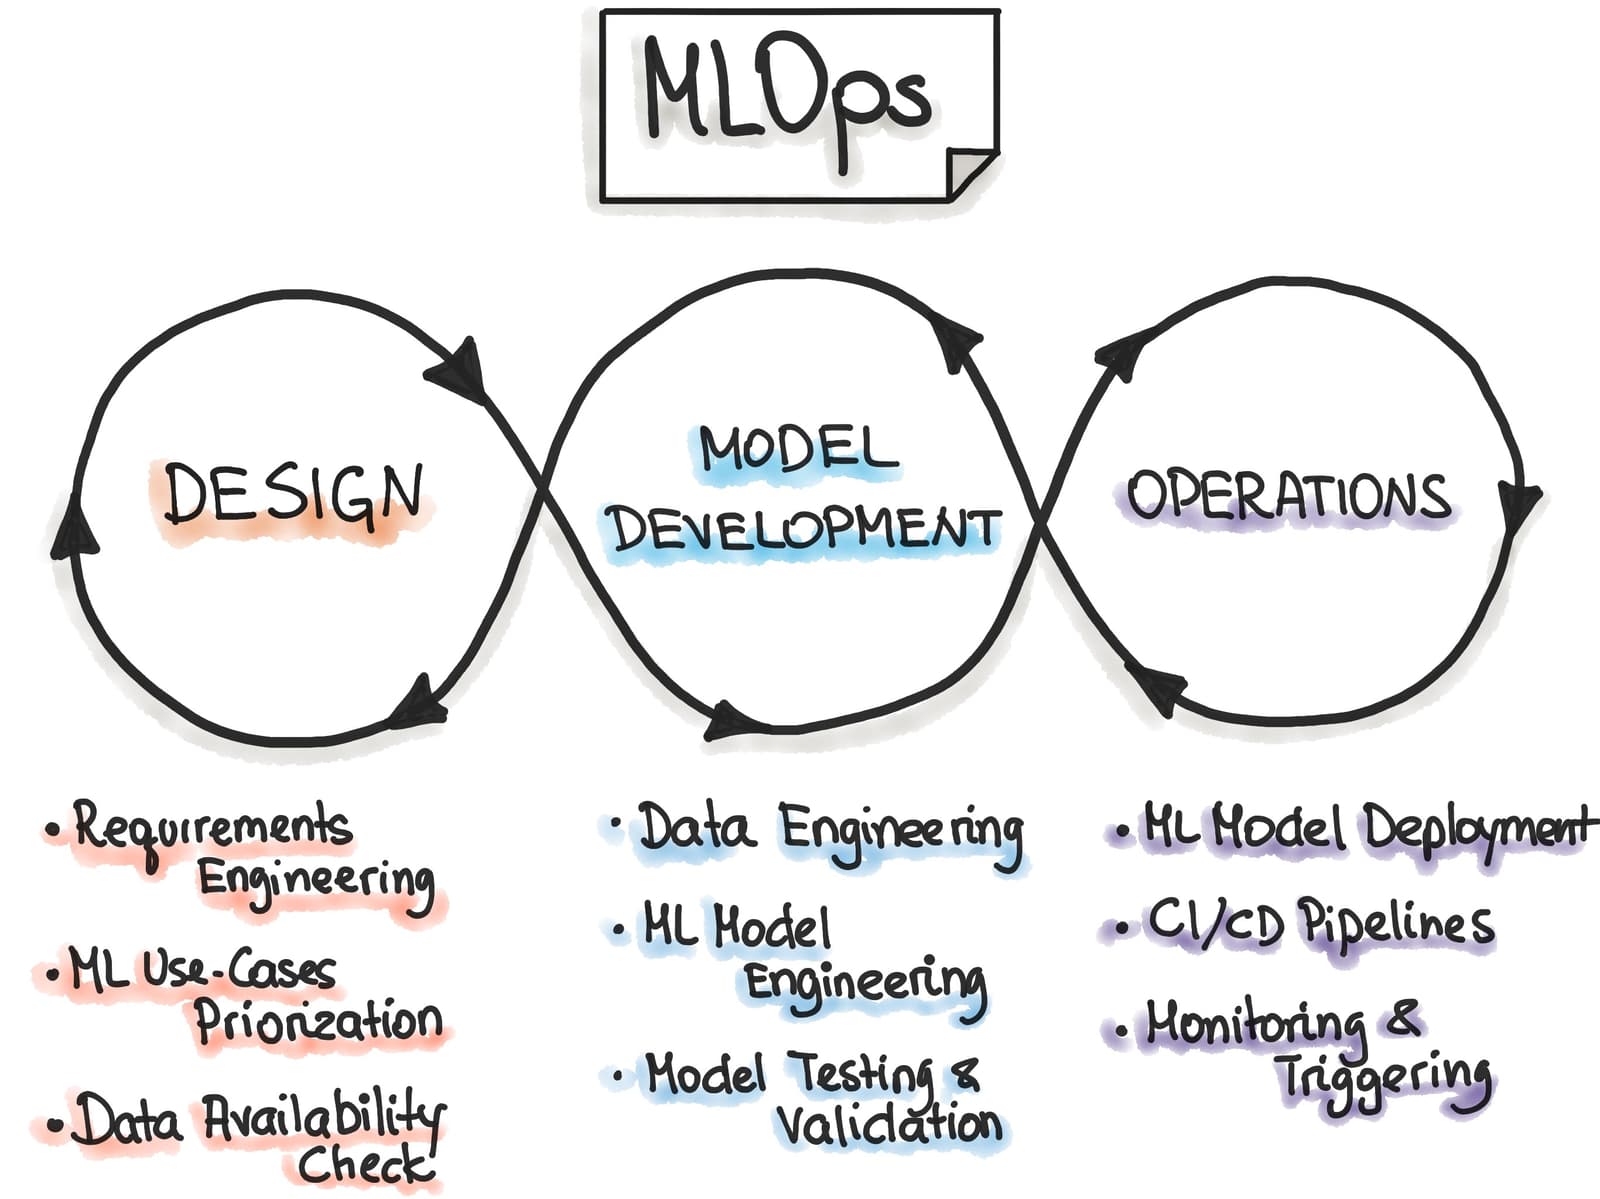
How would you design a reproducible ML training pipeline?
Tests if you can version ML's three moving parts: code, data, and environment. Good answers cover Git for code, DVC or lakehouse versioning for data, and Docker plus locked dependencies for environments.

What trade-offs decide managed ML platforms versus open-source Kubernetes?
Weigh total cost plus hidden engineering headcount, lock-in vs flexibility, and audit feature gaps.
What is a feature store and how does it prevent training-serving skew?
This tests training-serving consistency via centralized feature management. Covers offline batch storage, online serving, shared transformations, and alternatives like ad-hoc ETL. A red flag is calling it just a database and ignoring point-in-time correctness.
What are the essential components of an end-to-end ML platform?
Tests mapping the ML lifecycle to infrastructure. A strong answer walks through six stages: data ingestion, feature store, training pipeline, model registry, deployment/serving, and monitoring with feedback loops.
How would you architect dynamic training resource provisioning?
Routes jobs to right-sized instances, provisions managed jobs using spot, and auto-tears down on completion.

Design concept drift detection with automated retraining safeguards
Baseline monitors raise CloudWatch alarms; EventBridge triggers retraining with cooldowns; model registry gates promotion.
How do you programmatically promote a retrained model to production?
Compare on held-out data using significant metric uplift, schema, latency, and drift checks before shadow release.
How would you implement automated data validation before training?
Enforce schema contracts, halt training on failure, quarantine bad batches, and alert owners.
What triggers automatic full retraining in an ML pipeline?
A strong answer lists four triggers: fresh data, code changes, model drift, and scheduled cadence.

How do you monitor thousands of per-customer models as a fleet?
Tests fleet-level statistical aggregation versus per-instance alerting. Strong answers propose tiered telemetry, cohort baselining for drift, and hierarchical alerting to prevent fatigue.
Design an automated system to diagnose model performance drop root causes
Tests causal attribution between pipeline bugs and drift. Strong answers sequence schema/null audits, feature drift via PSI/KS, then concept drift via holdout decay. Red flag: skipping pipeline checks to retrain immediately.
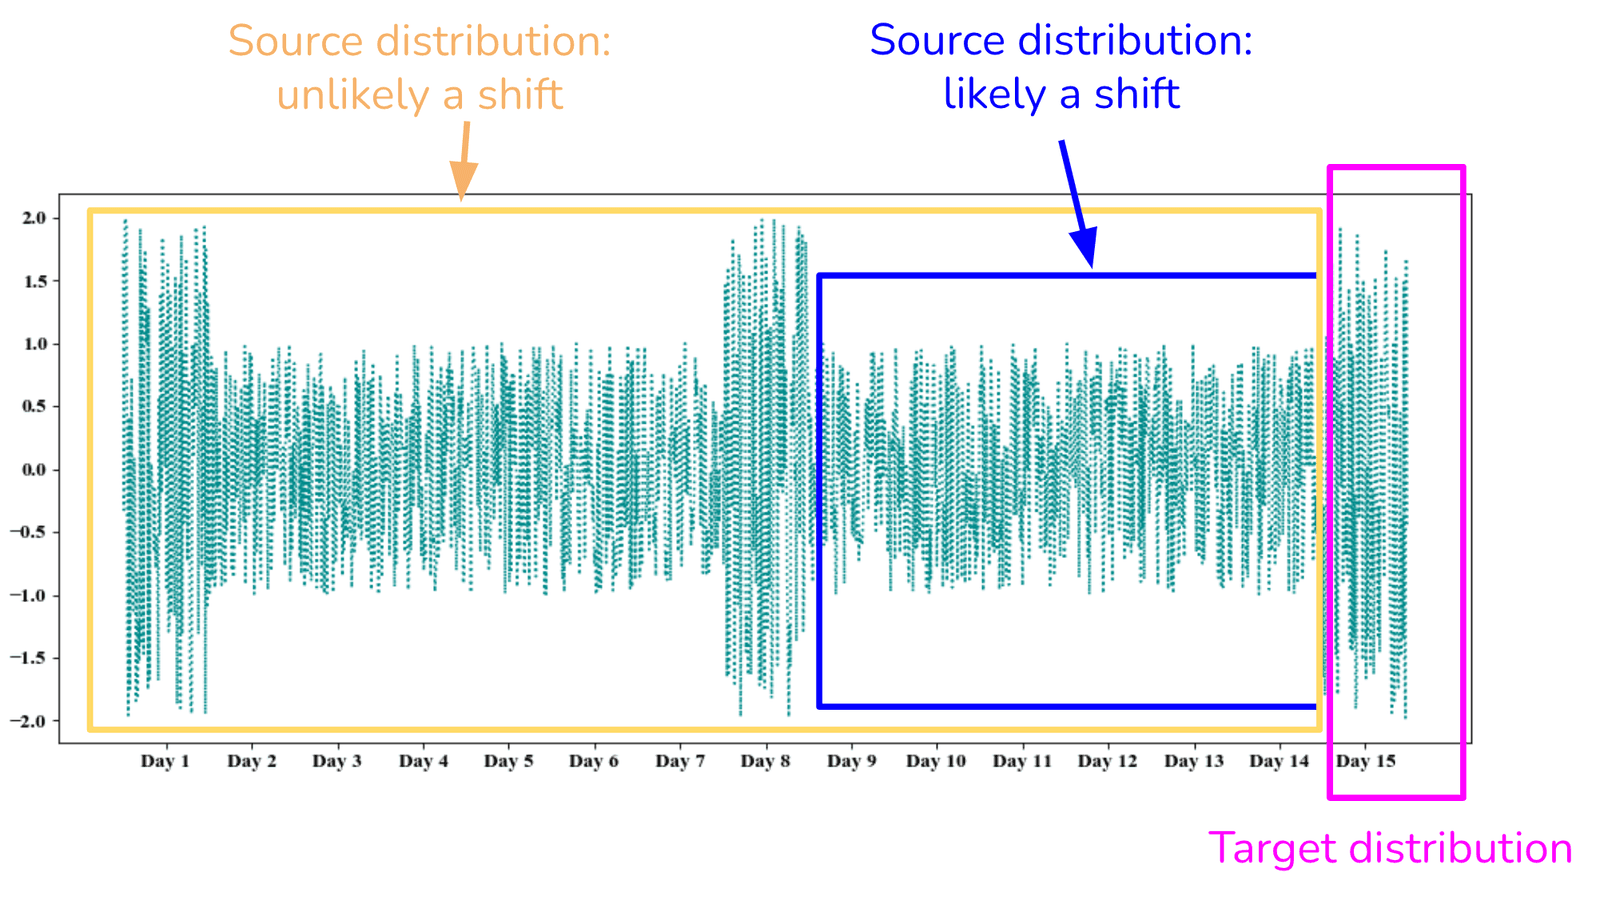
Model output distribution shifts. What are root causes and next steps?
This tests covariate vs label shift vs concept drift when outputs shift. A strong answer checks features before labels, then feedback loops or staleness. A red flag is generic drift without separating P(X), P(Y), and P(Y|X).
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles