Intermediate concepts in Computer Vision, page 4
Sliding Windows: Scanning Images for Objects
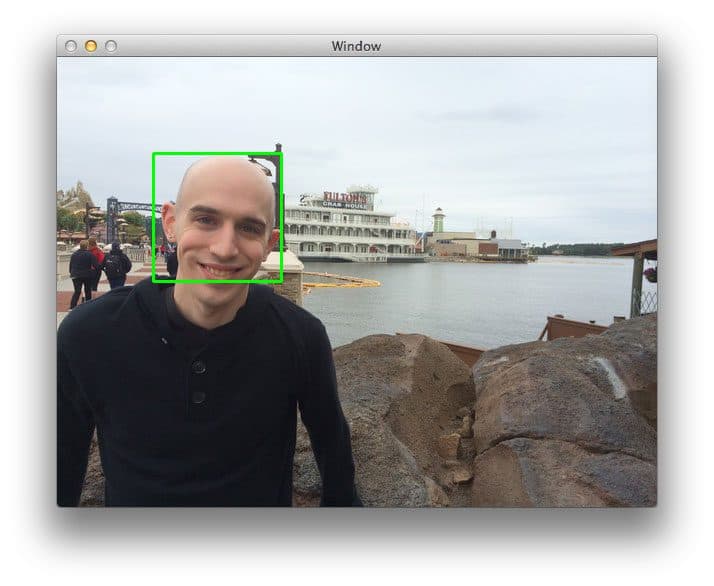
A sliding window scans an image with a fixed-size box to find objects. At each location, a classifier checks the window's contents. Combined with an image pyramid, it can detect objects at various scales, localizing exactly where they are.
Anchor Boxes: Pre-defined Guesses for Object Detection
Anchor boxes are predefined 'template' boxes of various sizes and shapes. Object detection models use them as a starting point, predicting how to shift and scale these templates to fit actual objects, making detection faster.
Watershed Algorithm: Segmenting by Topography
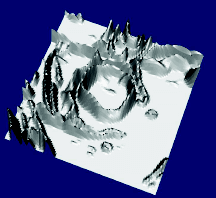
The watershed algorithm treats an image as a landscape where pixel brightness is height. It finds the 'ridges' separating distinct 'valleys,' effectively segmenting touching objects. Its main footgun is extreme sensitivity to noise, causing over-segmentation.
U-Net: Encoder-Decoder for Image Segmentation
U-Net segments images by first compressing them to capture context, then expanding to localize features precisely. It excels in biomedical imaging where annotated data is scarce.
Self-Attention: How Models Weigh Word Importance
Self-attention lets a model weigh the importance of all words in a sequence simultaneously, asking "which other words are most relevant?" It's the core of Transformers, enabling parallel processing for tasks like translation, unlike sequential RNNs.
Autoregressive Models: Generating Images One 'Word' at a Time
Autoregressive models generate images sequentially, like writing a sentence word by word. Each new pixel or patch depends on what came before. This creates high-fidelity images but is much slower than one-shot models, a key trade-off in generative AI.
Semantic Scene Classification: Understanding Context, Not Just Objects
Scene classification tells you the context of an image ("this is a forest"), not just the objects in it ("there's a tree"). It's used by self-driving cars to identify a highway vs. a residential street and by apps to organize photos.

3D Object Detection: Seeing in Depth, Not Just Pixels
3D object detection adds depth to a 2D flat view, understanding an object's true size, distance, and orientation. It's vital for autonomous cars and robotics that need spatial awareness.
Meta-Learning: Learning How to Learn
Meta-learning is 'learning to learn.' Instead of training on data, it learns from the performance of other models, using metadata from experiments to improve the learning process itself. This helps algorithms become more flexible and solve new problems faster.

Neural Network Pruning: Making Models Smaller and Faster
Neural network pruning makes models smaller and faster by removing unimportant connections, like trimming a bonsai tree. It's essential for deploying large models on devices with limited memory, like phones.
Image Convolution: A Sliding Feature Detector
An image convolution is a sliding filter that scans an image to detect features like edges or textures. It's the core building block of modern computer vision, used in image classification and object detection.

Non-Maximum Suppression: One Box Per Object
Non-Maximum Suppression (NMS) ensures each detected object gets just one bounding box. It sorts all proposed boxes by confidence, keeps the best one, and discards others that overlap it too much.
COCO: The Messy Real-World Vision Benchmark
COCO is the standard benchmark for detecting overlapping objects in cluttered scenes. Use it to test object detectors and segmentation. Strong scores here do not mean your model works on specialized domains like medical or satellite imagery.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles