Concepts in Computer Vision, page 5

Kalman Filters: Predicting Through Noise
A Kalman filter predicts an object's next position, then corrects that prediction with noisy real-world measurements. It's used in video tracking to smooth an object's path between frames or in robotics to fuse imperfect sensor data.
Mean Shift: A Mode-Seeking Algorithm
Mean shift is a technique for finding the peaks, or modes, of a density function. It's a non-parametric method used for cluster analysis in domains like computer vision and image processing to locate the densest areas in a feature space.
Two-Stream ConvNets: Seeing What vs. How It Moves
Two-Stream ConvNets split video analysis into two paths: a spatial stream sees *what* is in a frame, and a temporal stream sees *how* it moves via optical flow. This is used for action recognition, like telling 'typing' from 'waving'.
Correlation Filters: Fast and Robust Object Tracking
Correlation filters track objects by learning a template that gives a peak response at the object's location. This makes them extremely fast for real-time visual tracking. The footgun: basic versions fail when the object changes scale or is occluded.
Particle Filters for Object Tracking
A particle filter tracks an object by maintaining a cloud of possible states ('particles'), not one best guess. It's used to follow objects through clutter and occlusion, like tracking a face in a crowd.
DeepSORT: Adding Visual Memory to Object Tracking
DeepSORT adds a 'visual memory' to object tracking, using a deep learning model to re-identify objects after they're hidden. It's used in surveillance and autonomous driving to maintain consistent IDs across frames.
Temporal Segment Networks: Seeing the Whole Video Story
Temporal Segment Networks (TSN) understand video actions by sampling sparse snippets across the entire timeline. This gives a model long-range context to distinguish complex actions.

Attention in Vision: Teaching Models Where to Look
Attention teaches a model where to look in an image by dynamically weighting important pixels or features. It's used in object detection to focus on relevant regions. The footgun is assuming it's free; attention adds computational cost and complexity.

Generative Adversarial Networks (GANs): A Forger and a Detective
A GAN pits two neural networks against each other: a Generator that creates fakes and a Discriminator that spots them. This adversarial game forces the Generator to produce highly realistic outputs, like photorealistic faces. The main footgun is mode collapse.
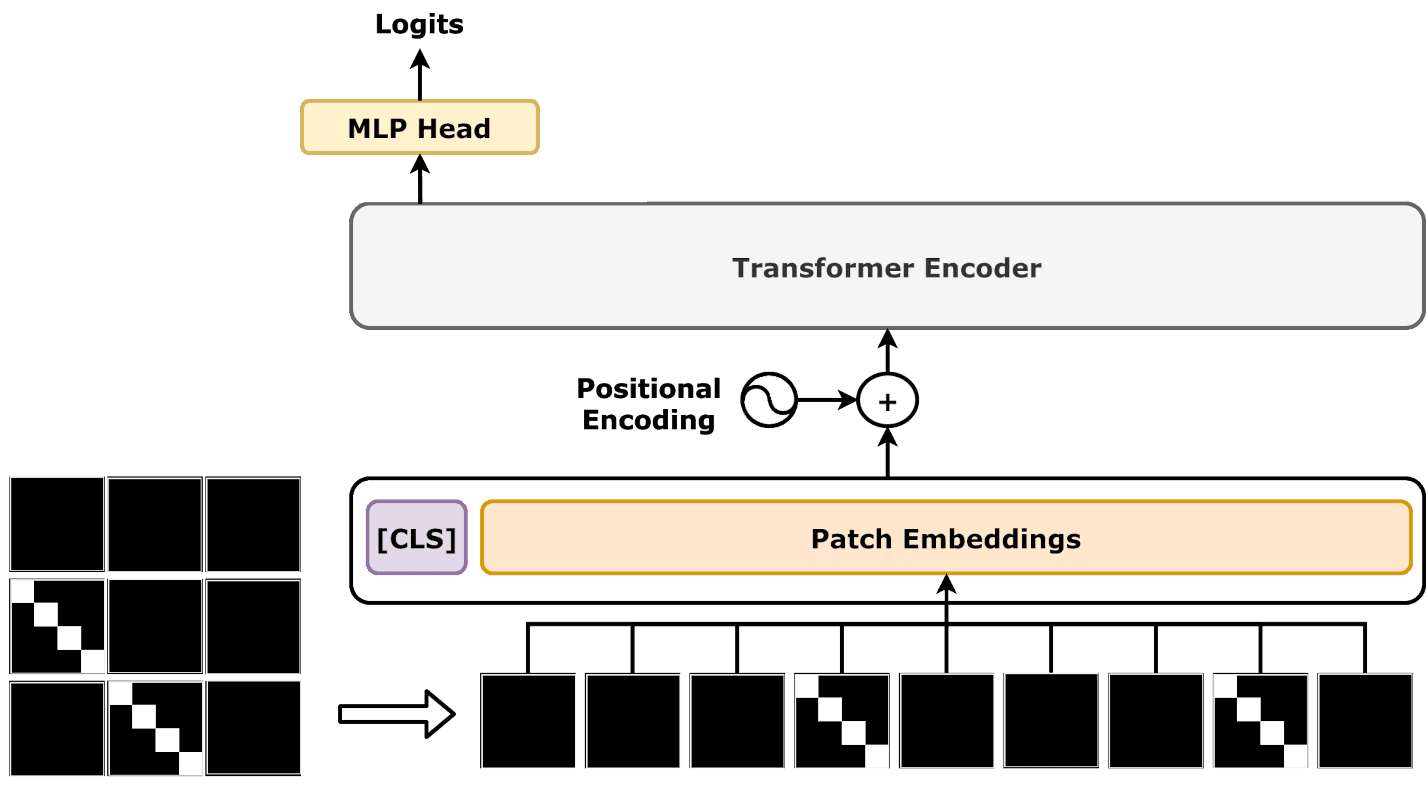
Patch Embedding: Turning Images into Words for Transformers
Patch embedding chops an image into a grid of squares, turning each into a vector. This lets sequence-based models like Transformers "read" images. It's the core of Vision Transformers (ViTs), but it discards the fine-grained detail inside each patch.

Multi-Head Attention: Seeing Data From Multiple Angles
Multi-head attention lets a model analyze a sequence from multiple perspectives at once. It runs several "attention heads" in parallel, each focusing on different relationships, like syntax vs. semantics.
DETR: Object Detection as Direct Set Prediction
DETR reframes object detection from a filtering task to direct set prediction. It uses a Transformer to output a fixed set of object predictions in one pass, eliminating complex post-processing.
Swin Transformer: Efficient Vision with Shifted Windows
Swin Transformer makes Vision Transformers practical by processing images in local "windows" instead of all at once. It's a powerful backbone for object detection and segmentation where scale varies.
Cross-Attention: How Models Fuse Text and Images
Cross-attention lets a model fuse different data streams, like asking 'what in this image corresponds to this word?'. It's key for text-to-image generation, where text queries attend to image features. The footgun is confusing it with self-attention.
MLP-Mixer: Vision Without Convolutions or Attention
MLP-Mixer shows that simple MLPs can achieve strong vision results, challenging the need for convolutions or attention. It works by alternating between mixing features within image patches and mixing information across patches.
NeRF: Turning 2D Photos into a Walkable 3D Scene
A Neural Radiance Field (NeRF) learns to be a 'ray-tracing oracle' for a scene, predicting color and density from any angle. It's used to create walkable 3D experiences from 2D photos. The footgun: NeRFs can't invent details not in the source images.
Diffusion Models: Generating by Reversing Noise
Diffusion models generate data by learning to reverse a process of adding noise. They power state-of-the-art image generation (DALL-E 2, Stable Diffusion). The main footgun is that their iterative sampling process is slow and computationally expensive.
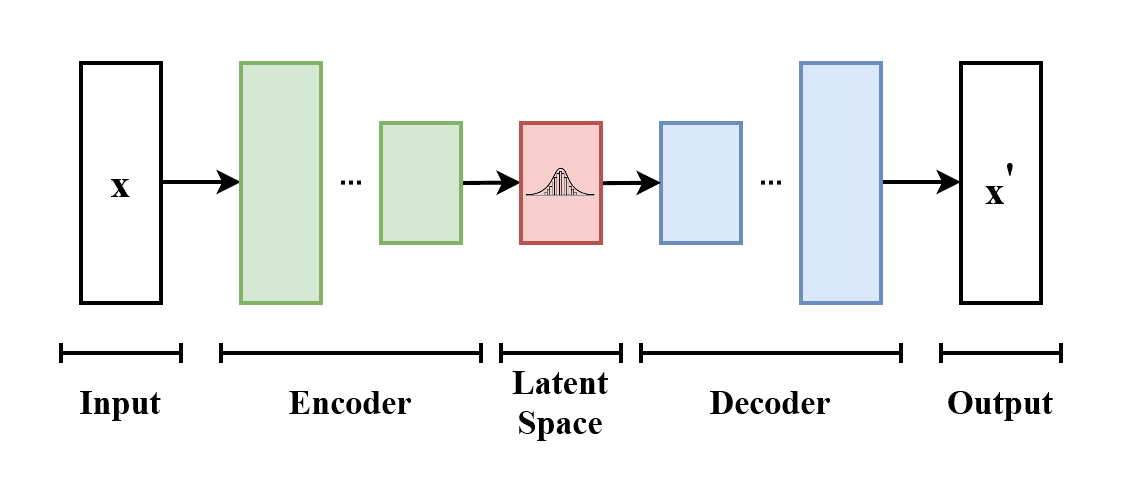
Variational Autoencoders: Learning to Generate Data
A VAE learns to create new data by compressing examples into a "latent space" of core features and then decoding from it. It's used for generative art and data augmentation, but its outputs can be blurrier than those from other models like GANs.
Latent Space: A Map Where Distance is Similarity
A latent space is a map of concepts where distance equals similarity. Similar items are clustered together, which powers image generation and recommendation engines. The footgun is that the map's dimensions are abstract, not human-interpretable features.
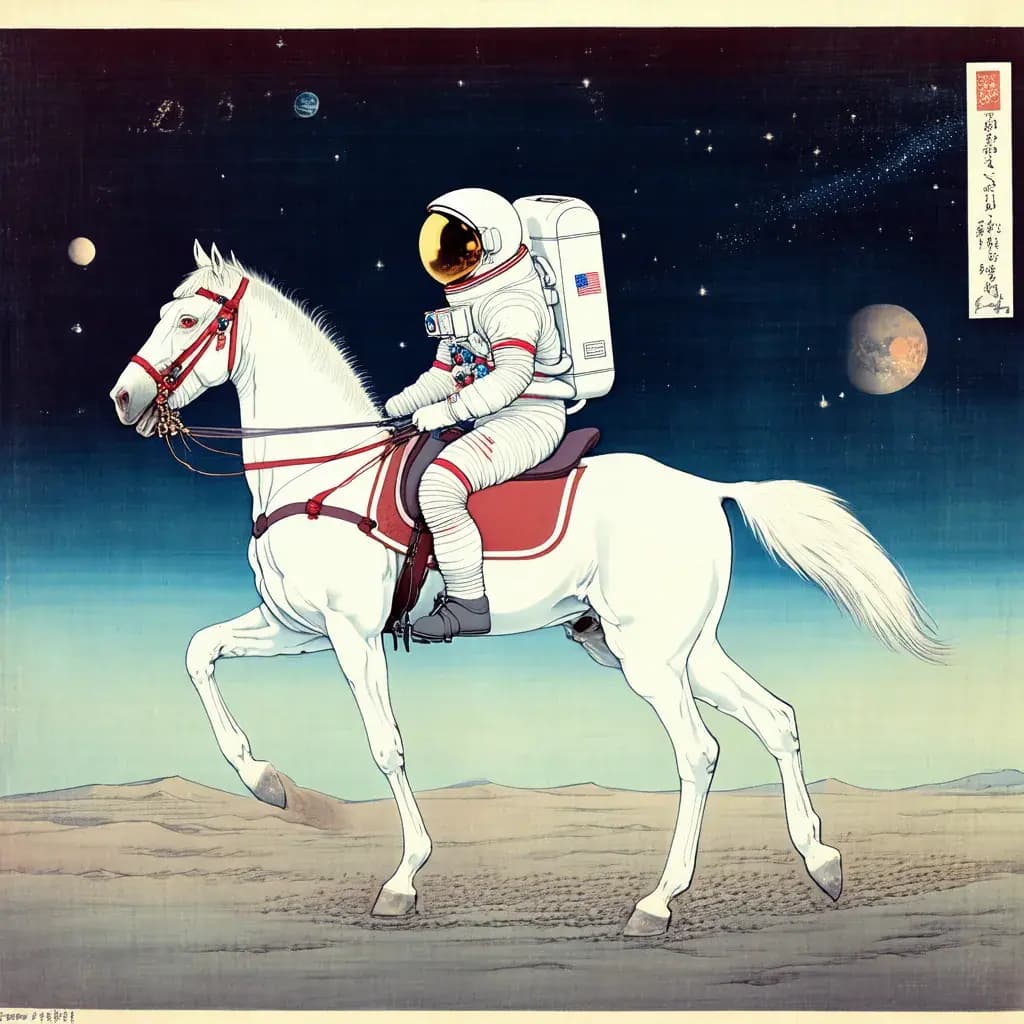
Text-to-Image Generation: From Words to Pixels
Text-to-image models act like a digital artist, translating language into visuals. They're used to create art, marketing materials, and prototype designs. The main footgun is prompt ambiguity, which can lead to bizarre or nonsensical images.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles