Concepts in MLOps & Infrastructure, page 3
Parameter Servers for Distributed ML Training
A parameter server splits the work in distributed training: central servers hold the model's parameters, while worker nodes pull parameters, compute gradients on data subsets, and push updates back. This enables training models too large for one machine.
Horovod: Scale ML Training Across Many GPUs
Horovod scales a single-GPU training script to hundreds of GPUs with minimal code changes, slashing training time. It's used when models are too big for one machine.
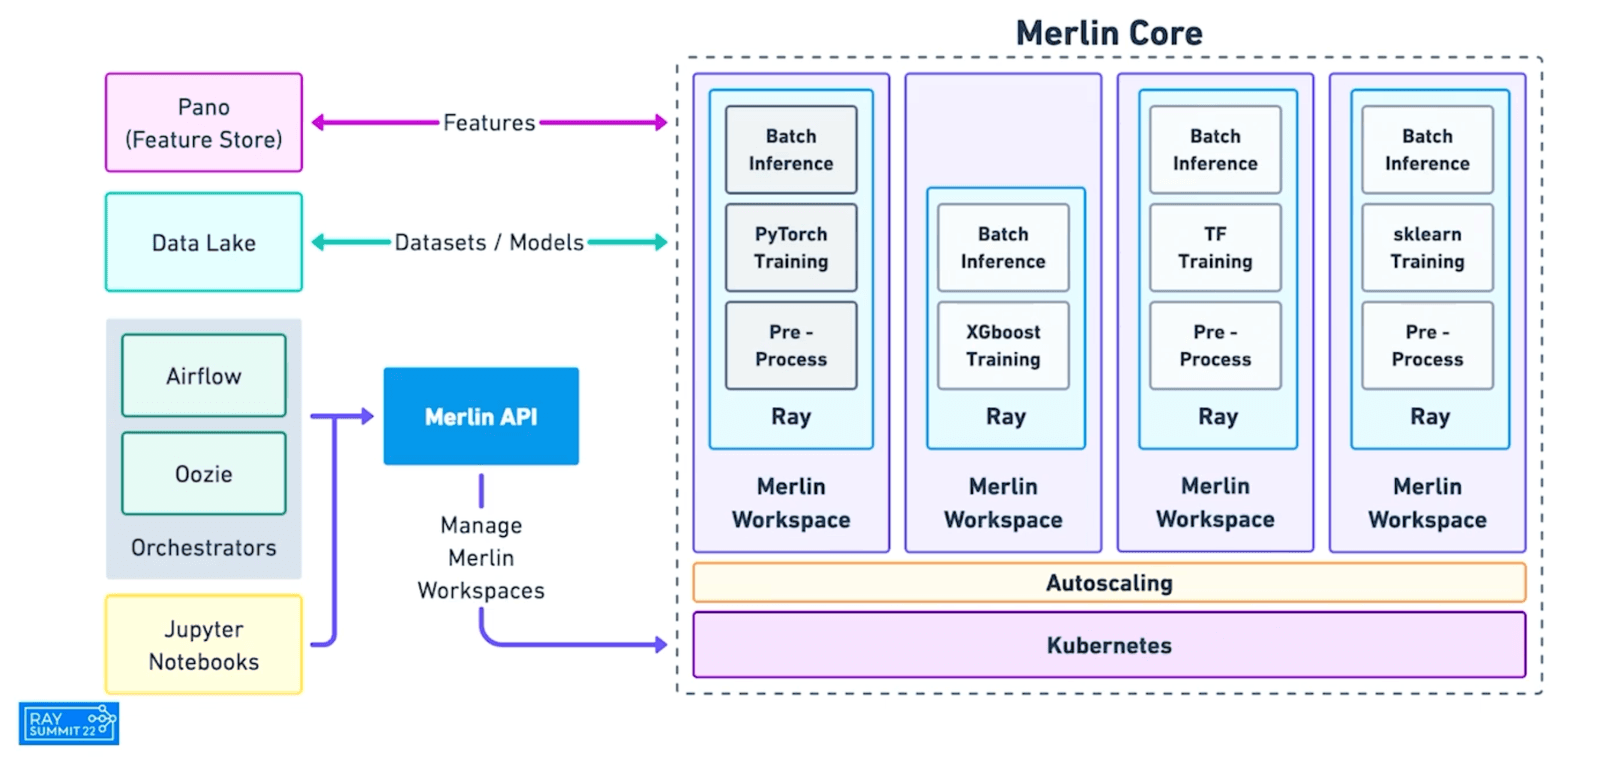
Ray AI Runtime (AIR): A Unified ML Toolkit
Ray AIR is a unified toolbox for the ML lifecycle, bundling libraries for data, training, tuning, and serving. It's for scaling end-to-end ML workflows on one distributed platform.
Kubeflow: MLOps on Kubernetes
Kubeflow brings the declarative, container-based world of Kubernetes to the entire ML lifecycle. It provides tools for building portable and scalable ML workflows, from development to production serving.
Slurm: The Job Scheduler for Supercomputers
Slurm is the reservation system for a shared supercomputer, queuing up jobs and assigning them to available nodes. It's the backbone of high-performance computing clusters in science and ML.
Elastic Training: Training Models on Unreliable Hardware
Elastic Training lets ML training jobs survive worker nodes being added or removed mid-run. It's like a construction crew that adapts to a changing number of workers, making it ideal for training large models on cheap but unreliable cloud spot instances.
All-Reduce: Synchronizing Parallel Workers
All-Reduce lets parallel workers agree on a global result. Each worker contributes data, an operation (like sum) runs on all data, and every worker gets the final answer. It's the core of distributed ML training, used to average gradients across GPUs.
Microsoft DeepSpeed: Training Massive Models Across GPUs
DeepSpeed trains models too big for one GPU by partitioning model states across many devices. It's essential for training foundation models like BLOOM, but its complexity is overkill for smaller models and misconfiguration can harm performance.
Git-Based CI Triggers: Automating on Events
Think of Git events like push or pull_request as the "play" button for your automation. This is how CI systems automatically run tests on new code. The footgun is using broad triggers, like push on all branches, which causes costly and redundant runs.
Unit Testing ML: Beyond Standard Code Checks
Unit testing for ML isn't just about code logic; it's about checking data, models, and infrastructure in isolation. Use it to validate data transformers, check model prediction shapes, or confirm a function handles nulls.

Shadow Deployment: Test Models on Real Traffic
Shadow deployment runs a new model on real traffic without serving its predictions, letting you catch data drift before users are affected. It is the safest production validation method, but teams often forget to monitor its latency and resource costs.
Automating MLOps with GitHub Actions
Treat your ML workflow like any other CI/CD pipeline. GitHub Actions automates MLOps tasks—like training, testing, and deployment—triggered by events in your repo. Use it to run validation on PRs or deploy models on merge.
GitOps for MLOps: Your ML System as Code
GitOps for MLOps treats your entire machine learning pipeline—data, code, and models—as declarative configuration in Git. It automates ML workflows, ensuring reproducibility by making every change a reviewable commit.

Online Inference: Predictions on Demand
Online inference is a vending machine for predictions: you make one request and get one result back immediately. It powers real-time features like fraud detection or content moderation.
Batch Inference: High Throughput, Not High Speed
Think of batch inference as processing a day's mail at once, not as each letter arrives. It trades immediate answers for cost-effective, high-volume predictions, like generating daily product recommendations. The footgun is using it for real-time needs.
Model Server: The MLOps Deployment Bridge
A model server bridges ML training and production, operationalizing models within your release cycle. Use it when models must become first-class CI/CD citizens. The footgun is treating deployment as a one-time handoff rather than repeatable infrastructure.
Serverless Inference: Run ML Models Without Managing Servers
Serverless inference treats ML prediction like a function call, abstracting away servers. You pay for compute time per prediction, not for idle infrastructure.
Streaming Inference: Real-Time Model Predictions
Streaming inference makes predictions on data in-flight, not from a database. It's for real-time recommendations or fraud detection where millisecond decisions are critical. The footgun is assuming a single server can handle the load; you must build for scale.
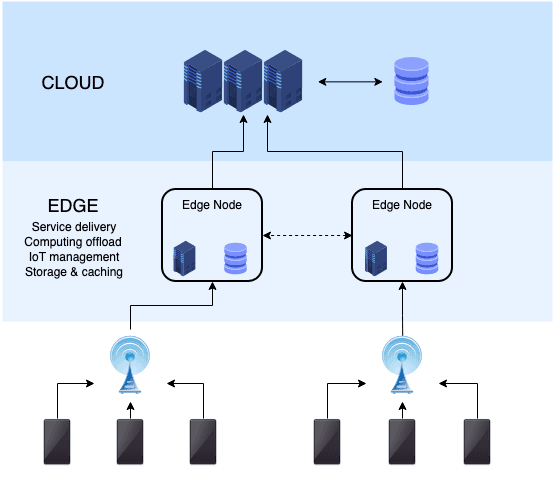
Edge AI: Running Models Where the Data Is
Edge AI runs machine learning models directly on devices, not in a distant cloud. This enables real-time, offline applications like smart cameras or voice assistants. The footgun is underestimating device hardware limits; models must be small and efficient.
Multi-Armed Bandits for Model Selection
Treat your candidate models like slot machines. A Multi-Armed Bandit (MAB) algorithm automatically allocates traffic to find the best one, balancing exploration of new options with exploiting the current winner.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles