Advanced everything in MLOps & Infrastructure, page 4
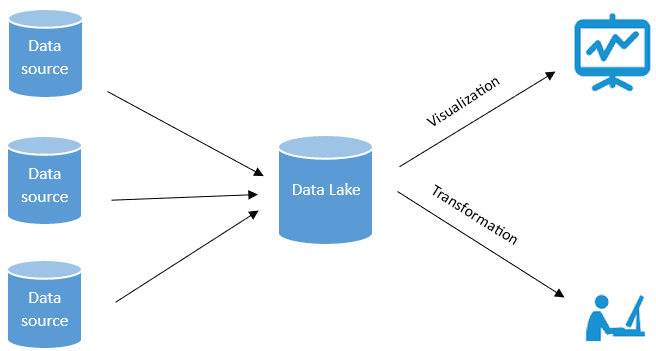
Data Lake: A Single Repository for Raw Data
A data lake is a central repository that stores vast amounts of raw data in its native format. It acts as a single source for analytics and machine learning, but without proper management it can become a useless "data swamp".
ML Metadata: The Logging Layer for ML Pipelines
ML Metadata is the logging layer for your ML pipeline, tracking every dataset, hyperparameter, and model version. It's crucial for debugging failed runs by tracing a model back to its exact data.
Data Drift vs. Concept Drift: When Models Go Stale
Your ML model's accuracy decays when the real world no longer matches its training data. This is drift. It happens when user behavior changes (concept drift) or input data distributions shift (data drift).
Continuous Training: CI/CD for ML Models
Continuous Training (CT) is a CI/CD pipeline for models, not code. It automatically retrains and redeploys models to fight performance decay from changing data, a problem known as 'data drift'. The footgun is deploying a new model without validating it first.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles