Easy everything in Product Management, page 3

How would you implement a simple feature flag system?
Tests runtime config separation and distributed hygiene. Outline: control service, datastore, API, SDK, and update mechanism; local evaluation with cached state; short-lived flags. Red flag: static config files requiring redeployment are not feature flags.

What differentiates leading and lagging indicators for subscriptions?
Leading indicators forecast; lagging indicators confirm. Subscriptions: activation rate leads, MRR lags.

Why is extrapolating 5% weekly growth naive for annual forecasting?
This tests knowledge of extrapolation limits. A strong answer cites market saturation, seasonality, and channel exhaustion as invalidating factors, and notes that compounding 5% over 52 weeks magnifies error.

What data and approach for a simple 30-day DAU forecast?
Tests forecasting from sessionized logs without overengineering. Cite timestamped events, a 30 min session rule, and a regression baseline with day-of-week, recent totals, scored with MAE. Red flag: deep learning before a baseline or ignoring privacy hashing.
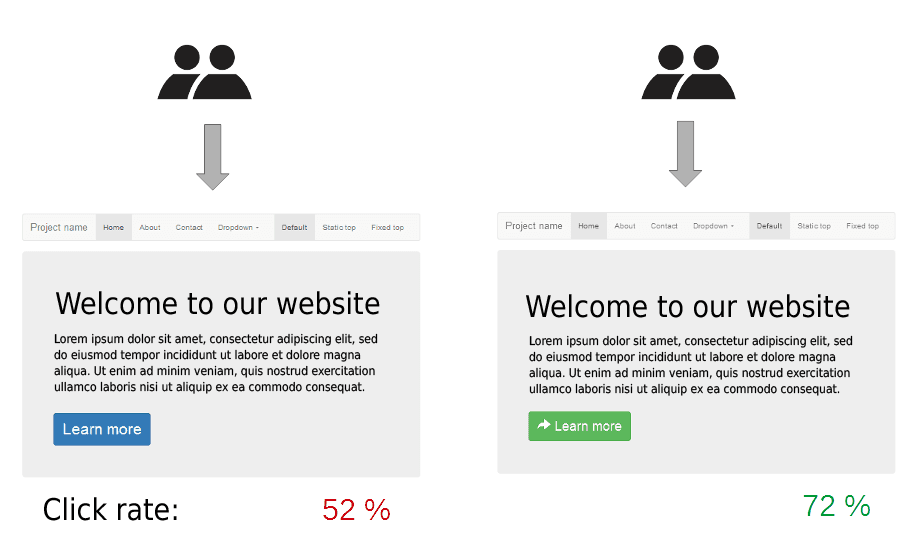
Implement a 10% onboarding tutorial feature flag and track success
Tests lightweight experiment design and metric selection beyond vanity numbers. Strong answers cover user-ID bucketing, conversion tracking, and guardrail metrics like drop-off. Red flag: manual toggles or click-through without downstream outcomes.
How would you instrument a key activation milestone event?
Tests schema design beyond a bare event name. A strong answer includes the event key, user ID, timestamp, and properties like project_id and is_first_project. Red flag: omitting the user ID or sending only a human-readable label without structured context.
Model a 3-month 20% promo discount and apply it at billing
This tests separating coupon rules from per-user redemptions. Good answers use a coupons table for the 20%/3-month rule, a redemptions table for usage, and apply the discount to the first three invoices. A red flag is hard-coding the discount on the user row.

What schema changes are needed to add a Pro subscription tier?
This tests normalization of billing data versus hardcoding tiers. Add a plans table with integer cents pricing, link subscriptions via plan_id, and leave users untouched. Red flag: adding a tier string column to users or storing prices in subscriptions.

Describe the data model and backend logic for a daily login bonus.
This tests streak state machines and calendar edge cases. A strong answer stores last_login_utc and streak_count, uses UTC day buckets, resolves timezones per user tz, and needs no leap-year logic.
Describe the end-to-end data flow for tracking a 'Share' button click
Payload carries event type, user ID, timestamp, device, content; client batches with retry; backend validates and lands in a partitioned store.

How do you determine if a user is 'new' for a setup guide?
This tests whether you separate account age from user state for onboarding. Good answers compare created_at (brittle) with a persistent flag (idempotent) and consider milestones. A red flag is using a timestamp as a permanent new proxy without managing reruns.
How would you instrument a 4-step onboarding wizard?
Track Step Started and Step Completed with step_index and flow_variant; tie via distinct_id.
What is a p-value in A/B tests and what does threshold mean?
P-value is the chance of this or more extreme result if the null is true; the 5% threshold is the accepted false-positive rate.

How do you set up a button color A/B test?
Tests whether you can define a valid experiment, not just a color change. A strong answer covers hypothesis, randomization, primary metric, sample size, and significance threshold.

What framework decides between low-effort/low-impact and high-effort/high-impact experiments?
This tests structured experiment sequencing beyond gut instinct. A strong answer picks ICE, RICE, or PIE; scores both experiments by impact, confidence, and effort or reach; then weighs opportunity cost and bandwidth.

Which three data sources would you analyze to improve activation?
This tests whether you ground hypotheses in diverse evidence before experimenting. A strong answer names qualitative feedback, funnel metrics, and behavioral analytics as distinct inputs.
How would you design a near real-time social proof notification system?
This tests low-latency event pipeline design with bounded load. A strong answer uses a fire-and-forget beacon, stream processor, and cache with TTL; it favors approximate counts and windowed aggregation.
How would you implement a timezone-safe, tamper-proof offer countdown?
Tests distrust of the client and server-side UTC enforcement. Outline: server owns canonical end time; client syncs clock offset to render remaining time; checkout re-validates expiry. Red flag: using local Date.now or localStorage.

What is a conversion funnel? Instrument a three-step onboarding funnel with events.
This tests translating business funnels into concrete event instrumentation. A strong answer outlines three ordered steps, names exact events like user_signed_up and project_created, and notes unique-user counting.
How would you track a 'Sign Up' button click end-to-end?
It tests your ability to instrument a custom event and validate the pipeline. Attach a gtag listener to the button, fire a sign_up_click event, then confirm the hit in GA4 DebugView or real-time reports.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles